How to Check VCF 9 Hardware Compatibility: Servers, CPUs, NICs and vSAN ESA Devices

The four checks that decide VCF 9 hardware support: BCG listings, CPU KB 318697, ESX 9 deprecated devices and vSAN ESA certification with a fresh HCL DB.

Short answer: VCF 9 hardware support is decided in four places. The Broadcom Compatibility Guide (BCG) must list the server model and every I/O device for ESX 9.x. The CPU must not be discontinued in KB 318697. No device may be End of Life in KB 391170. For vSAN ESA, the NVMe devices must be ESA-certified, and the vSAN HCL database in vCenter, SDDC Manager and the VCF Installer must be less than 90 days old. This page walks through the four checks in the order an upgrade fails them.

The four checks at a glance

CheckWhereWhat blocks VCF 9Details on vDan
Server model and I/O devicesBroadcom Compatibility Guide: Systems/Servers and I/O Devices, release ESX 9.0 or 9.1The model or device has no ESX 9.x listingthis page
CPU generationBroadcom KB 318697 (formerly 82794)The CPU is “Discontinued” for 9.xKB 82794 / 318697 CPU tables
Deprecated drivers and devicesBroadcom KB 391170The device is “End of Life”: ESX 9.0 no longer claims itESX 9.0 deprecated devices (searchable)
vSAN ESA devices and the HCL DBBCG vSAN ESA view, plus the local all.json in vCenter, SDDC Manager and the VCF InstallerNon-certified NVMe, or an HCL DB older than 90 daysvSAN HCL DB offline update · ESA HCL lab workaround

Collect what the host actually has

The BCG searches by model, by CPU series and, for I/O devices, by the four PCI IDs (VID, DID, SVID, SSID). Get them from the ESXi shell:

esxcli hardware platform get          # vendor and server model
esxcli hardware cpu global get        # CPU packages, cores
esxcli hardware cpu list | head -20   # Family / Model / Stepping (decimal)
vmkchdev -l | grep -E "vmnic|vmhba"   # VID:DID SVID:SSID per NIC and storage adapter
esxcli network nic list               # driver and link per vmnic
esxcli network nic get -n vmnic0      # driver and firmware version
esxcli storage core adapter list      # storage controllers and drivers
esxcli storage core device list | grep -E "Display Name|Vendor|Model|Revision"

vmkchdev -l prints the IDs as vid:did svid:ssid. Enter all four in the BCG I/O Devices search. The VID:DID pair alone matches a whole chip family, while the SVID:SSID pair identifies the vendor’s specific card, and that is what the listing certifies.

1. Server model: the BCG Systems listing

Search the BCG for the exact server model and pick release ESX 9.0 or 9.1. Two details decide most cases:

  • The listing names CPU series. A model listed for ESX 9.x with newer CPUs doesn’t cover the same chassis with an older CPU generation.
  • The OEM must keep the model listed. KB 318697 states that even a deprecated CPU stays supported only while the server OEM keeps the model in the BCG.

On Cisco UCS, check the UCS firmware bundle against the ESX release as well. The BCG entry for a UCS server lists the supported firmware, and the matching nenic/nfnic driver versions come from Cisco’s UCS hardware and software compatibility tool.

2. CPU: deprecated or discontinued in 9.x

KB 318697 has two tables. “Discontinued” CPUs block ESX 9.x installation and upgrade. “Deprecated” CPUs are fully supported in 9.x but will be blocked in the next major release. Broadwell, Kaby Lake and Skylake-W are discontinued. Skylake-SP and Skylake-D got a 9.x extension in KB 428874. Cascade Lake, EPYC 7001/7002, Coffee Lake and Denverton are deprecated. The exact rows, CPUID values and how to read esxcli hardware cpu list are in the CPU support page and the Skylake page.

3. NICs, HBAs and drivers: ESX 9 deprecated devices

KB 391170 lists 487 devices as Restricted (they work, but get no new features and only best-effort fixes) and 1,137 as End of Life. ESX 9.0 doesn’t claim End of Life devices at all, so a host can upgrade cleanly and come up without its storage controller or uplinks. Search your VID:DID in the ESX 9.0 deprecated devices table before the upgrade, not after.

The VCF Installer has a 10 GbE minimum NIC speed check. In a lab you can work around it (see the minimal VCF 9.0 lab). In production, a NIC that fails it isn’t a valid design.

4. vSAN ESA: certified NVMe and a fresh HCL database

vSAN ESA has its own BCG view. Each NVMe device must be ESA-certified for the release, or the server must be an ESA ReadyNode. Broadcom KB 326717 lists the component changes allowed in an ESA ReadyNode (CPU, storage device, memory, NIC, boot device), as long as the replacement is itself listed.

The local copy of the HCL database is a separate check, and it fails more often than the hardware does. vCenter, SDDC Manager and the VCF Installer each keep their own all.json. The Installer and SDDC Manager treat a copy older than 90 days as an error. The error text is the same as for uncertified disks (“No vSAN ESA certified disks found on the ESXi Host”), so check the database date first. The offline update for all three places is in vSAN HCL DB offline update.

Let vSphere Lifecycle Manager check the cluster

On a vSAN cluster managed by a vLCM image, the cluster’s hardware compatibility check compares the vSAN storage controllers and disks, including firmware, against the vSAN HCL. Firmware is validated only when the image includes a firmware add-on from the vendor’s Hardware Support Manager. If “Prevent remediation if hardware compatibility issues are found” is enabled, a finding blocks remediation (KB 412988). PowerCLI exposes the same check:

Get-LcmHardwareCompatibility -Cluster (Get-Cluster 'wld01-cl01')

This covers only what vSAN uses. It doesn’t replace checks 1–3 for the server, CPU and NICs.

Labs: what you can and cannot work around

BlockerSupported fixLab-only option
HCL DB older than 90 daysUpload a fresh all.json (KB 412606, KB 315556)Not needed
NVMe not ESA-certifiedCertified devices, vSAN OSA or external storagevSAN ESA hardware mock VIB (details)
NIC slower than 10 GbEFaster NICsInstaller validation bypass (minimal lab)
Discontinued CPUNew hardware, or stay on 8.x until its End of General SupportRPQ/TQ for software-only support via the account team (KB 428874)

Sources

vCenter and VCF Certificate Troubleshooting: Which Tool or Fix You Need

Which vCenter or VCF certificate is failing, and which tool fixes it: an alarm-to-fix map for vCenter 7, 8 and 9, vCert vs lsdoctor, and auto-renewal.

Short answer: start by identifying the certificate, not the tool. Run the VECS expiry check below or a vCert health check (option 1), then match the alarm or error to the table on this page. vCert fixes most vCenter certificate problems: Machine SSL, solution users, STS signing, trust anchors and ESXi. lsdoctor fixes the Lookup Service registrations that point at them. From vCenter 8.0 U3h and VCF 9.0.2, VMCA-issued Machine SSL and ESXi certificates renew themselves, but only in vmca mode and only a few days before expiry.

This page is the index for every certificate article on vDan. Each link says when to read it.

First check: which certificate is expiring?

Most vCenter certificates live in VECS, the VMware Endpoint Certificate Store. This loop from Broadcom KB 396907 prints every store with the alias and expiry date of each entry. Run it as root in the vCenter appliance shell:

for i in $(/usr/lib/vmware-vmafd/bin/vecs-cli store list); do echo STORE $i; sudo /usr/lib/vmware-vmafd/bin/vecs-cli entry list --store $i --text | egrep "Alias|Not After"; done

The store name tells you which certificate you are dealing with:

Store or certificateWhat uses itRead
MACHINE_SSL_CERTThe vCenter endpoint certificate that browsers and API clients seeAuto-renewal: when you still need vCert
Solution users (machine, vsphere-webclient, vpxd, vpxd-extension, wcp, hvc)Internal service-to-service authenticationvCert guide · certificate-manager scripting
STS signing certificate (not a VECS store; check it with vCert)Signs every vCenter SSO tokenSTS signing certificate guide
STS_INTERNAL_SSL_CERTLegacy STS store on vCenters upgraded from 6.xSTS_INTERNAL_SSL_CERT and vCert’s LEGACY result
BACKUP_STORE, BACKUP_STORE_H5CRollback copies of replaced certificatesCertificate alarm after renewal: check the backup stores
TRUSTED_ROOTSCA certificates that vCenter trustsvCert guide (trusted root options)
ESXi host certificate (stored on the host, tracked by vCenter)Host management endpointESXi Host Certificate Status alarm

Alarm or error → fix

Find the message you see and go straight to the fix.

You seeLikely causeRead
“STS Signing Certificates are about to expire”, or “no healthy upstream” at loginSTS signing certificate within 90 days of expiry, or already expiredSTS signing certificate guide
“ESXi Host Certificate Status” alarmA host certificate expires within about 30 daysESXi Host Certificate Status: Renew, VMCA mode, vCert
A Certificate Status alarm that stays raised after you renewedAn old copy in a backup store, or a certificate that renewal doesn’t coverCheck the backup stores · What auto-renewal covers
vCert reports STS as LEGACY; an old certificate still shows after a Machine SSL renewalSTS still uses the pre-7.0 STS_INTERNAL_SSL_CERT storeSTS_INTERNAL_SSL_CERT explained
“HTTP Status 500 – Internal Server Error” at the vSphere Client loginExpired certificates, a corrupted STS cache after patching, or broken SSO registrationsHTTP 500: causes and fixes
Lookup Service errors, SSL trust mismatch in service registrationsRegistrations still point at an old certificatelsdoctor guide
lsdoctor fails with an IndexError on vCenter 8.0.3.00000A customised login bannerlsdoctor on 8.0.3.00000
VCF 9.0 “Certificate authorities update failed” (401 in vmware_vrlcm.log)# or & in the Microsoft CA service account password (KB 406901)KB 406901 fix
VCF 9 upgrade stops at the vRNI / Aria Operations for Networks SSL thumbprint checkSDDC Manager stores the thumbprint of a replaced certificatevRNI SSL thumbprint fix
vROps / Aria Operations: “Data Retriever is not initialized yet”Expired internal certificate (KB 71018)Replace the vROps internal certificate
VAMI: “Exception in invoking authentication handler User password expired”Not a certificate: the appliance root password expiredvCenter password expired

Tools: vCert, lsdoctor and certificate-manager

ToolUse it forWhere to get itGuide
vCert (vCert.py)Checking and replacing vCenter certificates: Machine SSL, solution users, STS signing, trust anchors, VMCA and ESXi. Supports vCenter 7.0, 8.0 and 9.x.Broadcom KB 385107vCert guide
lsdoctor (lsdoctor.py)Checking and repairing Lookup Service registrations, SSL trust and solution users. Start with the read-only --lscheck.Broadcom KB 320837lsdoctor guide
certificate-managerThe older built-in, interactive-only menu. Broadcom now recommends vCert for most certificate workflows.On the appliance: /usr/lib/vmware-vmca/bin/certificate-managerScripting certificate-manager, and when to use vCert instead

A rule that saves time: vCert changes certificates, lsdoctor fixes what points at them. If you replace a certificate and services then fail to register or trust each other, that is lsdoctor territory. Take an offline snapshot of every vCenter in the SSO domain before running either tool.

Auto-renewal in vCenter 8.0 U3h and VCF 9.0.2

Per Broadcom KB 427937, vCenter 8.0 U3h and VCF 9.0.2 renew two certificate types natively:

  • VMCA-issued Machine SSL, 5 days before expiry;
  • VMCA-issued ESXi host certificates, 10 days before expiry by default (configurable).

Both require vpxd.certmgmt.mode = vmca. The certificate alarm fires at 30 days, so a certificate that will renew itself can still show a red alarm for about three weeks. Solution user, STS signing, externally issued and legacy-store certificates are not covered. vCenter Certificate Auto-Renewal: When You Still Need vCert has the full table, including the 9.1 threshold change.

VCF 9: fleet certificates and custom CAs

In VCF 9, VCF Operations Fleet Management can renew certificates for VCF components, including ones from a Microsoft CA or OpenSSL. It isn’t a layer on top of the native vCenter renewal; it replaces it. Giving an ESXi host a CA-signed certificate through Fleet Management switches vCenter to custom mode, and new hosts then need a CA-signed certificate before you commission them.

Upgrade-time certificate traps

  • vCenters upgraded from 6.x can keep STS on the legacy store, so a Machine SSL renewal never reaches it. Check with vCert before the next upgrade.
  • HTTP 500 right after patching is often a corrupted STS Tomcat cache, not an expired certificate. Clear the cache.
  • VCF upgrade pre-checks compare stored thumbprints. After you replace a component certificate, SDDC Manager can still hold the old one. vRNI example.
  • Run a vCert health check after every upgrade. Stale trusted roots and mismatched trust anchors don’t expire into an outage on a schedule, so no renewal job finds them.

Other products and related certificates

Sources

VCF 9 Certificate Management: Custom CAs, Auto-Renewal, and Host Onboarding

How a custom CA changes VCF 9 certificate operations: what Fleet Management auto-renews, what stays manual, and how new ESX hosts must be onboarded.

Short answer: In VCF 9, the certificate authority you choose decides who renews each certificate. Certificates signed by a CA configured in VCF Operations (VMCA, Microsoft CA or OpenSSL CA) can be renewed manually or automatically from Fleet Management, 60 days before expiry. Certificates signed by an external CA that you import are yours to renew. And once ESX hosts get CA-signed certificates through Fleet Management, vCenter switches to custom certificate mode, so every new host needs a CA-signed certificate before you commission it.

Part of the series “vCenter and VCF Certificate Management: Diagnosis, Renewal, and Operations”: vCenter Certificate Auto-Renewal: When You Still Need vCert (start here) · STS_INTERNAL_SSL_CERT Explained: What vCert’s LEGACY Result Means · vCenter Certificate Alarm After Renewal? Check the Backup Stores

Where certificate management lives in VCF 9

Fleet-wide certificate work is done in the VCF Operations console. The menu path depends on the version of the documentation you follow:

  • VCF 9.0: Fleet Management > Certificates, then VCF Management (fleet components) or VCF Instances and pick an instance or domain.
  • VCF 9.1: Manage in the top navigation bar, then Fleet management > Certificates in the left pane. The same VCF Management / VCF Instances split applies.

The scope split matters. The CA and the auto-renewal setting are configured separately for VCF management components (VCF Operations, VCF Automation, identity broker, logs, networks, fleet management services) and for each VCF Instance (vCenter, ESX, NSX Manager, SDDC Manager). Three instances means three instance-level CA configurations to keep consistent. The same screens show certificates and Certificate Alerts, and let you generate CSRs, import and replace; 9.1 adds bulk operations.

Configured CA versus imported certificate

This is the distinction that drives the whole operating model. The VCF 9.1 documentation lists three configured CA types:

  • VMCA: the default signing CA, embedded in vCenter.
  • Microsoft CA (AD CS): integrated through the /certsrv web enrollment URL, a least-privileged service account and a certificate template you create on the CA.
  • OpenSSL CA: the CA embedded in SDDC Manager.

Scope is version-specific. The VCF 9.0 “Configure a Certificate Authority” page says that VCF management components support only Microsoft CA, while VCF Instance components support Microsoft CA and OpenSSL. The VCF 9.0 blog adds that the Fleet Management appliance acts as the CA for the management components when you leave them at their defaults. In 9.1, check the supported combinations for your build before you standardise.

Anything else counts as an external CA: a public CA, or an enterprise PKI that is not wired into VCF Operations. The 9.1 documentation is explicit about what that means in practice:

Operation in VCF OperationsConfigured CAExternal CASelf-signed
Generate CSR / importYesYesNo
Manual renewYesNoNo
Auto-renewYesNoNo
Replace with VMCA-signed (9.1.1+)YesYesYes
Auto-replace with VMCA before expiry (9.1.1+)n/aYesNo
Monitor for expiryYesYesYes

Summarised from the VCF 9.1 “Managing Certificates in VMware Cloud Foundation” page.

So an imported certificate is monitored but not renewed. For an external CA the cycle is manual: generate a CSR, have it signed outside VCF, import it (base64 .crt, .cer, .pem, .p7b or .p7c), then use Replace with imported certificate. Expired certificates cannot be replaced, so this must happen before expiry. The 9.1.1 auto-replace with VMCA is a fallback that changes the issuer, which your security team may not accept.

What auto-renewal actually covers

When you use Activate Auto-renewal at the management or instance level, VCF renews TLS certificates that meet two conditions: they were signed by a configured CA, and the component supports non-disruptive certificate (NDC) updates. Renewal starts 60 days before expiry. The 9.0 documentation lists the NDC-managed certificates: ESX SSL, vCenter machine SSL, NSX Manager (local manager and VIP), SDDC Manager, VCF Identity Broker, VCF Operations, VCF Automation, VCF Operations for logs, VCF Operations for networks, and Fleet Management.

Limits to plan around:

  • Microsoft CA and OpenSSL auto-renewal needs the CA configured first. A Microsoft CA must be reachable from VCF Operations and time-synchronised with SDDC Manager.
  • Root and intermediate certificates are never renewed.
  • In 9.1, if a certificate is already inside the 60-day window, renew it manually before you turn auto-renewal on.
  • System-managed certificates, such as internal certificates without a customer-facing API, are renewed by their own component. VCF Operations only monitors them and raises an alert if that renewal fails.
  • vCenter also has its own native auto-renewal (vCenter 8.0 U3h / VCF 9.0.2 and later). According to KB 427937, it renews ESXi certificates 10 days before expiry (vpxd.certmgmt.certs.autoRenewThreshold) and the machine SSL certificate 5 days before, and it does not work when the certificate mode is custom. For VCF, Broadcom recommends configuring the CA in Fleet Management instead. The auto-renewal article in this series covers the vCenter side.

Custom certificate mode and new ESX hosts

This is the part that catches teams during expansion. KB 427937 says that the first time you configure an ESX host with a CA-signed certificate through Fleet Management, vCenter’s vpxd.certmgmt.mode advanced setting changes to custom. As a result, you must apply a CA-signed certificate to new hosts before you commission them. KB 417983 adds that the switch happens even when the replacement certificate comes from VMCA, because vCenter does not allow ESX certificate changes outside custom mode. After the switch, vCenter raises the alarm “When ESXi Certificate Mode is set to custom it is mandatory to add the custom CA certificates to vCenter trusted root store before updating the host certificates”. The KB treats this as expected and says you can reset it to green.

In custom mode, vCenter no longer provisions VMCA certificates to hosts, and certificate management becomes your responsibility (see vSphere 9.0 “Change the ESX Certificate Mode”). If you try to commission a host that still has its default certificate, it can fail validation with Host SSL certificate is not trusted by SDDC Manager / SDDC_TRUST_HOST_SSL_CERT_FAILED (KB 415767, VCF 5.2.x and 9.x). The commissioning documentation states the same rule for deployments done with external ESX certificates: all hosts added later must also use external certificates.

A repeatable onboarding procedure for a fleet in custom mode:

  1. Check the mode on the target vCenter: Configure > Advanced Settings, filter on vpxd.certmgmt.
  2. Prepare the host as usual: DNS forward and reverse records, host name equal to the FQDN, self-signed certificate regenerated for the FQDN.
  3. Issue a certificate for the host from the same CA chain the rest of the domain uses. Include the FQDN in the SAN; in 9.1, VCF Operations requires both the FQDN and the IP in the SAN for certificates it generates or imports.
  4. Install it on the host (/etc/vmware/ssl/rui.crt and rui.key, then restart hostd and vpxa), following “Configure ESX Hosts with Signed Certificates”.
  5. Make sure the issuing root and any intermediates are trusted by vCenter and SDDC Manager, then commission the host.
  6. After the host is added, confirm it appears under the instance in Fleet Management with Show ESX Hosts turned on, and that it falls under auto-renewal if its issuer is a configured CA.

KB 415767 also describes a workaround for environments that moved to external certificates after bring-up: temporarily set the mode back to vmca, commission the host, then revert. The new host then carries a VMCA certificate that you still have to replace, so treat this as an exception.

Certificate ownership matrix

A template to complete for your own fleet. Rows reflect the documented behaviour described above. Where the documentation does not settle a cell for every deployment, the cell says “check your deployment”.

ComponentIssuerRenewal mechanismMonitoringOnboarding procedure
vCenter machine SSLVMCA, Microsoft CA or OpenSSL CA (configured)Fleet Management auto-renewal, 60 days before expiry (NDC)Fleet Management > Certificates, Certificate AlertsReplace with configured CA certificate at instance level
ESX host SSLConfigured CA (mode switches to custom)Fleet Management auto-renewal (NDC)Certificate Alerts, Show ESX Hosts; vCenter host certificate alarmsCA-signed certificate on the host before commissioning
NSX Manager (LM and VIP)Configured CAFleet Management auto-renewal (NDC)Certificate AlertsCheck your deployment
SDDC ManagerConfigured CAFleet Management auto-renewal (NDC)Certificate AlertsCheck your deployment
VCF Operations, Automation, logs, networks, identity broker, Fleet ManagementVCF 9.0: Microsoft CA or Fleet Management default CA; 9.1: check your deploymentManagement-level auto-renewal (NDC)Certificate Alerts (VCF Management)Check your deployment
Any component with an imported external-CA certificateExternal / public CAManual: CSR, sign, import, replace, before expiryExpiry monitoring in VCF OperationsYour PKI process; record the owner and expiry date
System-managed internal certificatesComponent-internalRenewed by the component itselfVCF Operations alerts on failed renewalCheck your deployment

In your own copy, add a named owner and the CA template used for each row. Use the same CA settings (URL, template, service account) in every VCF Instance, and keep imported external-CA certificates to a minimum, because each one is a manual renewal. If the CA wizard fails in VCF 9.0, see the KB 406901 write-up.

Sources

Related on vdan.cz

vCenter Certificate Auto-Renewal: When You Still Need vCert

vCenter 8.0 U3h and VCF 9.0.2 renew VMCA Machine SSL and ESXi certificates automatically. What is covered, which thresholds apply, where vCert fits.

Short answer: Partly. From vCenter 8.0 Update 3h and VCF 9.0.2, vCenter renews VMCA-issued Machine SSL and ESXi host certificates automatically, but only when vpxd.certmgmt.mode is vmca, and only just before expiry: 5 days for Machine SSL, 10 days (configurable) for ESXi. Solution user, STS signing, externally issued and legacy-store certificates are not covered. You still need to know which mechanism owns each certificate, and keep vCert ready for recovery.

Part of the series “vCenter and VCF Certificate Management: Diagnosis, Renewal, and Operations”: this article is the entry point. Troubleshooting: STS_INTERNAL_SSL_CERT Explained: What vCert’s LEGACY Result Means and vCenter Certificate Alarm After Renewal? Check the Backup Stores. Fleet operations: VCF 9 Certificate Management: Custom CAs, Auto-Renewal, and Host Onboarding.

What changed in 8.0 U3h and VCF 9.0.2

Before vCenter 8.0 Update 3h, an expiring VMCA-issued Machine SSL certificate was an administrator task. If nobody acted, the certificate expired and services such as vpxd-svcs and sps stopped starting. Broadcom KB 396907 describes that failure and the manual fix with vCert.

The vCenter 8.0 U3h and VCF 9.0.2 release notes add native auto-renewal for two certificate types:

  • vCenter Machine SSL: extended by 2 years once fewer than 5 days remain.
  • ESXi host SSL: extended by 5 years once fewer than 10 days remain. This applies to hosts that support non-disruptive certificate renewal. The 8.0 U3h notes limit it to ESXi 8.0 Update 3 and later.

Both renewals apply only to certificates that VMCA issues. Both stop working if the vCenter advanced setting vpxd.certmgmt.mode is custom. KB 427937 adds that vCenter services are not restarted during the renewal.

Three renewal mechanisms, not one

“Auto-renewal” can mean three separate things, and they have different thresholds and eligibility rules. Before you trust any of them, check which one owns the certificate in front of you.

MechanismCoversWhen it renewsConditionSource
Native vCenter, Machine SSLvCenter Machine SSL certificate issued by VMCA5 days before expiry; fixed, not configurablevpxd.certmgmt.mode = vmca; vCenter 8.0 U3h+ or VCF 9.0.2+KB 427937, 8.0 U3h and 9.0.2 release notes
Native vCenter, ESXiESXi host certificates issued by VMCA10 days before expiry (8.0 U3h / 9.0.2); configurable via vpxd.certmgmt.certs.autoRenewThresholdvmca mode; host supports non-disruptive renewalKB 427937, release notes
VCF Operations Fleet ManagementVCF components with VMCA, Microsoft CA, OpenSSL or self-signed certificates that support non-disruptive updates60 days before expiryAuto-renewal toggle turned on per VCF Management or per VCF Instance; for Microsoft CA or OpenSSL, a CA configured firstKB 427937, VCF 9.0 TechDocs

One side effect is easy to miss. KB 427937 says that the first time you give an ESXi host a CA-signed certificate through Fleet Management, vCenter switches vpxd.certmgmt.mode to custom. After that, new hosts need a CA-signed certificate before you commission them, and the native vCenter renewal in the first two rows stops applying. Fleet Management and native renewal are alternatives, not layers. Article 4 of this series covers the Fleet Management side.

The ESXi threshold depends on version and source

Published values for the native ESXi renewal threshold differ:

SourceVersionESXi renewal threshold
vCenter 8.0 U3h release notesvCenter 8.0 U3hfewer than 10 days
VCF 9.0.2 vCenter release notesVCF 9.0.2fewer than 10 days
KB 427937vCenter 8.0 U3h, VCF/VVF 9.0.210 days, changeable with vpxd.certmgmt.certs.autoRenewThreshold
“What’s New with vSphere in VCF 9.1” (VMware blog, May 2026)vSphere in VCF 9.130 days, configurable with the same setting

The most likely explanation is that the default changed in 9.1, but I have not found release notes that state this directly. Don’t rely on either number. Check the value your vCenter actually uses:

  1. In the vSphere Client, select the vCenter Server and open Configure > Settings > Advanced Settings.
  2. Filter on vpxd.certmgmt.
  3. Check vpxd.certmgmt.mode. It must be vmca for native renewal.
  4. Check vpxd.certmgmt.certs.autoRenewThreshold (days). Broadcom does not say whether this key is listed when it has never been set. If it is missing, assume the documented default for your version.
  5. While you are there, note vpxd.certmgmt.certs.hardThreshold. TechDocs gives it a default of 30 days and describes it as the point where vCenter raises a red alarm.

Why the alarm fires before renewal is due

KB 427937 says the certificate pre-expiration alarm fires 30 days before expiry by default. KB 397104 ties the Certificate Status alarm to vpxd.cert.threshold and vpxd.certmgmt.certs.hardThreshold, both 30 by default. Native renewal does not start until 5 days (Machine SSL) or 10 days (ESXi, 8.0 U3h / 9.0.2) before expiry. That means a healthy, eligible certificate can keep a red alarm raised for about three weeks before renewal happens.

KB 427937 also says renewal follows the certificate’s expiration date, not the time the alarm fired. You have two options: renew early yourself, or confirm eligibility and let the alarm run its course. What you must not do is assume the alarm will clear on its own. It will not if the certificate is not eligible, for example a solution user certificate (KB 397104). It also will not clear if the certificate that triggers it lives in a store that renewal never touches. Article 3 covers the BACKUP_STORE case.

Where auto-renewal does not help, and vCert does

  • An expired Machine SSL certificate. If the vCenter is below 8.0 U3h, or the certificate already expired while in custom mode, KB 396907 still points to manual replacement with vCert (Manage certificates > Machine SSL certificate) followed by a restart of all services.
  • Solution user certificates. KB 397104 resolves expiring solution user certificates by replacing them, for example with vCert. Native renewal covers only Machine SSL and ESXi.
  • Legacy STS configuration. On vCenters upgraded from 6.x, the STS service can still use the old STS_INTERNAL_SSL_CERT store, and Machine SSL renewal never updates it. See article 1.
  • STS signing certificate. This is a separate certificate with its own failure pattern (“no healthy upstream”). See the STS signing certificate guide.
  • Externally issued certificates. The VCF 9.1 vSphere blog is explicit that certificates from an external CA are not auto-renewed natively. The administrator owns them, or Fleet Management does in VCF.
  • Trust problems and health checks. Stale trusted roots, mismatched trust anchors and certificates left in unused stores do not expire into an outage on a schedule, so no renewal job fixes them. A regular vCert health check (option 1) after each upgrade finds them. The vCert guide explains how to read the report.

The same blog notes that in 9.1 the VMCA root and its solution user certificates are renewed during a vCenter upgrade if the root expires in less than a year. Machine SSL and ESXi certificates are not renewed in that step.

A quick eligibility check

To see what is actually in VECS and when each entry expires, KB 396907 gives this loop. Run it on the vCenter appliance shell:

for i in $(/usr/lib/vmware-vmafd/bin/vecs-cli store list); do echo STORE $i; sudo /usr/lib/vmware-vmafd/bin/vecs-cli entry list --store $i --text | egrep "Alias|Not After"; done

Illustrative output (placeholder dates, trimmed):

STORE MACHINE_SSL_CERT
Alias : __MACHINE_CERT
            Not After : <date within 30 days>   <- alarm raised; native renewal at 5 days if mode = vmca
STORE STS_INTERNAL_SSL_CERT
Alias : __MACHINE_CERT
            Not After : <date>                   <- legacy store; not touched by renewal (see article 1)
STORE BACKUP_STORE
Alias : bkp___MACHINE_CERT
            Not After : <past date>              <- old copy; see article 3

For each certificate that expires soon, answer three questions: who issued it (VMCA or external), which mechanism owns it (native, Fleet Management or nobody), and does that mechanism’s condition hold. If the answer to the second question is “nobody”, renew it yourself with vCert, or through Fleet Management in VCF.

So, can you stop renewing manually?

For VMCA-issued Machine SSL and ESXi certificates on a vCenter in vmca mode: mostly yes, provided you accept an alarm that fires weeks before the renewal. For everything else, including VCF components with a custom CA, solution users, STS and legacy stores: no. Those need an owner, a monitor and a tested recovery procedure.

Sources

Related on vdan.cz

STS_INTERNAL_SSL_CERT Explained: What vCert’s LEGACY Result Means

Renewed Machine SSL but port 3128 still shows an old cert? What vCert’s LEGACY STS result means and how to move STS to MACHINE_SSL_CERT.

Short answer: STS_INTERNAL_SSL_CERT is a legacy VECS store that older vCenter releases used for the Security Token Service (STS) TLS listener. After an upgrade, the STS service can still point at that store, so renewing the Machine SSL certificate does not change what STS presents on port 3128. vCert reports this as LEGACY. Broadcom’s fix is to switch the STS configuration to MACHINE_SSL_CERT with vCert, restart vmware-stsd, and then remove the old store (KB 423742, KB 424604).

Part of the series “vCenter and VCF Certificate Management: Diagnosis, Renewal, and Operations”: vCenter Certificate Auto-Renewal: When You Still Need vCert (start here) · vCenter Certificate Alarm After Renewal? Check the Backup Stores · VCF 9 Certificate Management: Custom CAs, Auto-Renewal, and Host Onboarding

The symptom: new Machine SSL certificate, old STS certificate

The usual sequence goes like this. You replace or renew the Machine SSL certificate, the vSphere Client shows the new certificate on 443, and everything looks healthy. Then a vulnerability scanner flags an expired or soon-to-expire certificate on port 3128, or an identity-related compliance check fails. Or you run vCert and the STS configuration check comes back as LEGACY.

Nothing went wrong with the renewal. There are simply two different certificate sources involved, and the one on 443 is not the one STS is using.

Where STS_INTERNAL_SSL_CERT comes from and why it survives upgrades

In vCenter 6.x and earlier, the vmware-stsd service took its TLS certificate from a dedicated VECS store named STS_INTERNAL_SSL_CERT. Upgrades migrate that configuration so that STS keeps working, which means the old store reference can live on for years. Broadcom’s sources describe the origin slightly differently:

  • KB 423742: usually left behind after upgrading from vCenter 5.5 or 6.x to 7.x or 8.x.
  • The vCert KB 385107: the legacy store is present if the system was upgraded from 5.5; greenfield 6.x/7.x deployments use MACHINE_SSL_CERT.
  • KB 316625: found on appliances that were originally Windows vCenter Servers and were later migrated to the VCSA. According to that KB, new 8.x deployments do not have this store.

So the practical rule is simple: if the vCenter has a long upgrade history, check for it. KB 423742 also explains why it causes trouble. Newer vCenter versions do not refresh this store when the Machine SSL certificate is renewed, so the certificate inside it can expire without anyone noticing. On 7.x/8.x, the STS store reference is defined in /usr/lib/vmware-sso/vmware-sts/conf/server.xml (KB 316625). On vCenter 9.0 and later, STS runs on an embedded Tomcat and the reference moved to /usr/lib/vmware-sso/vmware-sts/conf/catalina.properties (KB 438122).

STS TLS certificate vs. STS signing certificate

These two are often confused because both have “STS” in the name. They are different objects with different jobs, and vCert handles them in different menus.

STS TLS (server) certificateSTS signing certificate
PurposeSecures the TLS connection to the STS listenerSigns SAML tokens issued by SSO
Where it livesMACHINE_SSL_CERT (expected) or legacy STS_INTERNAL_SSL_CERT in VECSTenantCredential entries in VMware Directory
Who sees itAnything connecting to port 3128, including scannersServices validating SSO tokens
vCert: check/view5. Check configurations → 2. Check STS server certificate and configuration2. View certificate info → 8. STS signing certificates
vCert: fixSwitch STS to MACHINE_SSL_CERT and restart vmware-stsdReplace the STS signing certificate (Manage certificates)
Symptom when expiredScanner/compliance finding on 3128Login failures, “No Healthy Upstream”

A LEGACY result is about the left column only. If users cannot log in and the vSphere Client shows “No Healthy Upstream”, you are looking at the signing certificate instead; see vCenter STS signing certificate expiration.

How to read the vCert configuration check

If you have not used vCert yet, start with installing and using the vCert tool. The main menu option 1. Check current certificate status checks certificate health, meaning expiry, SAN and key usage. It does not tell you which store STS reads from. That question is answered by 5. Check configurations → 2. Check STS server certificate and configuration. This check does two things (KB 385107):

  1. It checks which VECS store the STS service is configured to use. Anything other than MACHINE_SSL_CERT is reported as LEGACY, and vCert offers to update the configuration and restart the service.
  2. It checks the vmwSTSConnectionStrings attribute in VMware Directory. A standalone vCenter should reference its own hostname; a node in Enhanced Linked Mode should reference localhost. If the value is wrong, vCert prompts you to correct it.

Inspect what port 3128 actually presents

KB 423742 identifies the STS listener as port 3128 and gives this command to run on the appliance:

openssl s_client -connect localhost:3128 -showcerts

For a shorter comparison, you can pipe the output through standard openssl x509 and put it side by side with the Machine SSL certificate on 443. This is plain OpenSSL usage, not a Broadcom-specific procedure:

for p in 443 3128; do
  echo "== port $p"
  openssl s_client -connect localhost:$p </dev/null 2>/dev/null | openssl x509 -noout -subject -issuer -enddate
done

To see whether the legacy store exists and what its entry expires, use the VECS listing from KB 424604 / KB 316625:

for i in $(/usr/lib/vmware-vmafd/bin/vecs-cli store list); do echo STORE $i; /usr/lib/vmware-vmafd/bin/vecs-cli entry list --store $i --text | egrep "Alias|Not After"; done

Broadcom’s workflow: KB 423742 and KB 424604

There are two KBs, and they cover two stages. KB 423742 (“STS_INTERNAL_SSL_CERT replacement using vCert”) switches the STS configuration interactively through the vCert menu. KB 424604 (“Removing STS_INTERNAL_SSL_CERT from vCenter Server with vCert”) removes the store, with a Lookup Service check first. Both apply to vCenter 7.x and 8.x, and both restart vmware-stsd. Combined, the procedure is:

  1. Take a backup or snapshot. KB 424604 makes an offline snapshot mandatory. In Enhanced Linked Mode, take offline snapshots of all nodes.
  2. Check the Lookup Service with lsdoctor: python lsdoctor.py -l. If it finds stale registrations, run python lsdoctor.py -s (stale configuration left over from 5.x) and then python lsdoctor.py -t (SSL trust mismatch). See the lsdoctor guide, and note that KB 320837 requires a service restart after -s and -t.
  3. Run vCert. Either use the menu (./vCert.py → 5 → 2, then SSO administrator credentials) as in KB 423742, or run the check directly as in KB 424604: python vCert.py --run config/check_config/sts_config/op_check_sts_config.yaml
  4. Answer y to “Update STS server configuration to use the MACHINE_SSL_CERT store?”
  5. Answer y to “Restart service(s) vmware-stsd”.
  6. Validate: port 3128 should now present the Machine SSL certificate, and the vCert check should no longer say LEGACY.

Do not delete the store by hand first. KB 316625 warns that removing STS_INTERNAL_SSL_CERT while server.xml still references it stops STS from starting, and the other vCenter services then fail with it. The configuration change always comes before the removal. That KB (and KB 438122 for vSphere 9.x) documents script and manual alternatives in case vCert is not an option.

Annotated example: before and after

Illustrative example only. Host names and dates are placeholders. The LEGACY line follows the format shown in KB 423742. Your vCert version may word the post-fix line differently.

# BEFORE - vcsa01.lab.local, upgraded from 6.x
== port 443
subject=CN = vcsa01.lab.local
issuer=CN = CA, DC = vsphere, DC = local, ...
notAfter=<new date, e.g. 2028>          <-- renewed Machine SSL, fine
== port 3128
subject=CN = vcsa01.lab.local
issuer=CN = CA, DC = vsphere, DC = local, ...
notAfter=<old date, already past>     <-- what the scanner reports

vCert: 5. Check configurations -> 2. Check STS server certificate and configuration
Checking STS Server Configuration
-----------------------------------------------------------------
Checking VECS store configuration                          LEGACY
                                    ^-- STS reads STS_INTERNAL_SSL_CERT, not MACHINE_SSL_CERT
Update STS server configuration to use the MACHINE_SSL_CERT store? [y/n]: y
Restart service(s) vmware-stsd [y/n]: y

# AFTER
== port 3128
subject=CN = vcsa01.lab.local
notAfter=<same date as port 443>       <-- 3128 and 443 now match
vCert STS check: no longer LEGACY           <-- configuration uses MACHINE_SSL_CERT
vecs-cli store list: no STS_INTERNAL_SSL_CERT entry (after KB 424604 removal)

A short checklist after the change: the 3128 and 443 certificates should have the same expiry date, vmware-stsd should be running, a vSphere Client login should work, and the scanner should be clean on its next pass. KB 423742 also says that once STS uses the Machine SSL store, later Machine SSL renewals carry over to STS as expected. For how renewals themselves are scheduled and monitored, see vCenter Certificate Auto-Renewal: When You Still Need vCert. If an expiry alarm still points at an old certificate after the fix, check the BACKUP_STORE article.

Sources

Related on vdan.cz

vCenter Certificate Alarm After Renewal? Check the Backup Stores

Why a vCenter certificate alarm can point to an old rollback copy in BACKUP_STORE or BACKUP_STORE_H5C, and how to verify and clear it with vCert.

Short answer: the Certificate Status alarm checks every store in VECS, not only the certificates vCenter actively uses. Replacing certificates saves the old ones in BACKUP_STORE and BACKUP_STORE_H5C so you can roll back, and when those copies expire they can raise the alarm. Find out which store and alias the alarm refers to. Confirm the active Machine SSL and solution user certificates are valid. Then use vCert to clear the expired backup entries. Your vCenter version decides which backup store can still raise the alarm.

Part of the series “vCenter and VCF Certificate Management: Diagnosis, Renewal, and Operations”: vCenter Certificate Auto-Renewal: When You Still Need vCert (start here) · STS_INTERNAL_SSL_CERT Explained: What vCert’s LEGACY Result Means · VCF 9 Certificate Management: Custom CAs, Auto-Renewal, and Host Onboarding

Why a renewal leaves certificates behind

A Machine SSL or solution user replacement on the vCenter Server Appliance doesn’t simply discard the old certificate. According to KB 326268, the replacement creates two VECS stores, BACKUP_STORE and BACKUP_STORE_H5C. The old certificates go into them so the change can be reverted. The vSphere documentation describes BACKUP_STORE as the store that supports certificate revert. It keeps only the most recent state, so you can go back one step and no further.

Nothing removes these entries automatically. They keep their original validity dates. The certificate you replaced a year ago still sits in the backup store, and its expiry date keeps getting closer. vCenter watches all VECS stores (KB 318973). When a backup copy nears or passes its expiry date, you can get a Certificate Status alarm even though every certificate vCenter actually uses is fine.

Step 1: find the store the alarm refers to

Before you change anything, find out which certificate raised the alarm. KB 318973 documents the vpxd warning that the expiry check writes. The warning includes the certificate subject and the VECS store name:

grep "will expire on" /var/log/vmware/vpxd/vpxd.log | tail -20

# Message format documented in KB 318973:
# ... opID=CheckCertificateExpiry-... Certificate [Subject: <Certificate Subject>] from store <VECS Store Name> will expire on YYYY-MM-DD HH:MM:SS

If the store is MACHINE_SSL_CERT or a solution user store, the problem is real and you need to renew. If it is BACKUP_STORE or BACKUP_STORE_H5C, read on.

Step 2: compare active and backup certificate expiry

Run this over SSH as root to list the alias and the “Not After” date for every store except TRUSTED_ROOT_CRLS. KBs 318973 and 326268 both use it:

for store in $(/usr/lib/vmware-vmafd/bin/vecs-cli store list | grep -v TRUSTED_ROOT_CRLS); do echo "[*] Store :" $store; /usr/lib/vmware-vmafd/bin/vecs-cli entry list --store $store --text | grep -ie "Alias" -ie "Not After";done;

To check only the two backup stores:

/usr/lib/vmware-vmafd/bin/vecs-cli entry list --store BACKUP_STORE --text | grep -ie "Alias" -ie "Not After"
/usr/lib/vmware-vmafd/bin/vecs-cli entry list --store BACKUP_STORE_H5C --text | grep -ie "Alias" -ie "Not After"

Compare the results with the active stores. MACHINE_SSL_CERT holds the __MACHINE_CERT alias. The solution user stores are machine, vpxd, vpxd-extension, vsphere-webclient and, depending on the version, hvc and wcp. Backup aliases have a bkp_ prefix, for example bkp___MACHINE_CERT or bkp_vpxd. If the active entries show future dates and only bkp_* entries have expired, the alarm is about a rollback copy.

Menu option 1 in vCert, “Check current certificate status”, gives the same view. It has its own “Checking BACKUP_STORE entries” section. The excerpt below is illustrative and follows the format shown in KB 425134:

# Illustrative example - vcsa01.lab.local, not real output
Checking Machine SSL certificate                 VALID
Checking Solution User certificates:
   machine                                       VALID
   vpxd                                          VALID
   vpxd-extension                                VALID
   vsphere-webclient                             VALID
Checking BACKUP_STORE entries:
   bkp___MACHINE_CERT                            EXPIRED   <-- old rollback copy
   bkp_machine                                   VALID
   bkp_vpxd                                      VALID

Step 3: know how your version behaves

This is where the version matters. The KBs describe it this way:

  • KB 326268 (applies to vCenter 6.x, 7.x, 8.x): from vCenter Server 7.0 Update 3 and in 8.0, an expired certificate in BACKUP_STORE no longer raises the alarm. An expired certificate in BACKUP_STORE_H5C still does, and you have to delete it to clear the alert.
  • KB 425734: vCert can flag BACKUP_STORE certificates that are expiring or expired. The KB says this has no impact on the system. Wait until they expire and then remove them with vCert, or open a support case if you want them removed earlier.
  • KB 445656 (7.x and 8.x): the backup entries are historical, inactive copies. The KB still recommends clearing them with vCert to prevent Certificate Status alarms.
  • KB 425134: expired BACKUP_STORE entries reported by vCert can also appear during vCenter upgrade prechecks. The fix is the same vCert cleanup.

So don’t assume every certificate warning is a false alarm, and don’t assume every one needs a renewal. On 7.0 U3 or 8.0, an alarm that persists while BACKUP_STORE is the only store with expired entries means you should keep looking. Check BACKUP_STORE_H5C and the other stores, and check the store name in vpxd.log. On older builds, an expired BACKUP_STORE entry alone can explain the alarm.

Troubleshooting table: store, active status, action

Store with expired/expiring entryActive Machine SSL / solution usersCan it raise the alarm?Action
MACHINE_SSL_CERT or solution user storeExpired or expiringYes. This is a real issue.Renew first (vCert option 3 or vSphere Client). Leave the backups alone until the new certificates work.
Any backup storeExpired or expiringYesTreat it as a real issue. Fix the active certificates first. The backup is your rollback path.
BACKUP_STOREValidBefore 7.0 U3: yes. 7.0 U3 and 8.0: not for expired entries (KB 326268).Clear the expired entries with vCert 3 → 12. On 7.0 U3/8.0, if the alarm persists, look for another store.
BACKUP_STORE_H5CValidYes, including 7.0 U3 and 8.0 (KB 326268)Clear the expired entries with vCert 3 → 12. vCert cleans this store too when it exists.
BACKUP_STORE, entries only approaching expiryValidReported by vCert. KB 425734 says there is no impact.Wait until they expire and then clear them, or ask Broadcom Support to remove them early.
MACHINE_SSL_CERT, alias __MACHINE_CSRValidYes (KB 318973)This is an old CSR entry. Clear it with vCert 3 → 14 or the KB 318973 command.
TRUSTED_ROOTS, SMS, STS_INTERNAL_SSL_CERT, othersValidYesDifferent cause. See KB 318973 and the STS_INTERNAL_SSL_CERT article.

Step 4: clear the backup stores with vCert

vCert is documented in KB 385107. The menu numbers below are from vCert 6.1.2, the version current in that KB when this post was written. Check them against the version you run. For installation, see my vCert guide.

  1. Take a VAMI file-based backup or a snapshot of the vCenter. In Enhanced Linked Mode, take powered-off snapshots of all vCenter nodes in the SSO domain.
  2. Optional: export the entry you are about to remove (KB 318973):
    /usr/lib/vmware-vmafd/bin/vecs-cli entry getcert --store BACKUP_STORE --alias bkp___MACHINE_CERT --output /root/old_machine.crt
  3. Run ./vCert.py, then choose 3. Manage certificates and then 12. Clear expired certificates in BACKUP_STORE in VECS. KB 385107 says this option clears expired entries in BACKUP_STORE, and in BACKUP_STORE_H5C if that store exists.
  4. Verify the result. Run vCert 1. Check current certificate status again, or rerun the vecs-cli loop. No expired bkp_* entries should remain.
  5. If an alarm still shows after the stores are clean, reset it to green in the vSphere Client. KB 423484 notes that the alarm does not clear by itself after a certificate fix.

If vCert doesn’t clear an entry, KB 326268 gives a manual fallback. List the store, note the alias, and delete that one entry:

/usr/lib/vmware-vmafd/bin/vecs-cli entry list --store BACKUP_STORE
/usr/lib/vmware-vmafd/bin/vecs-cli entry delete --store BACKUP_STORE --alias <cert_alias>

According to the vecs-cli reference, entry delete removes the entry from VECS permanently. Delete only the aliases you identified as expired backup copies. Never delete entries from the active stores, and don’t touch TRUSTED_ROOT_CRLS unless a KB tells you to.

Preventing a repeat

Every Machine SSL or solution user replacement leaves another backup copy behind. Once you have confirmed that the new certificates work, add a backup-store check to your runbook. This matters most when renewal is automated or done in batches, as covered in the auto-renewal article. On VCF 9, fleet-level certificate operations are covered in the custom CA article.

Sources

Related on vdan.cz

VCF 9 SAP HANA Network Design: Why 6 NICs Matter for vMotion and NFS

SAP HANA on VCF 9 with NFS: why storage needs its own NICs, separate from vMotion. The 2, 4 and 6 NIC models compared on Cisco VIC and HPE Synergy.

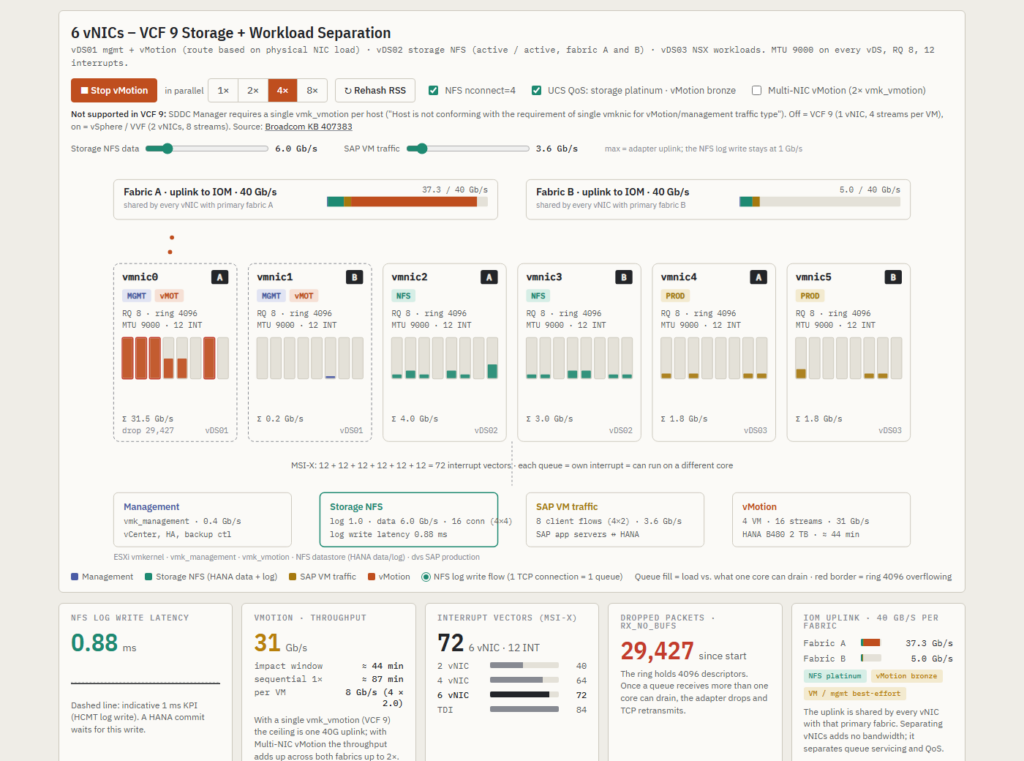
Short answer: on VCF 9 hosts that run SAP HANA on NFS, give storage its own pair of physical NICs (vNICs on Cisco UCS), separate from vMotion. The VCF 9.1 Design Library’s 6‑NIC Storage and Workload Separation model does this and also isolates NSX workloads, so I recommend it as the baseline. The 4‑NIC Storage Separation model also isolates NFS storage, but it puts SAP client traffic on the same switch as vMotion. The reason is host maintenance. A vMotion of a 2 TB HANA VM lands on the same receive queues as the NFS log writes of every HANA database on that host, unless storage has a vNIC of its own. HANA commits wait for those log writes. A faster adapter does not change that, and VCF 9 makes it worse by allowing only one vMotion VMkernel adapter per host. You can watch all of it happen in an interactive model: vdan.cz/vcf9-sap-hana-tdi-design.

VCF 9 SAP HANA 6-NIC network model: four parallel vMotions on vmnic0 while the NFS log write on vDS02 stays under 1 ms
6 vNICs, four HANA VMs migrating at once. vMotion saturates vmnic0, the storage vNICs on vDS02 carry only the 16 NFS connections of those four VMs, and the log write stays under 1 ms.

Why vMotion is a HANA problem and not just a network problem

HANA writes its redo log synchronously. A transaction commit returns only after storage has acknowledged the log write, so log write latency turns directly into application response time. The SAP HCMT tool checks this, and the indicative KPI for log write latency is about 1 ms. Under normal load a well built NFS path delivers a few hundred microseconds.

Now migrate a HANA VM with 1 to 2 TB of RAM. On a 40 Gb/s uplink a vMotion runs at 16 to 35 Gb/s for 10 to 20 minutes, including the dirty page iterations at the end. If that traffic shares the network path with storage, the log write latency jumps from sub‑millisecond to several milliseconds, commits stall, and the application servers see timeouts. This is why SAP and the FlexPod CVD separate vMotion from storage in the first place. The interesting part is where the sharing happens, because it is not only bandwidth.

What happens inside the adapter

On a Cisco UCS blade with a VIC, every vNIC in the service profile gets its own set of receive queues. The adapter policy used in the FlexPod TDI design gives each vNIC on a VIC 1380 8 receive queues with a ring of 4096 descriptors and 12 MSI‑X interrupts. On a VIC 15231 the policy is 16 queues, a ring of up to 16384 and 20 interrupts. Three details matter:

  • The adapter spreads incoming flows across the queues with an RSS hash of IP addresses and ports. It does not know what a flow is. One NFS log connection always lands on exactly one queue.
  • Each queue has its own interrupt and is serviced by one CPU core. A queue that receives more than its core can drain fills its ring and the adapter drops packets. That shows up as rx_no_bufs in esxcli network nic stats.
  • Queues belong to the vNIC. Two vNICs on the same physical adapter never compete for queues or cores. They share only the uplink to the IOM or IFM, and that is where QoS can help.

So if vMotion streams and the NFS log flow arrive on the same vNIC, the hash will sooner or later put a vMotion stream on the queue that also carries the log write. Network I/O Control cannot see that. NIOC shares bandwidth between port groups on the uplink, it does not assign queues. Only a separate vNIC does.

One remark for readers on HPE Synergy. The Synergy 6310C is a Broadcom NetXtreme‑E adapter (ESXi driver bnxtnet). A port is split into up to eight FlexNICs that share the ASIC’s pool of queues and interrupt vectors, and RSS defaults to 4 queues per function. A FlexNIC is still a separate function with its own RSS, so the storage FlexNIC does not receive vMotion packets, but the queues behind it are not dedicated in the way a Cisco VIC vNIC’s are, and there are fewer of them. The model treats it that way and I come back to it below.

The four layouts

I modelled the three VCF 9.1 network models and the classic FlexPod TDI layout side by side. Same host, same VIC 1380 with 2 × 40 Gb/s, same traffic: NFS log 1 Gb/s, NFS data 6 Gb/s, SAP client traffic 3.6 Gb/s and management. Every HANA VM on the host mounts its data and log with nconnect, so it brings four NFS connections and two client flows of its own. The number of VMs is the parallel selector: with four VMs the storage class has 16 NFS data connections and the VM class 8 flows, with eight VMs 32 and 16. Then those one to eight HANA B480 VMs with 2 TB RAM are migrated at once. The VCF 9 rows use the single vMotion VMkernel adapter VCF 9 allows, the TDI row uses Multi‑NIC vMotion as the CVD configures it. The numbers are model output, not measurements. The model exists to show the mechanism.

LayoutvNICsStorage isolated from vMotionLog write · idle1× vMotion4× vMotion8× vMotion
VCF 9 Single Distributed Switch2no0.34 ms1.82 ms2.37 ms3.49 ms
VCF 9 Workload Separation4no0.34 ms1.82 ms2.26 ms3.49 ms
VCF 9 Storage + Workload Separation6yes0.34 ms0.35 ms0.88 ms0.83 ms
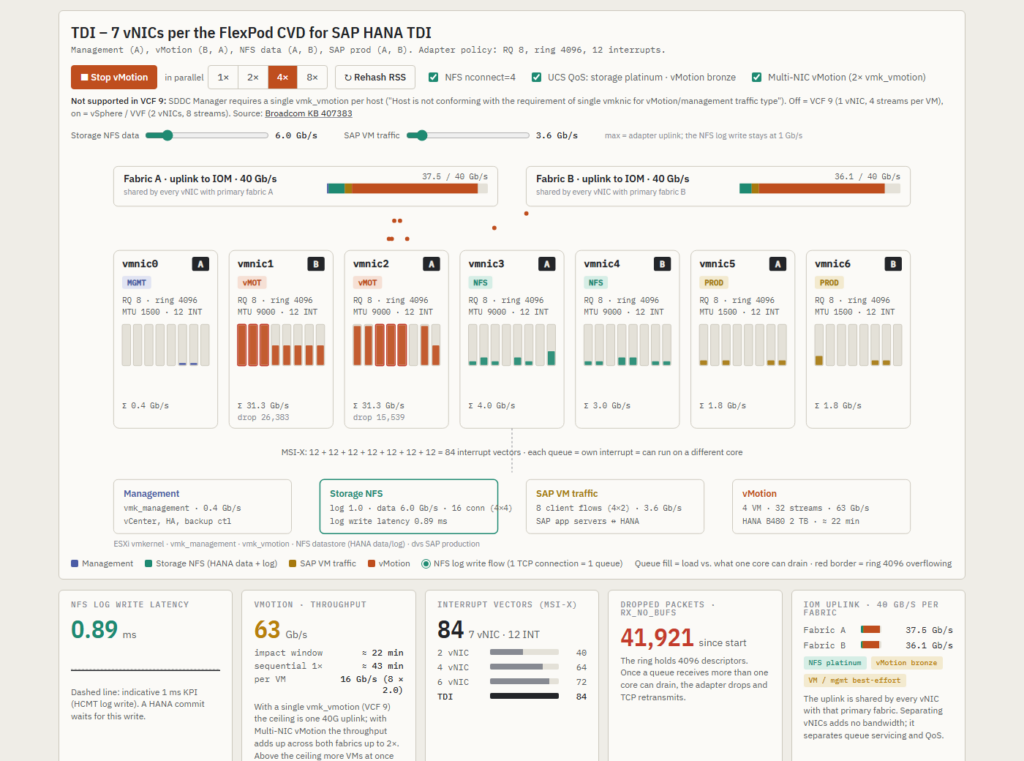
FlexPod SAP HANA TDI (Multi‑NIC vMotion)7yes0.34 ms0.35 ms0.89 ms0.84 ms

The split is clean. The two layouts that put vMotion and storage on the same vNIC cross the 1 ms KPI with a single migration. The two that give storage its own vNIC stay under it with eight. What remains in the 6 and 7 vNIC rows has two parts: uplink pressure, which is what the UCS QoS policy is for, and the fact that eight VMs bring 32 NFS data connections into the 16 storage queues, so the log flow starts sharing a queue with data connections of other databases. That second part is the argument for more queues on the storage vNIC, and I come back to it with the VIC 15231.

2 NICs: Single Distributed Switch

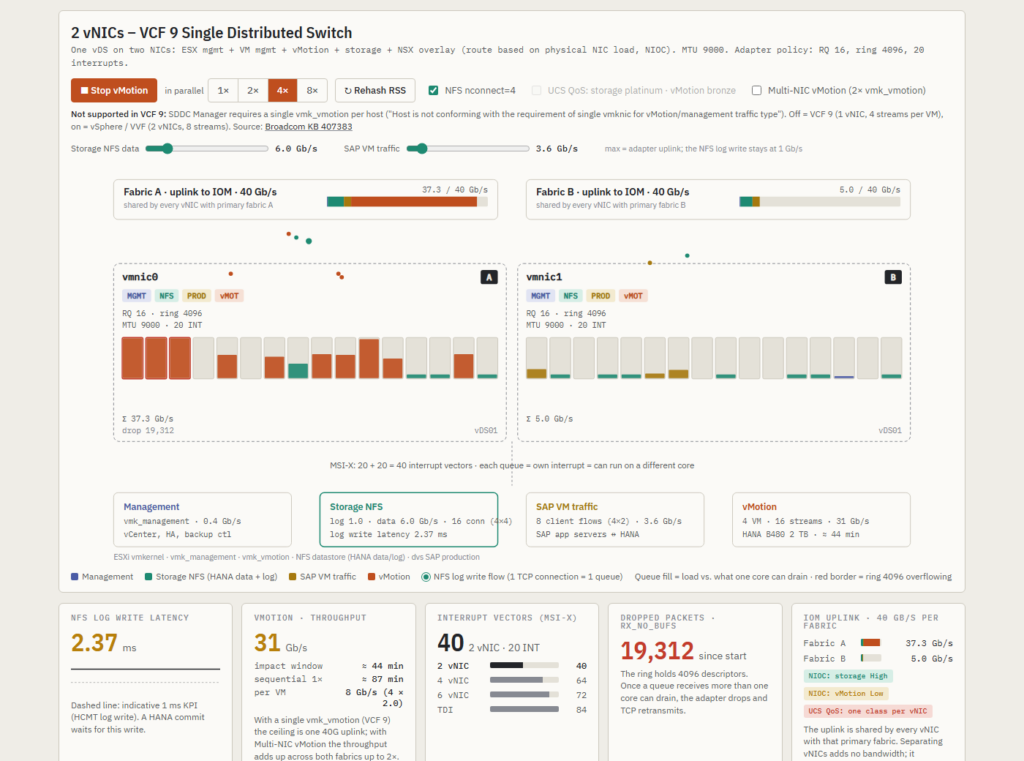
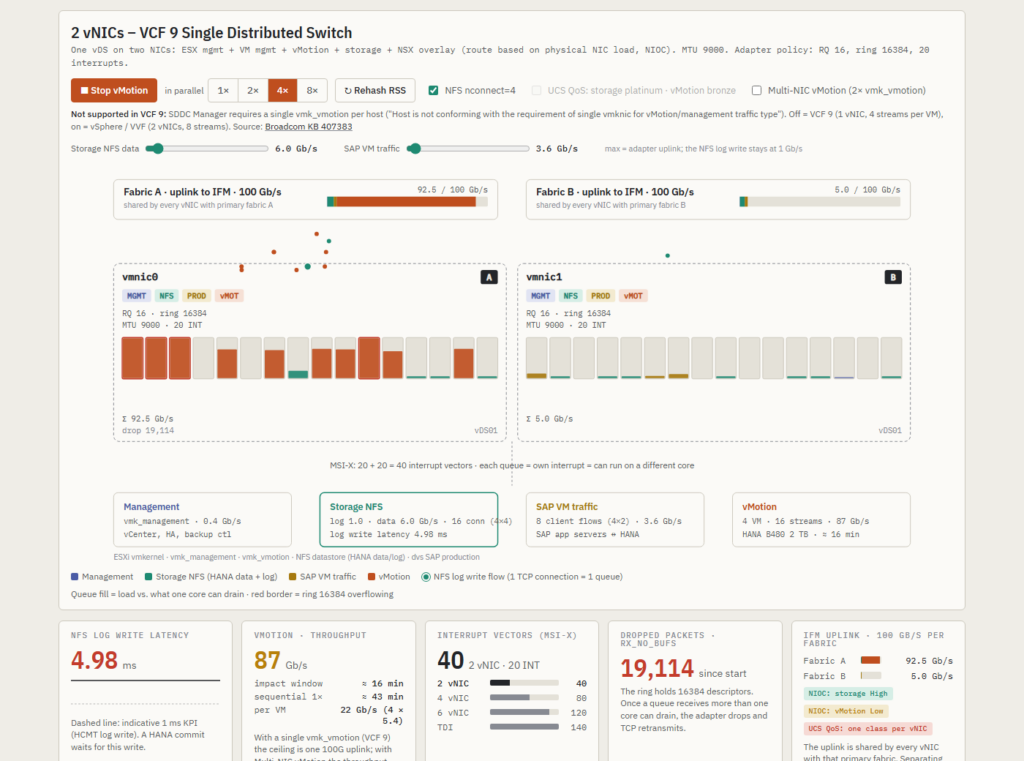
One vDS, everything on two uplinks, NIOC with storage and VMs at High and vMotion at Low, MTU 9000. It is the simplest model to run and the worst one for HANA. All four traffic classes hash into the same queues of the same vNIC. NIOC holds vMotion at the uplink limit, the queue collision remains.

VCF 9 Single Distributed Switch model with 2 vNICs: vMotion streams overflow the receive queues shared with the NFS log
2 vNICs, four migrations. All 16 vMotion streams enter through vmnic0, they sit in the same queues as the NFS log and the 16 data connections, the rings overflow and the log write is at 2.4 ms.

4 NICs: Workload Separation

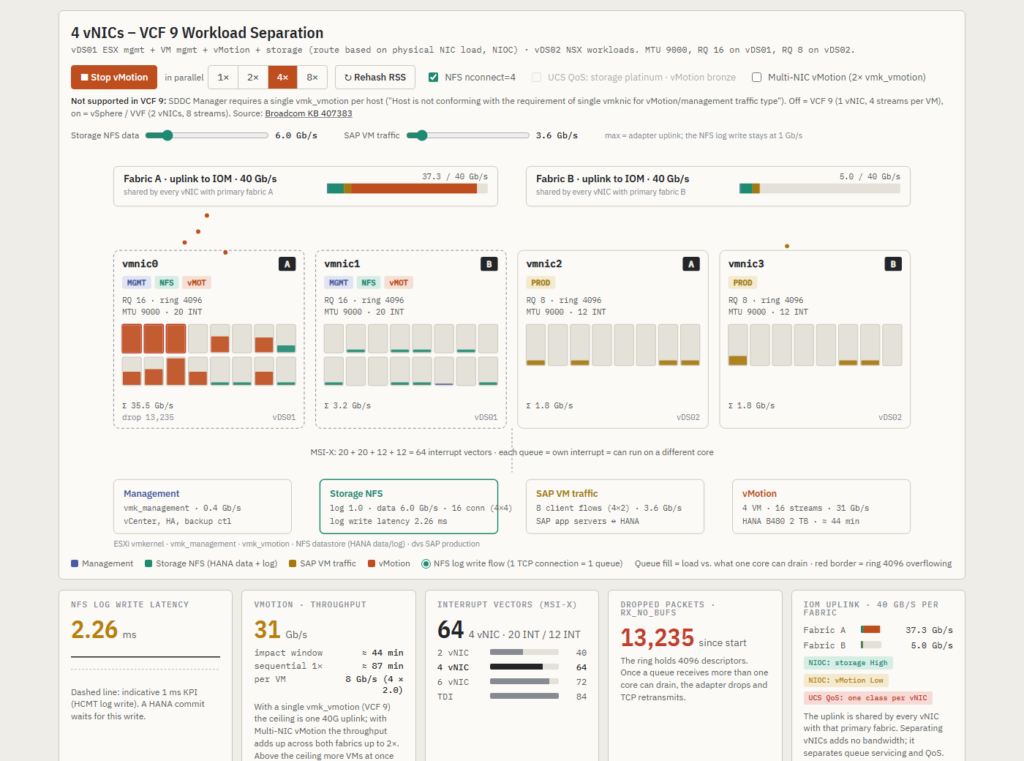
Two vDS. The NSX workloads get their own pair, which is good for the VMs. Management, vMotion and storage still share vDS01, so for the HANA log it changes almost nothing. The numbers are within hash luck of the 2‑NIC model. Note the greyed out QoS switch in the screenshot: UCS assigns a QoS class per vNIC, so storage and vMotion on one vNIC cannot be told apart on the uplink either.

VCF 9 Workload Separation model with 4 vNICs: vMotion and NFS log traffic share the same receive queues on vDS01
4 vNICs, four migrations. vDS02 is quiet, vDS01 carries vMotion and the NFS log in the same queues.

4 NICs the other way: Storage Separation

The Design Library also has a 4‑NIC Storage Separation Distributed Switch Model. It uses the same two vDS as Workload Separation but splits them differently: one vDS is dedicated to storage, and the other carries everything else (management, vMotion and workloads). The Design Library lists it for NFS as well as vSAN, so it is a valid option for NetApp NFS datastores. I did not simulate this layout, so it has no row in the table. By the mechanism described above, it protects the HANA log write the way the 6‑NIC model does, because the storage vNICs never receive vMotion packets. It is still not the layout I recommend for HANA. The SAP application server traffic on the NSX segments now shares a vDS, its uplinks and its receive queues with vMotion, so every host evacuation affects the client path instead of the log. If a host has only four ports, Storage Separation is the better of the two 4‑NIC models, but plan for six.

6 NICs: Storage and Workload Separation

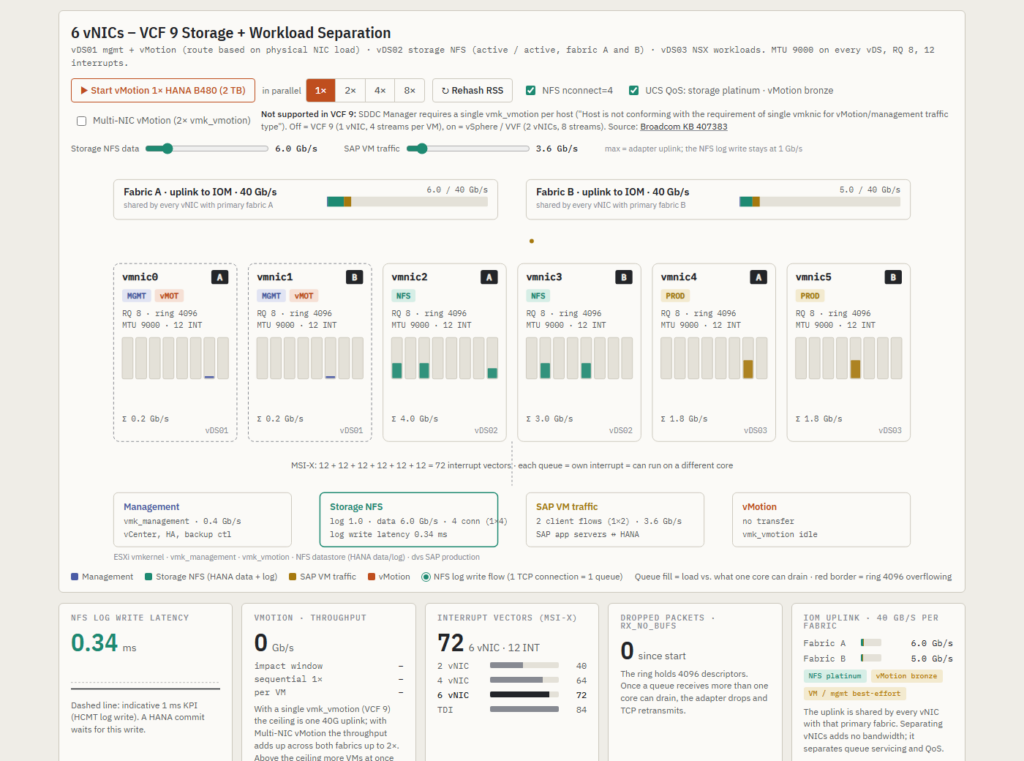
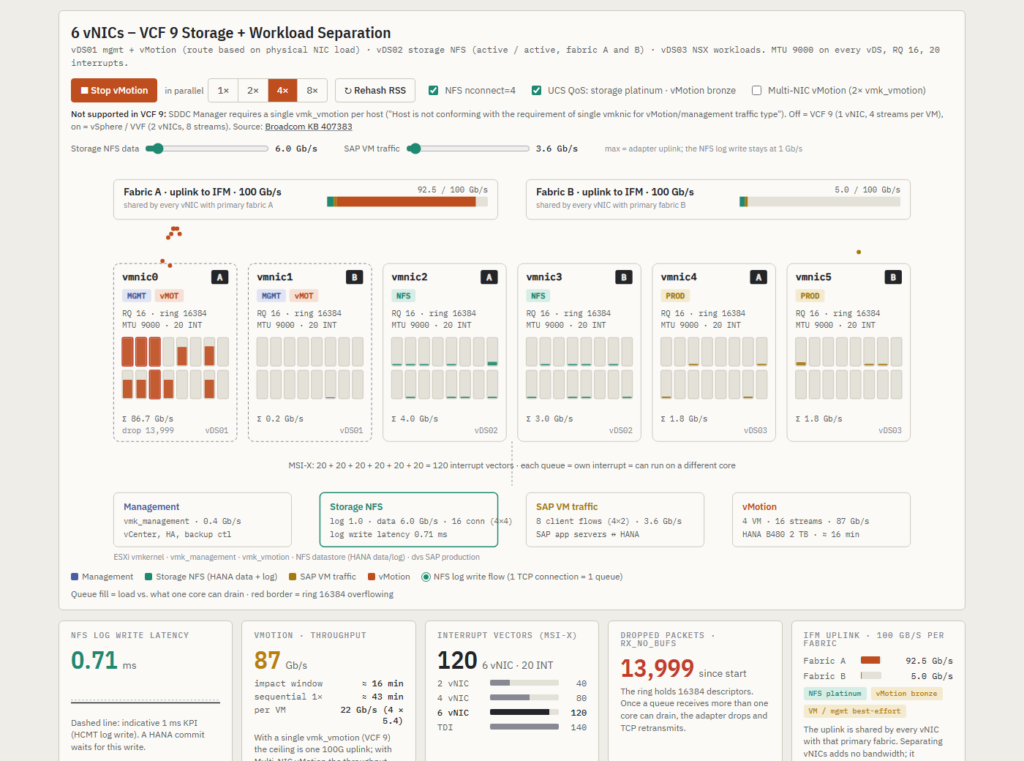
Three vDS on three NIC pairs. vDS01 carries management and vMotion, vDS02 carries storage on both uplinks active/active, vDS03 carries the NSX workloads. Storage now has its own pair of vNICs on both fabrics, its own queues and cores and its own UCS QoS class. vMotion shares a pair only with management, which is negligible traffic. The log write stays under 1 ms with eight parallel migrations. What moves the number from 0.35 to about 0.9 ms is not vMotion at all, it is the 32 NFS data connections of eight databases sharing 16 queues with the log flow. This is the layout I would make the baseline for any VCF 9 cluster that hosts HANA.

VCF 9 Storage and Workload Separation model at idle: NFS log and data connections spread over vmnic2 and vmnic3
6 vNICs at idle with one HANA VM. The NFS log and the four data connections spread over vmnic2 and vmnic3, so storage has 16 queues on two fabrics and nothing else in them.

7 NICs: FlexPod SAP HANA TDI

The Cisco CVD layout goes one step further and gives management its own vNIC as well, and it runs vMotion with two VMkernel adapters on two vNICs. A 2 TB VM then migrates in about 11 minutes instead of 22. For the HANA log it behaves like the 6‑NIC layout, because the storage vNICs are separate either way. If you build on FlexPod without VCF, use it. If you build on VCF 9, the 6‑NIC model gets you the same protection for HANA with one vNIC template less.

FlexPod SAP HANA TDI layout with 7 vNICs and Multi-NIC vMotion across both fabrics
7 vNICs per the FlexPod CVD, four migrations with Multi‑NIC vMotion. The streams spread over vmnic1 and vmnic2 on both fabrics, the storage vNICs carry only NFS.

QoS and NIOC are two different things

Separate vNICs alone are not enough. The uplink is still shared, and four parallel migrations will fill it. With a UCS QoS policy that puts the storage vNIC in the platinum class and vMotion in bronze, storage keeps its bandwidth and the log stays under 1 ms. Without it, vMotion takes the whole uplink and even the TDI layout ends up above 4 ms.

FlexPod TDI layout with eight vMotions and UCS QoS disabled: the shared uplink raises NFS log latency
The same TDI layout, eight migrations, QoS off. The queues are still isolated, the uplink is not.

The reverse holds as well. NIOC on the 2 and 4‑NIC models does protect bandwidth, and the model gives it credit for that, but it cannot protect queues. You need both: a vNIC of its own for storage, and a QoS class of its own on the uplink.

Multi-NIC vMotion is currently not supported by VCF 9.x SDDC Manager workflows

On plain vSphere you would give vMotion two VMkernel adapters on two uplinks, so a migration can use both fabrics. vSphere and VVF support Multi-NIC vMotion, but VCF 9.x SDDC Manager requires exactly one VMkernel adapter tagged for vMotion per host. When a host has a second one, SDDC Manager flags it after an inventory sync with the message “Host is not conforming with the requirement of single vmknic for vMotion/management traffic type”. The fix is to remove the second adapter and re-run host commissioning. Broadcom KB 407383 describes the issue. It notes that hosts with multiple vMotion adapters reach far lower vMotion concurrency in VCF 9.x than in vSphere 8.x, and that Load-based Teaming on the single vMotion VMkernel adapter is the exception to that limit.

For HANA hosts this has two consequences. A single migration gets only half the stream helpers and one 40 Gb/s path, about 16 Gb/s in the model, so a 2 TB VM takes about 22 minutes instead of 11. And on the 2 and 4‑NIC layouts every one of those streams enters through the single vNIC that also carries the NFS log, which is why the table above shows the KPI broken from the first migration. The simulator has a Multi‑NIC vMotion switch so you can compare both cases. It is off by default because that is what VCF 9 gives you.

Parallel vMotion during maintenance

vSphere allows up to eight concurrent vMotions per host. With one vMotion adapter on a 40 Gb/s uplink, one 2 TB HANA VM uses about 16 Gb/s and takes about 22 minutes. Two in parallel fill the uplink at about 31 Gb/s and still finish in about 22 minutes, so the second one is free. From there on more parallelism buys nothing: four VMs take about 44 minutes and eight about 89 minutes, the same as running them two at a time. What grows is the impact window on the shared layouts, because every additional VM puts more vMotion streams into the queues the log flow lives in. When you evacuate a host with HANA VMs on VCF 9, two at a time is the sensible limit.

Does a faster adapter fix it?

The first question I got after showing the model was whether a 100 Gb/s adapter makes the discussion go away. The simulator now has three adapters to switch between: the Cisco VIC 1380 with 2 × 40 Gb/s, the Cisco VIC 15231 with 2 × 100 Gb/s and 16 receive queues per vNIC, and the HPE Synergy 6310C with 2 × 50 Gb/s. The table shows the 2 vNIC and 6 vNIC layouts on each, single vMotion adapter, UCS or NIOC bandwidth protection on.

AdapterLayoutIdle1× vMotion4× vMotion8× vMotion2 TB VM, one migration
Cisco VIC 1380 · 2 × 40G · RQ 82 vNIC0.34 ms1.82 ms2.37 ms3.49 ms16 Gb/s · ≈ 22 min
6 vNIC0.34 ms0.35 ms0.88 ms0.83 ms
Cisco VIC 15231 · 2 × 100G · RQ 162 vNIC0.27 ms1.74 ms4.98 ms3.42 ms32 Gb/s · ≈ 11 min
6 vNIC0.27 ms0.27 ms0.71 ms0.71 ms
HPE Synergy 6310C · 2 × 50G · RSS 42 vNIC1.81 ms3.92 ms18.44 ms40.17 ms16 Gb/s · ≈ 22 min
6 vNIC0.34 ms0.34 ms0.87 ms0.87 ms

The VIC 15231 halves the migration time and the wider ring drops far fewer packets, but on the 2 vNIC layout the log write still sits well above the KPI from the first migration. Bandwidth was never the only problem. The vMotion streams still land in the same queues and on the same cores as the log flow, and at 8 Gb/s per stream they fill a core faster than before. On the 6 vNIC layout the 15231 is better in every column, and the 16 storage queues per vNIC are exactly what the 32 NFS connections of eight databases need.

Cisco VIC 15231 with 2 vNICs: vMotion still shares receive queues with the NFS log flow
2 vNICs on a VIC 15231, four migrations. Sixteen queues, a ring of 16384 and a 100G uplink. The vMotion streams still share queues with the NFS log flow, log write at 5.0 ms.
Cisco VIC 15231 with 6 vNICs: four vMotions at 87 Gb/s with the storage vNICs untouched
6 vNICs on a VIC 15231, four migrations at 87 Gb/s. The storage vNICs are untouched and the impact window shrinks to about 16 minutes.

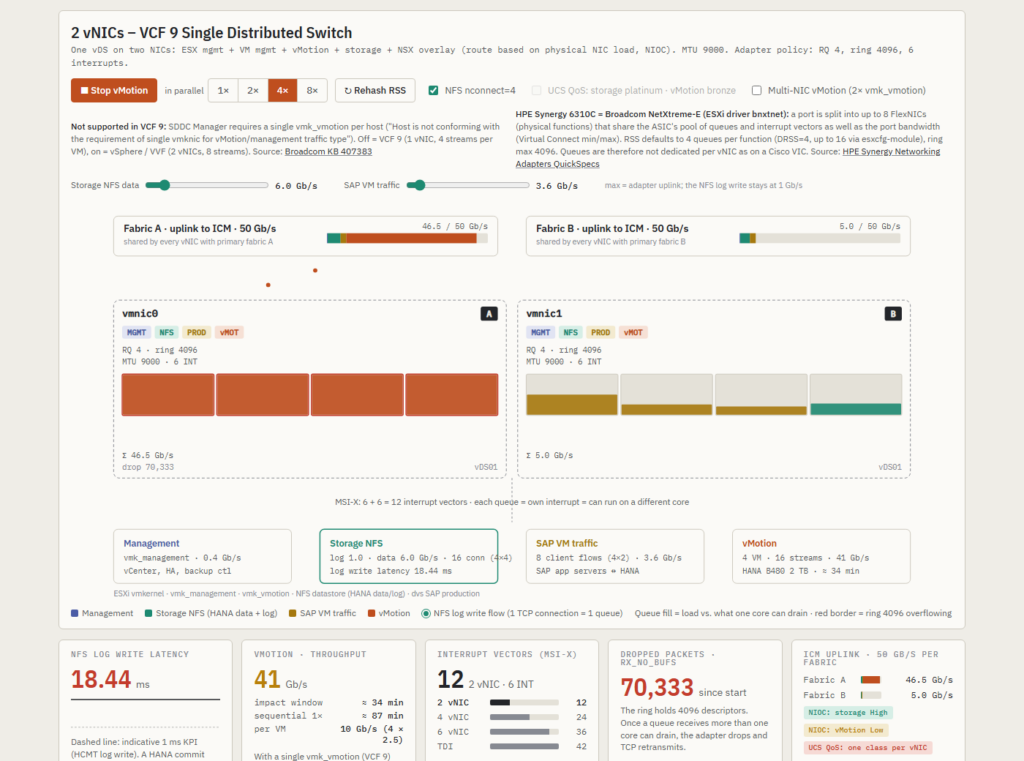
The Synergy 6310C is the other direction. With four RSS queues per FlexNIC, the 2 vNIC layout is above the KPI before any vMotion starts: the log flow of a single HANA VM already shares its queue with NFS data and client traffic. Every migration then lands in the same four queues, and at four and eight migrations the model’s latency formula runs off the scale, so take the direction from those cells and not the digits. The 6 vNIC layout still protects the log, because the storage FlexNIC never sees vMotion packets, but the headroom is smaller than on either VIC. If you run HANA on Synergy, raise the RSS queue count of the storage function from the default and give storage its own FlexNIC pair in Virtual Connect with a bandwidth minimum.

HPE Synergy 6310C with 2 vNICs: four RSS queues per FlexNIC carry vMotion next to the NFS flows
2 vNICs on a Synergy 6310C, four migrations. Four queues per FlexNIC, every one of them carries vMotion next to the NFS flows, and the log write is at 18.4 ms in the model.

Lifecycle note for the VIC 1380: Broadcom KB 391170 lists the UCS VIC 1340 and VIC 1380 as Restricted in ESX 9.0, under both nenic and nfnic. They still work on 9.0 and stay listed in the compatibility guide, but they get no new features or driver enhancements and only best-effort fixes, and Restricted devices are removed in the next major release. The VIC 15231 isn’t in either the Restricted or the End of Life list. If you are planning new HANA hosts for VCF 9, start from the 15231, and check your exact adapter and firmware in the Broadcom Compatibility Guide. The full list is on ESXi 9.0 – Deprecated and unsupported devices.

What I recommend

  • For HANA hosts on VCF 9, use the 6‑NIC Storage and Workload Separation model. If a host has only four ports, Storage Separation is better than Workload Separation because it keeps the NFS log away from vMotion, but SAP client traffic then shares the path with vMotion, so plan for six. On FlexPod without VCF, keep the 7‑vNIC TDI layout from the CVD.
  • Put the storage vNICs in a platinum QoS class in UCS and vMotion in bronze. NIOC is not a substitute on the uplink, and it is no help at all in the queues.
  • Do not buy a faster adapter to avoid the layout decision. A VIC 15231 shortens the maintenance window, it does not separate the queues. Where it does pay off is the storage vNIC: 16 queues for the NFS connections of many databases on one host.
  • Mount HANA data and log with nconnect, or with several mounts. One TCP connection is one queue and one core. Count the connections: eight databases with nconnect=4 are 32 data connections plus their log flows on the storage vNIC.
  • Limit concurrent HANA vMotions per host to two during maintenance windows. With the single vMotion adapter VCF 9 allows, two migrations fill the uplink and a third one only stretches the window.
  • Run HCMT at idle and during a vMotion of one and two HANA VMs, and keep the result as a baseline. On a performance ticket SAP and Broadcom ask about deviations from best practice first.
  • Watch rx_no_bufs on the storage vNICs. If the counter increases during the test, the receive ring is being exhausted. Correlate this with per-queue statistics and traffic load before attributing the drops to RSS/queue contention.

Try it yourself

The interactive model is on this site: vdan.cz/vcf9-sap-hana-tdi-design. You can switch between the four layouts and the three adapters, set one to eight HANA VMs and migrate them in parallel, toggle the UCS QoS policy, nconnect and Multi‑NIC vMotion, move the NFS data and SAP client traffic sliders up to the adapter’s line rate, and re‑roll the RSS hash to see how much of the effect is luck. The numbers update live, including the log write latency, the number of NFS and client connections per layout, the interrupt vector count and the dropped packets on the rings. It is available in Czech and English.

A word on the model: queue capacity, stream rates and the latency formula are illustrative and documented on the page. They are there to explain why the layouts behave differently, not to replace a measurement on your own hardware.

Related on vdan.cz

Sources

Microsoft Secure Boot Certificate Expiration in vSphere VMs (KB 423893): What to Do in 2026

Microsoft KEK and UEFI CA 2011 expired in June 2026. What it means for vSphere VMs with Secure Boot, and how SilentPK (8.0 U3j) and Capsule PK (9.1.1) fix it.

The Microsoft KEK CA 2011 and UEFI CA 2011 certificates expired in June 2026, and Windows Production PCA 2011 expires in October 2026. vSphere VMs with UEFI Secure Boot keep booting, but VMs without the Microsoft 2023 certificates can’t take future Secure Boot database updates. The fix is two steps: update the VM’s Platform Key (PK) first, using SilentPK on ESXi 8.0 U3j (P09) and later or Capsule PK on ESX 9.1.1.0 for Windows VMs with vTPM, then update KEK and DB through the guest OS vendor. Broadcom KB 423893 is the source of truth and was last updated on 2 September 2026.

Which Microsoft certificates expire, and when

CertificateExpires
Microsoft Corporation KEK CA 2011June 2026
Microsoft Corporation UEFI CA 2011June 2026
Microsoft Windows Production PCA 2011October 2026

What happens to VMs after the certificates expire

The VMs continue to boot. The impact is that a VM whose KEK and DB don’t contain the Microsoft 2023 certificates can’t apply future Secure Boot database updates, which can block Secure Boot-related security updates in the guest. Guest OS updates that don’t depend on these databases keep working.

Which VMs are affected

  • VM hardware version 13 or newer (Secure Boot starts at version 13)
  • UEFI Secure Boot enabled
  • KEK and DB without the Microsoft 2023 certificates: typically VMs on hardware version 13, VMs created on ESXi hosts earlier than 8.0 U2, or VMs deployed from templates that carry an old NVRAM

VMs on hardware version 13 need an upgrade to version 14 or later before their PK can be updated.

How to find affected VMs

  • Fleet-wide: KB 423893 attaches PowerCLI scripts (SecureBootExportVMList.ps1, SecureBootExportVMListv2.ps1) that export Secure Boot and vTPM status for all VMs.
  • Inside a Windows guest: Get-SecureBootUEFI -Name PK
  • Inside a Linux guest: mokutil --pk
  • vCenter and ESX 9.1.1.0: the alarm “Virtual Machine UEFI Secure Boot Platform Key is out of date. Refer KB 423893” flags affected VMs.

Remediation by ESXi version: 8.0 U3j (P09), 9.0 and 9.1.1

Secure BootvTPMESX 7.x, ESXi 8.0 U3i (P08) and earlierESXi 8.0 U3j (P09)ESX 9.0.x / 9.1.0ESX 9.1.1.0 and later
DisabledDisabledNo actionSilentPK update (optional)SilentPK update (optional)SilentPK update (optional)
EnabledDisabledManual update from the vUEFI interfaceSilentPK updateSilentPK updateSilentPK update
EnabledEnabledManual update from the vUEFI interfaceManual update from VMX configuration (preferred for non-Windows VMs)Manual update from VMX configuration (non-Windows VMs)Capsule PK update (Windows) / manual VMX update (non-Windows)
DisabledEnabledNo actionNo actionNo actionNo action

Source: KB 423893, as of its 2 September 2026 update. ESX 7.x gets only the manual vUEFI method; no automated fix is planned for it.

SilentPK vs Capsule PK

  • SilentPK update (ESXi 8.0 U3j and later): the hypervisor adds the missing Windows OEM Devices PK certificate automatically during a guest reboot or VM power cycle. No guest OS action is needed. It is used for VMs without vTPM.
  • Capsule PK update (ESX 9.1.1.0 and later, Windows): an OS-coordinated firmware update that changes the PK during a guest reboot while preserving vTPM measurements, so BitLocker and other vTPM-dependent features don’t lock you out. It requires VMware Tools 13.1.5 or later and the July 2026 Windows cumulative update (earlier for Windows Server 2025 and Windows 11 24H2/25H2).

The order that matters

  1. Patch hosts to ESXi 8.0 U3j (P09), or to ESX 9.1.1.0 if you have Windows VMs with vTPM.
  2. Update the Platform Key first, with SilentPK, Capsule PK or the manual method from the table.
  3. Then update KEK and DB following the guest OS vendor’s guidance.

Related: this article is about guest (VM) Secure Boot. For host-level Secure Boot on Cisco UCS, see how to run the Secure Boot validation script on an ESXi host.

“STS Signing Certificates are about to expire”: vCenter STS Certificate Guide (7, 8, 9)

vCenter alarm “STS Signing Certificates are about to expire”? Check the STS certificate, renew it in vSphere Client or vCert, avoid No Healthy Upstream.

Short answer: the vCenter alarm “STS Signing Certificates are about to expire” means the Security Token Service signing certificate, which signs every vCenter SSO token, is within 90 days of expiry. Renew it before it lapses: in the vSphere Client (Administration → Certificate Management → STS signing certificate → Refresh with vCenter certificate) while vCenter still works, or with vCert over SSH if it doesn’t. An expired STS certificate breaks logins and can cause No healthy upstream.

Certificates in vCenter are usually associated with Machine SSL, Solution Users, or trusted roots. However, there is another certificate that can have a very large operational impact: the Security Token Service signing certificate, commonly known as the STS signing certificate.

The STS certificate is not the certificate you see in your browser when opening the vSphere Client. It is part of the vCenter Single Sign-On authentication flow. When a user or internal service authenticates, STS validates the primary credentials and issues a SAML token containing user or service attributes. That token is then used by vCenter services to trust the authenticated identity.

In short: if STS cannot issue valid tokens, vCenter authentication starts to break.

Broadcom describes the STS certificate as critical for vSphere SSO because it is responsible for issuing, validating, and renewing security tokens.


What is the STS signing certificate?

The Security Token Service is part of vCenter Single Sign-On. Its job is to issue signed SAML tokens after successful authentication.

By default, the VMware Certificate Authority, or VMCA, generates the STS signing certificate. In most environments, the default VMCA-issued STS certificate is sufficient. A fresh installation of vSphere 7.0 Update 1 or later creates an STS signing certificate valid for 10 years, while KB 318968 describes a lifetime of around two years in its replacement scenarios, so check the actual date on your system rather than assume. You can refresh it with a new VMCA-issued certificate, or import a custom / third-party STS signing certificate if your company security policy requires all certificates to be replaced.

However, replacing the STS certificate should not be treated as a routine cosmetic change. Broadcom specifically warns that refreshing the STS certificate with a vCenter-issued certificate can replace third-party/custom certificates and may take the environment out of compliance if custom certificates are required.


Why does STS expiration matter?

When the STS signing certificate expires, vCenter may no longer be able to issue valid SAML tokens. This affects both users and internal solution users.

The result can be severe:

  • vSphere Client login failures
  • vCenter services failing to start after reboot
  • vmware-stsd service not starting
  • vpxd authorization errors
  • Signing certificate is not valid
  • No Healthy Upstream
  • failures in Enhanced Linked Mode environments
  • problems exporting OVF templates
  • certificate replacement workflows failing because authentication itself is broken

Broadcom’s KB for "Signing certificate is not valid" or "No healthy upstream" explains that these issues occur when the STS certificate or its signing root certificate has expired, preventing internal services and solution users from acquiring valid tokens.

This is why an STS certificate problem can look much bigger than a normal certificate warning. It can make the entire vCenter feel broken.


Typical symptoms

If the STS certificate is already expired, you may see errors such as:

HTTP Status 400 – Bad Request
Signing certificate is not valid
Cannot connect to vCenter Single Sign-On server
https://VC_FQDN/sts/STSService/vsphere.local
503 Service Unavailable
No Healthy Upstream

You may also see service startup failures after reboot. Broadcom notes that an expired STS certificate can prevent the vmware-stsd service from starting, which then causes dependent vCenter services to fail as well.


The warning: “STS Signing Certificates are about to expire”

In newer vCenter versions, you may receive the following alarm in the vSphere UI:

STS Signing Certificates are about to expire

This alarm means that the STS certificate for the vCenter Server Appliance is nearing expiration. Broadcom states that if the STS signing certificates expire without being replaced, vCenter will no longer be functional.

That warning should not be ignored.

When the alarm fires, and why it says 90 days when vCert says 91

The alarm starts 90 days before expiry and repeats once a week, then daily from seven days before expiry (Broadcom TechDocs). It actually triggers 90.999 days before the expiration date, so the alarm can say “expires in 90 days” while vCert reports 91. That is expected behaviour, not a second problem (KB 429527).

VMware Security Token Service “Healthy with warnings”

If the VMware Security Token Service shows warnings in the service health view or triggers a health alarm, two documented causes are worth checking:

  • The STS signing certificate is close to expiry. Check its Valid until date as described below and renew it.
  • The appliance is short on memory. During workload spikes the STS Java process can fail to allocate memory, exit with code 143 and be restarted by vMon, so its health briefly turns red and then green again. The SSO log directory then contains hs_err_sts_pid<PID>.log files. One-off events can be ignored; if it keeps happening, add RAM to the VCSA (KB 433542).

How to check the STS certificate

For vCenter 7.0 Update 2 and later, the STS certificate can be checked from the vSphere Client:

vSphere Client
→ Administration
→ Certificates
→ Certificate Management
→ STS signing certificate

The UI shows the Valid until date, certificate status, and certificate chain details. Broadcom recommends checking the STS certificate periodically, because the general certificate expiry alarm does not account for the STS certificate in the same way.

checksts.py is deprecated: use vCert instead

For command-line or advanced checks, Broadcom now recommends using vCert instead of the older checksts.py script. The checksts.py script is deprecated, and vCert is the current recommended tool for certificate management and replacement workflows.


Recommended tool: vCert

Broadcom provides vCert.py, a menu-driven tool for certificate management on vCenter Server 7.0, 8.0, and 9.0. Its purpose is to simplify certificate replacement when certificates expire or are about to expire.

Basic usage:

unzip -q vCert-<version>.zip
cd vCert-<version>
chmod +x vCert.py
./vCert.py

Useful menu paths:

2. View certificate info
→ 8. STS signing certificates
3. Manage certificates
→ 8. STS signing certificates

Broadcom’s KB also states that vCert creates logs under:

/var/log/vmware/vCert

and uses a working directory under:

/root/vCert-master

for staging and backups.


Replacing or refreshing the STS certificate before it expires

If the STS certificate is still valid and the vSphere Client is accessible, the preferred approach is usually to refresh it from the UI.

Path:

vSphere Client
→ Administration
→ Certificate Management
→ STS signing certificate
→ Actions
→ Refresh with vCenter certificate

Broadcom marks Refresh with vCenter certificate as the recommended UI option. It generates a new VMCA-issued STS certificate. In vSphere 8.0 and later, refreshing or replacing the STS signing certificate no longer requires a vCenter restart (TechDocs).

There is also an Import and Replace Certificate option for custom or third-party certificates. Use this only when required by your company security policy.

Important: Before making certificate changes, create proper offline snapshots of all vCenter Server appliances in the environment. In Enhanced Linked Mode, this means all vCenter / PSC nodes in the same SSO domain. Broadcom explicitly recommends snapshots before STS certificate replacement operations.


What if vCenter is already broken?

If the STS certificate has already expired, the vSphere Client may not be usable. You may be stuck with:

No Healthy Upstream

or:

Signing certificate is not valid

In that case, use vCert directly on the VCSA via SSH. Broadcom recommends vCert for checking and replacing STS signing certificates when vCenter is inaccessible.

The high-level recovery flow is:

1. Take offline snapshot / backup.
2. SSH to VCSA as root.
3. Upload and extract vCert.
4. Run ./vCert.py.
5. Check STS signing certificate.
6. Replace STS signing certificate.
7. Restart services if required.
8. Validate vSphere Client login.

Never skip the snapshot step. Certificate repair can make the situation worse if performed incorrectly.


Important note for vSphere 8

In vSphere 8.0, vCenter Single Sign-On can automatically renew a VMCA-generated STS signing certificate before it expires. However, Broadcom has documented rare cases where an STS refresh happening during long-running vSphere Lifecycle Manager operations can cause task failures due to cached STS certificate data.

So even with automatic renewal, it is still useful to know where the STS certificate is, how to check it, and how it affects authentication.


Best practices

My practical checklist:

1. Check STS certificate validity regularly.
2. Do not wait until the last week before expiration.
3. Replace if the certificate expires within 6 months.
4. Use vSphere Client if vCenter is still healthy.
5. Use vCert if vCenter login or services are already broken.
6. Take offline snapshots before any certificate operation.
7. In ELM, snapshot all vCenter/PSC nodes in the SSO domain.
8. Be careful with custom/third-party STS certificates.
9. Document the certificate state before and after replacement.
10. Validate vCenter login, service health, and integrations after replacement.

Broadcom recommends replacing the STS certificate if it is set to expire within six months. If expiration is more than six months away, schedule the replacement for an appropriate maintenance window.


Summary

The STS signing certificate is easy to overlook because it is not the browser-facing Machine SSL certificate. But it is one of the most important certificates in vCenter authentication.

When it expires, the impact can be dramatic: broken SSO, failed service startup, Signing certificate is not valid, and even No Healthy Upstream.

The key lesson is simple:

Do not wait for STS expiration to become an outage. Check it, plan it, snapshot first, and use the supported Broadcom workflows.

Not the same certificate: the STS signing certificate is different from the STS service’s TLS certificate on port 3128. If vCert reports STS_INTERNAL_SSL_CERT as LEGACY, or a scanner flags an old certificate on 3128 after you renewed Machine SSL, see STS_INTERNAL_SSL_CERT Explained: What vCert’s LEGACY Result Means. For which certificates vCenter now renews on its own, see vCenter Certificate Auto-Renewal: When You Still Need vCert.

Related vCenter certificate guides


References

  • Broadcom KB 318197 — "STS Signing Certificates are about to expire" alert received in vSphere UI
  • Broadcom KB 316619 — "Signing certificate is not valid" or "No healthy upstream" error in vCenter Server Appliance
  • Broadcom KB 385107 — vCert - Scripted vCenter expired certificate replacement
  • Broadcom KB 318968 — Checking the STS certificate expiration and replacing expired STS certificates on vCenter Servers
  • Broadcom KB 423367 — How to Export the STS Certificate from vCenter Server
  • Broadcom KB 429527 – The alarm "STS Signing Certificates are about to expire" is issued but it actually expires in 91 days
  • Broadcom KB 433542 – sts status changed from green to red alarm triggered in vCenter Server
  • Broadcom TechDocs – Managing the vCenter Security Token Service

VCF 9.x Upgrade Stuck on vRNI / Aria Operations for Networks SSL Thumbprint Validation

VCF 9.x upgrade keeps failing on the vRNI / Aria Operations for Networks thumbprint after a cert change? Clear the stale thumbprint cached in SDDC Manager.


During a VMware Cloud Foundation upgrade, you may hit a situation where the upgrade workflow fails on validation of the vRNI / Aria Operations for Networks certificate thumbprint.

Even after replacing the certificate directly on the vRNI appliance, clicking Retry in SDDC Manager may continue to fail with the old certificate thumbprint.

This can be confusing because the certificate on the vRNI side is already correct, but SDDC Manager still validates against the previous thumbprint.

Root Cause

The root cause is that SDDC Manager caches the SSL thumbprint either in its internal database, platformdb, or in the LCM / Domain Manager service memory when the upgrade task is first initialized.

As a result, even if the certificate is replaced on the vRNI / Aria Operations for Networks appliance, the Retry button does not automatically rediscover the new certificate thumbprint.

Instead, the retry operation may continue to use the old cached value.

To resolve this, the thumbprint stored in the SDDC Manager inventory database must be updated manually.

Warning:
This procedure modifies the internal SDDC Manager database. Use it only when you fully understand the impact. Always take a backup or snapshot of the SDDC Manager appliance before making manual database changes. In production environments, validate with VMware/Broadcom support first.


Step 1: Extract the New Certificate Thumbprint from vRNI

Log in to the SDDC Manager appliance via SSH.

Usually this means logging in as vcf and then switching to root:

su -

Now retrieve the SHA-256 fingerprint of the currently installed certificate on the vRNI / Aria Operations for Networks appliance:

echo -n | openssl s_client -connect <VRNI_FQDN_OR_IP>:443 2>/dev/null | openssl x509 -noout -fingerprint -sha256

Example output:

sha256 Fingerprint=XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX

Copy only the thumbprint value, without the prefix:

XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX

Step 2: Check the Current Thumbprint in SDDC Manager Database

Connect to the SDDC Manager PostgreSQL database:

psql -h localhost -U postgres -d platformdb

Now locate the vRNI / Aria Operations for Networks resource record:

SELECT id, type, status, ssl_thumbprint
FROM resource
WHERE type LIKE '%VRNI%'
OR type LIKE '%ARIA%';

Identify the row that belongs to your vRNI / Aria Operations for Networks appliance.

You should see that the ssl_thumbprint column still contains the old thumbprint, for example:

EF:0B:A2:15:...

Step 3: Update the Stored Thumbprint

Update the resource record with the new thumbprint:

UPDATE resource
SET ssl_thumbprint='<NEW_THUMBPRINT>'
WHERE id='<COMPONENT_ID>';

Example:

UPDATE resource
SET ssl_thumbprint='=XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX'
WHERE id='xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx';

Verify the change:

SELECT id, type, status, ssl_thumbprint
FROM resource
WHERE id='<COMPONENT_ID>';

Exit PostgreSQL:

\q

Step 4: Restart LCM and Domain Manager Services

SDDC Manager may still cache inventory data in memory, so restart the relevant services:

systemctl restart lcm
systemctl restart domainmanager

Wait a few minutes until the services are fully initialized.

You can monitor the LCM service log with:

tail -f /var/log/vmware/vcf/lcm/lcm.log

Step 5: Reset a Stuck Upgrade Task if Needed

In some cases, the upgrade task may remain stuck in an IN_PROGRESS state or the Retry button may stay unavailable.

If this happens, check the active execution tasks in the SDDC Manager database.

Connect again to PostgreSQL:

psql -h localhost -U postgres -d platformdb

Find tasks that are still marked as running:

SELECT id, status, action
FROM execution_task
WHERE status='IN_PROGRESS';

Identify the specific stuck task related to the failed upgrade validation.

Then manually mark it as failed:

UPDATE execution_task
SET status='FAILED'
WHERE id='<TASK_ID>';

Exit PostgreSQL:

\q

Step 6: Resume the Upgrade

Return to the SDDC Manager UI and refresh the upgrade page.

The upgrade workflow should now allow you to click Retry again.

This time, SDDC Manager should read the corrected thumbprint from the database, validate it against the current vRNI / Aria Operations for Networks certificate, and continue with the VCF 9.x upgrade.


Summary

If a VCF 9.x upgrade continues to fail on vRNI / Aria Operations for Networks certificate validation even after the certificate has been replaced, the issue may not be the certificate itself.

The problem can be caused by a stale SSL thumbprint cached in SDDC Manager.

The fix is to:

  1. Extract the new SHA-256 certificate thumbprint from vRNI.
  2. Update the corresponding ssl_thumbprint value in platformdb.
  3. Restart the lcm and domainmanager services.
  4. Reset the stuck execution task if required.
  5. Retry the upgrade from the SDDC Manager UI.

This is a useful recovery procedure when the UI retry mechanism continues to use stale inventory data instead of the actual certificate currently installed on the vRNI appliance.