VCF 9 SAP HANA Network Design: Why 6 NICs Matter for vMotion and NFS

SAP HANA on VCF 9 with NFS: why storage needs its own NICs, separate from vMotion. The 2, 4 and 6 NIC models compared on Cisco VIC and HPE Synergy.

Short answer: on VCF 9 hosts that run SAP HANA on NFS, give storage its own pair of physical NICs (vNICs on Cisco UCS), separate from vMotion. The VCF 9.1 Design Library’s 6‑NIC Storage and Workload Separation model does this and also isolates NSX workloads, so I recommend it as the baseline. The 4‑NIC Storage Separation model also isolates NFS storage, but it puts SAP client traffic on the same switch as vMotion. The reason is host maintenance. A vMotion of a 2 TB HANA VM lands on the same receive queues as the NFS log writes of every HANA database on that host, unless storage has a vNIC of its own. HANA commits wait for those log writes. A faster adapter does not change that, and VCF 9 makes it worse by allowing only one vMotion VMkernel adapter per host. You can watch all of it happen in an interactive model: vdan.cz/vcf9-sap-hana-tdi-design.
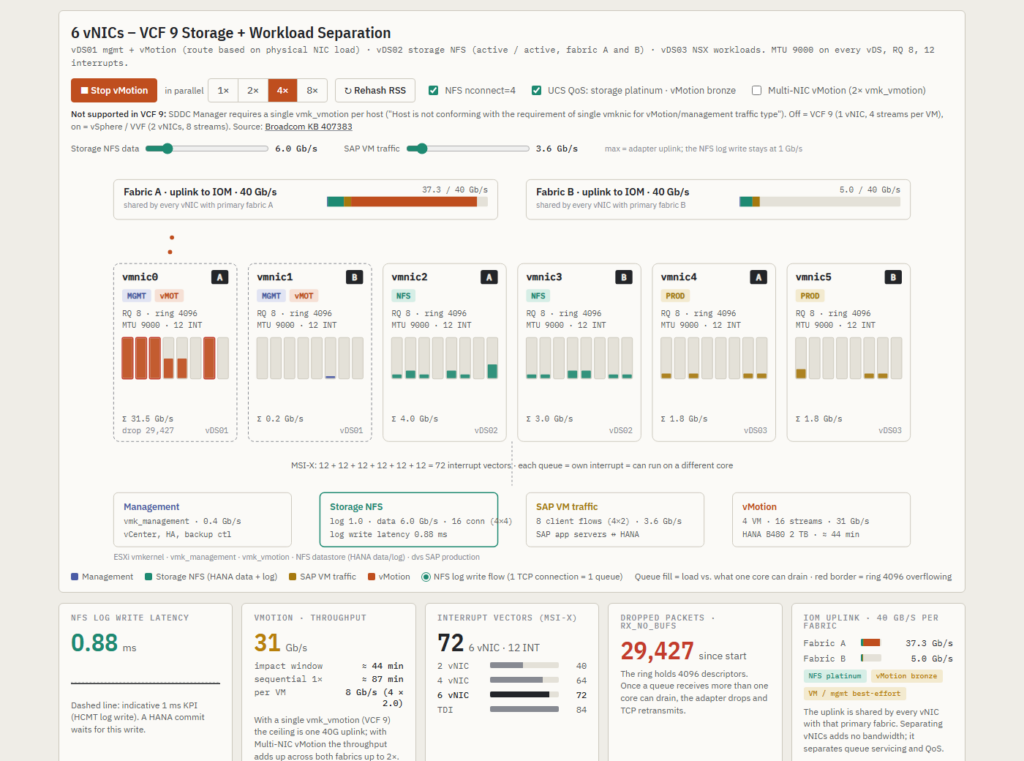
VCF 9 SAP HANA 6-NIC network model: four parallel vMotions on vmnic0 while the NFS log write on vDS02 stays under 1 ms
6 vNICs, four HANA VMs migrating at once. vMotion saturates vmnic0, the storage vNICs on vDS02 carry only the 16 NFS connections of those four VMs, and the log write stays under 1 ms.

Why vMotion is a HANA problem and not just a network problem

HANA writes its redo log synchronously. A transaction commit returns only after storage has acknowledged the log write, so log write latency turns directly into application response time. The SAP HCMT tool checks this, and the indicative KPI for log write latency is about 1 ms. Under normal load a well built NFS path delivers a few hundred microseconds.

Now migrate a HANA VM with 1 to 2 TB of RAM. On a 40 Gb/s uplink a vMotion runs at 16 to 35 Gb/s for 10 to 20 minutes, including the dirty page iterations at the end. If that traffic shares the network path with storage, the log write latency jumps from sub‑millisecond to several milliseconds, commits stall, and the application servers see timeouts. This is why SAP and the FlexPod CVD separate vMotion from storage in the first place. The interesting part is where the sharing happens, because it is not only bandwidth.

What happens inside the adapter

On a Cisco UCS blade with a VIC, every vNIC in the service profile gets its own set of receive queues. The adapter policy used in the FlexPod TDI design gives each vNIC on a VIC 1380 8 receive queues with a ring of 4096 descriptors and 12 MSI‑X interrupts. On a VIC 15231 the policy is 16 queues, a ring of up to 16384 and 20 interrupts. Three details matter:

  • The adapter spreads incoming flows across the queues with an RSS hash of IP addresses and ports. It does not know what a flow is. One NFS log connection always lands on exactly one queue.
  • Each queue has its own interrupt and is serviced by one CPU core. A queue that receives more than its core can drain fills its ring and the adapter drops packets. That shows up as rx_no_bufs in esxcli network nic stats.
  • Queues belong to the vNIC. Two vNICs on the same physical adapter never compete for queues or cores. They share only the uplink to the IOM or IFM, and that is where QoS can help.

So if vMotion streams and the NFS log flow arrive on the same vNIC, the hash will sooner or later put a vMotion stream on the queue that also carries the log write. Network I/O Control cannot see that. NIOC shares bandwidth between port groups on the uplink, it does not assign queues. Only a separate vNIC does.

One remark for readers on HPE Synergy. The Synergy 6310C is a Broadcom NetXtreme‑E adapter (ESXi driver bnxtnet). A port is split into up to eight FlexNICs that share the ASIC’s pool of queues and interrupt vectors, and RSS defaults to 4 queues per function. A FlexNIC is still a separate function with its own RSS, so the storage FlexNIC does not receive vMotion packets, but the queues behind it are not dedicated in the way a Cisco VIC vNIC’s are, and there are fewer of them. The model treats it that way and I come back to it below.

The four layouts

I modelled the three VCF 9.1 network models and the classic FlexPod TDI layout side by side. Same host, same VIC 1380 with 2 × 40 Gb/s, same traffic: NFS log 1 Gb/s, NFS data 6 Gb/s, SAP client traffic 3.6 Gb/s and management. Every HANA VM on the host mounts its data and log with nconnect, so it brings four NFS connections and two client flows of its own. The number of VMs is the parallel selector: with four VMs the storage class has 16 NFS data connections and the VM class 8 flows, with eight VMs 32 and 16. Then those one to eight HANA B480 VMs with 2 TB RAM are migrated at once. The VCF 9 rows use the single vMotion VMkernel adapter VCF 9 allows, the TDI row uses Multi‑NIC vMotion as the CVD configures it. The numbers are model output, not measurements. The model exists to show the mechanism.

LayoutvNICsStorage isolated from vMotionLog write · idle1× vMotion4× vMotion8× vMotion
VCF 9 Single Distributed Switch2no0.34 ms1.82 ms2.37 ms3.49 ms
VCF 9 Workload Separation4no0.34 ms1.82 ms2.26 ms3.49 ms
VCF 9 Storage + Workload Separation6yes0.34 ms0.35 ms0.88 ms0.83 ms
FlexPod SAP HANA TDI (Multi‑NIC vMotion)7yes0.34 ms0.35 ms0.89 ms0.84 ms

The split is clean. The two layouts that put vMotion and storage on the same vNIC cross the 1 ms KPI with a single migration. The two that give storage its own vNIC stay under it with eight. What remains in the 6 and 7 vNIC rows has two parts: uplink pressure, which is what the UCS QoS policy is for, and the fact that eight VMs bring 32 NFS data connections into the 16 storage queues, so the log flow starts sharing a queue with data connections of other databases. That second part is the argument for more queues on the storage vNIC, and I come back to it with the VIC 15231.

2 NICs: Single Distributed Switch

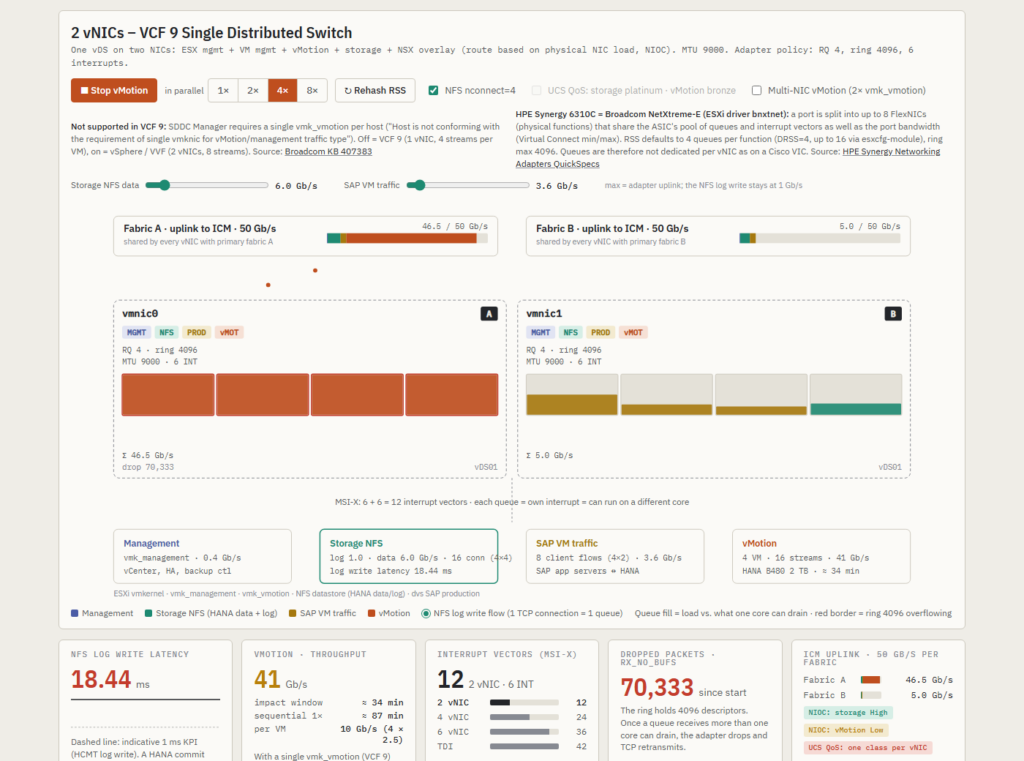
One vDS, everything on two uplinks, NIOC with storage and VMs at High and vMotion at Low, MTU 9000. It is the simplest model to run and the worst one for HANA. All four traffic classes hash into the same queues of the same vNIC. NIOC holds vMotion at the uplink limit, the queue collision remains.
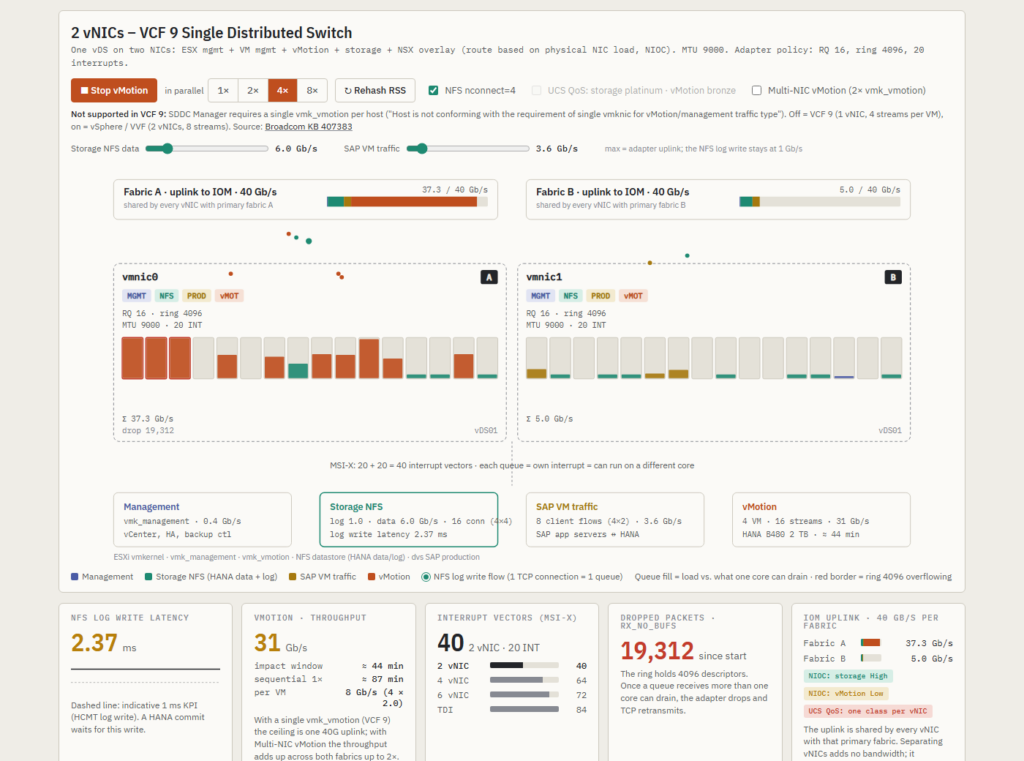
VCF 9 Single Distributed Switch model with 2 vNICs: vMotion streams overflow the receive queues shared with the NFS log
2 vNICs, four migrations. All 16 vMotion streams enter through vmnic0, they sit in the same queues as the NFS log and the 16 data connections, the rings overflow and the log write is at 2.4 ms.

4 NICs: Workload Separation

Two vDS. The NSX workloads get their own pair, which is good for the VMs. Management, vMotion and storage still share vDS01, so for the HANA log it changes almost nothing. The numbers are within hash luck of the 2‑NIC model. Note the greyed out QoS switch in the screenshot: UCS assigns a QoS class per vNIC, so storage and vMotion on one vNIC cannot be told apart on the uplink either.
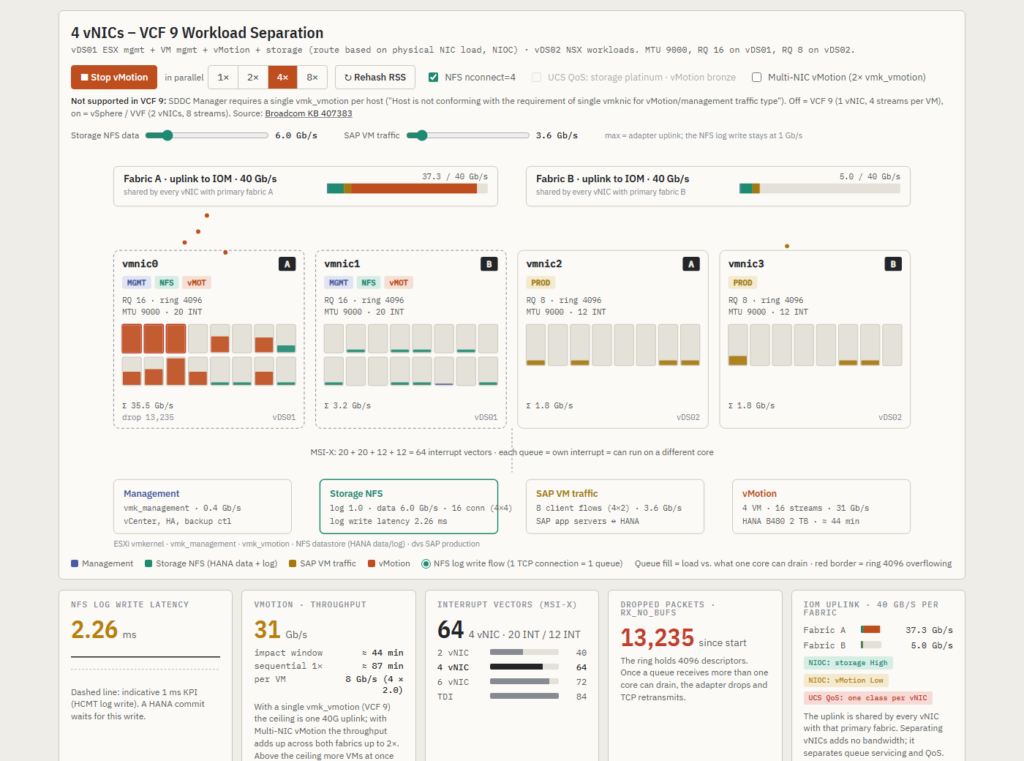
VCF 9 Workload Separation model with 4 vNICs: vMotion and NFS log traffic share the same receive queues on vDS01
4 vNICs, four migrations. vDS02 is quiet, vDS01 carries vMotion and the NFS log in the same queues.

4 NICs the other way: Storage Separation

The Design Library also has a 4‑NIC Storage Separation Distributed Switch Model. It uses the same two vDS as Workload Separation but splits them differently: one vDS is dedicated to storage, and the other carries everything else (management, vMotion and workloads). The Design Library lists it for NFS as well as vSAN, so it is a valid option for NetApp NFS datastores. I did not simulate this layout, so it has no row in the table. By the mechanism described above, it protects the HANA log write the way the 6‑NIC model does, because the storage vNICs never receive vMotion packets. It is still not the layout I recommend for HANA. The SAP application server traffic on the NSX segments now shares a vDS, its uplinks and its receive queues with vMotion, so every host evacuation affects the client path instead of the log. If a host has only four ports, Storage Separation is the better of the two 4‑NIC models, but plan for six.

6 NICs: Storage and Workload Separation

Three vDS on three NIC pairs. vDS01 carries management and vMotion, vDS02 carries storage on both uplinks active/active, vDS03 carries the NSX workloads. Storage now has its own pair of vNICs on both fabrics, its own queues and cores and its own UCS QoS class. vMotion shares a pair only with management, which is negligible traffic. The log write stays under 1 ms with eight parallel migrations. What moves the number from 0.35 to about 0.9 ms is not vMotion at all, it is the 32 NFS data connections of eight databases sharing 16 queues with the log flow. This is the layout I would make the baseline for any VCF 9 cluster that hosts HANA.
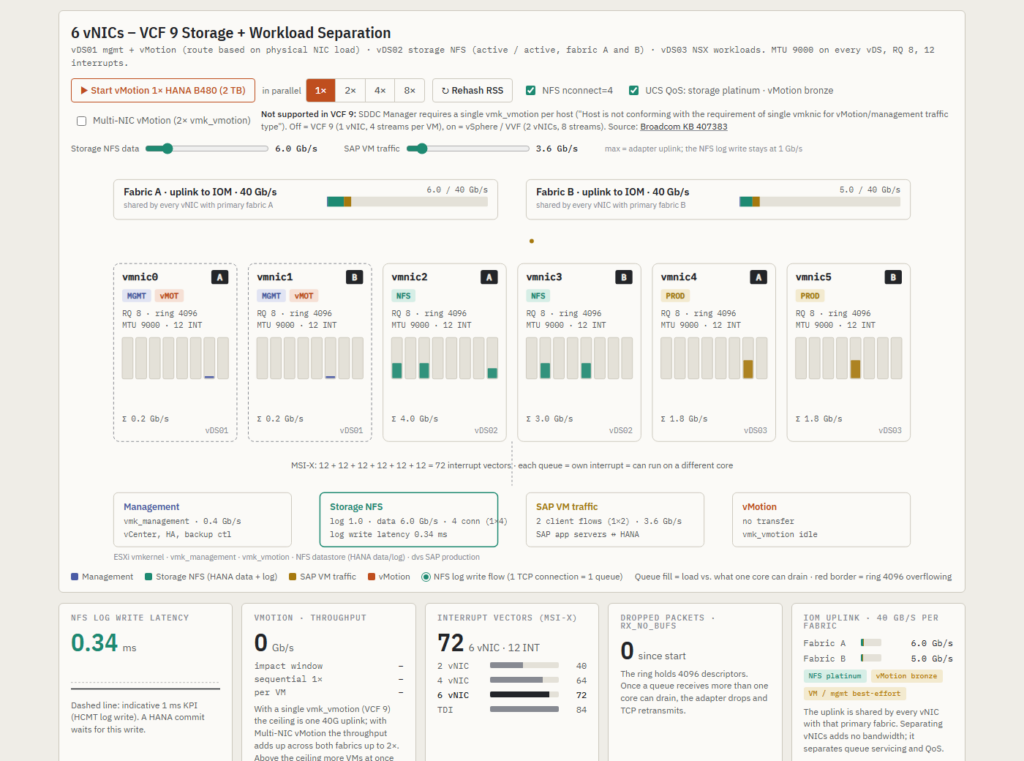
VCF 9 Storage and Workload Separation model at idle: NFS log and data connections spread over vmnic2 and vmnic3
6 vNICs at idle with one HANA VM. The NFS log and the four data connections spread over vmnic2 and vmnic3, so storage has 16 queues on two fabrics and nothing else in them.

7 NICs: FlexPod SAP HANA TDI

The Cisco CVD layout goes one step further and gives management its own vNIC as well, and it runs vMotion with two VMkernel adapters on two vNICs. A 2 TB VM then migrates in about 11 minutes instead of 22. For the HANA log it behaves like the 6‑NIC layout, because the storage vNICs are separate either way. If you build on FlexPod without VCF, use it. If you build on VCF 9, the 6‑NIC model gets you the same protection for HANA with one vNIC template less.
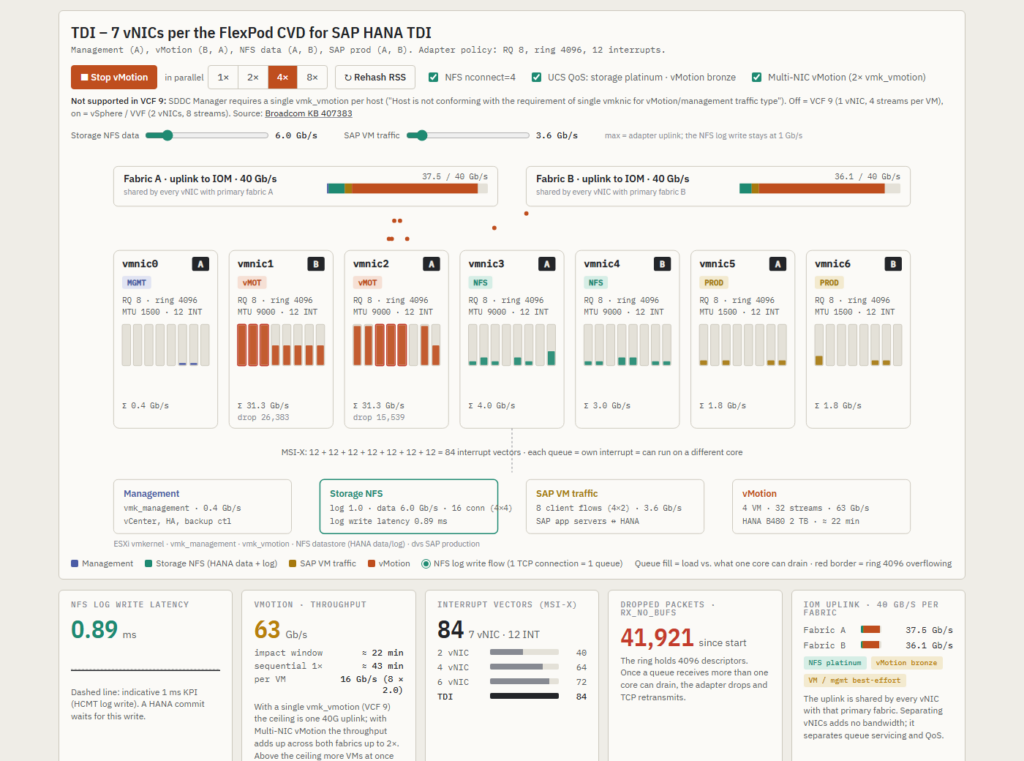
FlexPod SAP HANA TDI layout with 7 vNICs and Multi-NIC vMotion across both fabrics
7 vNICs per the FlexPod CVD, four migrations with Multi‑NIC vMotion. The streams spread over vmnic1 and vmnic2 on both fabrics, the storage vNICs carry only NFS.

QoS and NIOC are two different things

Separate vNICs alone are not enough. The uplink is still shared, and four parallel migrations will fill it. With a UCS QoS policy that puts the storage vNIC in the platinum class and vMotion in bronze, storage keeps its bandwidth and the log stays under 1 ms. Without it, vMotion takes the whole uplink and even the TDI layout ends up above 4 ms.

FlexPod TDI layout with eight vMotions and UCS QoS disabled: the shared uplink raises NFS log latency
The same TDI layout, eight migrations, QoS off. The queues are still isolated, the uplink is not.

The reverse holds as well. NIOC on the 2 and 4‑NIC models does protect bandwidth, and the model gives it credit for that, but it cannot protect queues. You need both: a vNIC of its own for storage, and a QoS class of its own on the uplink.

Multi-NIC vMotion is currently not supported by VCF 9.x SDDC Manager workflows

On plain vSphere you would give vMotion two VMkernel adapters on two uplinks, so a migration can use both fabrics. vSphere and VVF support Multi-NIC vMotion, but VCF 9.x SDDC Manager requires exactly one VMkernel adapter tagged for vMotion per host. When a host has a second one, SDDC Manager flags it after an inventory sync with the message “Host is not conforming with the requirement of single vmknic for vMotion/management traffic type”. The fix is to remove the second adapter and re-run host commissioning. Broadcom KB 407383 describes the issue. It notes that hosts with multiple vMotion adapters reach far lower vMotion concurrency in VCF 9.x than in vSphere 8.x, and that Load-based Teaming on the single vMotion VMkernel adapter is the exception to that limit.

For HANA hosts this has two consequences. A single migration gets only half the stream helpers and one 40 Gb/s path, about 16 Gb/s in the model, so a 2 TB VM takes about 22 minutes instead of 11. And on the 2 and 4‑NIC layouts every one of those streams enters through the single vNIC that also carries the NFS log, which is why the table above shows the KPI broken from the first migration. The simulator has a Multi‑NIC vMotion switch so you can compare both cases. It is off by default because that is what VCF 9 gives you.

Parallel vMotion during maintenance

vSphere allows up to eight concurrent vMotions per host. With one vMotion adapter on a 40 Gb/s uplink, one 2 TB HANA VM uses about 16 Gb/s and takes about 22 minutes. Two in parallel fill the uplink at about 31 Gb/s and still finish in about 22 minutes, so the second one is free. From there on more parallelism buys nothing: four VMs take about 44 minutes and eight about 89 minutes, the same as running them two at a time. What grows is the impact window on the shared layouts, because every additional VM puts more vMotion streams into the queues the log flow lives in. When you evacuate a host with HANA VMs on VCF 9, two at a time is the sensible limit.

Does a faster adapter fix it?

The first question I got after showing the model was whether a 100 Gb/s adapter makes the discussion go away. The simulator now has three adapters to switch between: the Cisco VIC 1380 with 2 × 40 Gb/s, the Cisco VIC 15231 with 2 × 100 Gb/s and 16 receive queues per vNIC, and the HPE Synergy 6310C with 2 × 50 Gb/s. The table shows the 2 vNIC and 6 vNIC layouts on each, single vMotion adapter, UCS or NIOC bandwidth protection on.

AdapterLayoutIdle1× vMotion4× vMotion8× vMotion2 TB VM, one migration
Cisco VIC 1380 · 2 × 40G · RQ 82 vNIC0.34 ms1.82 ms2.37 ms3.49 ms16 Gb/s · ≈ 22 min
6 vNIC0.34 ms0.35 ms0.88 ms0.83 ms
Cisco VIC 15231 · 2 × 100G · RQ 162 vNIC0.27 ms1.74 ms4.98 ms3.42 ms32 Gb/s · ≈ 11 min
6 vNIC0.27 ms0.27 ms0.71 ms0.71 ms
HPE Synergy 6310C · 2 × 50G · RSS 42 vNIC1.81 ms3.92 ms18.44 ms40.17 ms16 Gb/s · ≈ 22 min
6 vNIC0.34 ms0.34 ms0.87 ms0.87 ms

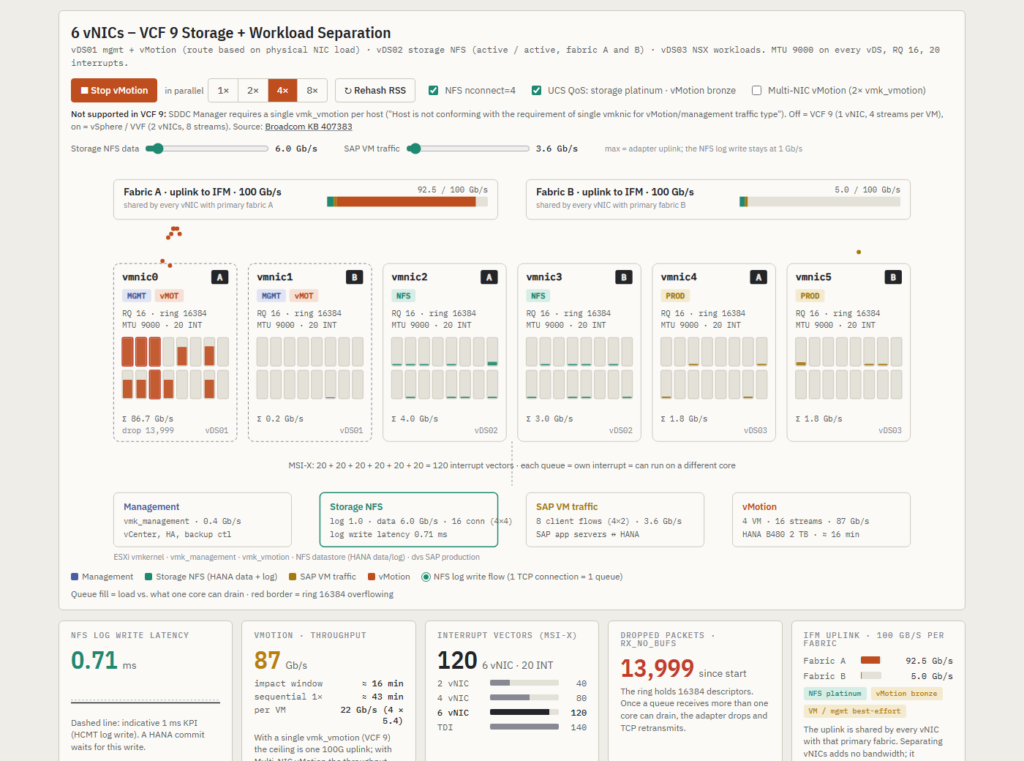
The VIC 15231 halves the migration time and the wider ring drops far fewer packets, but on the 2 vNIC layout the log write still sits well above the KPI from the first migration. Bandwidth was never the only problem. The vMotion streams still land in the same queues and on the same cores as the log flow, and at 8 Gb/s per stream they fill a core faster than before. On the 6 vNIC layout the 15231 is better in every column, and the 16 storage queues per vNIC are exactly what the 32 NFS connections of eight databases need.
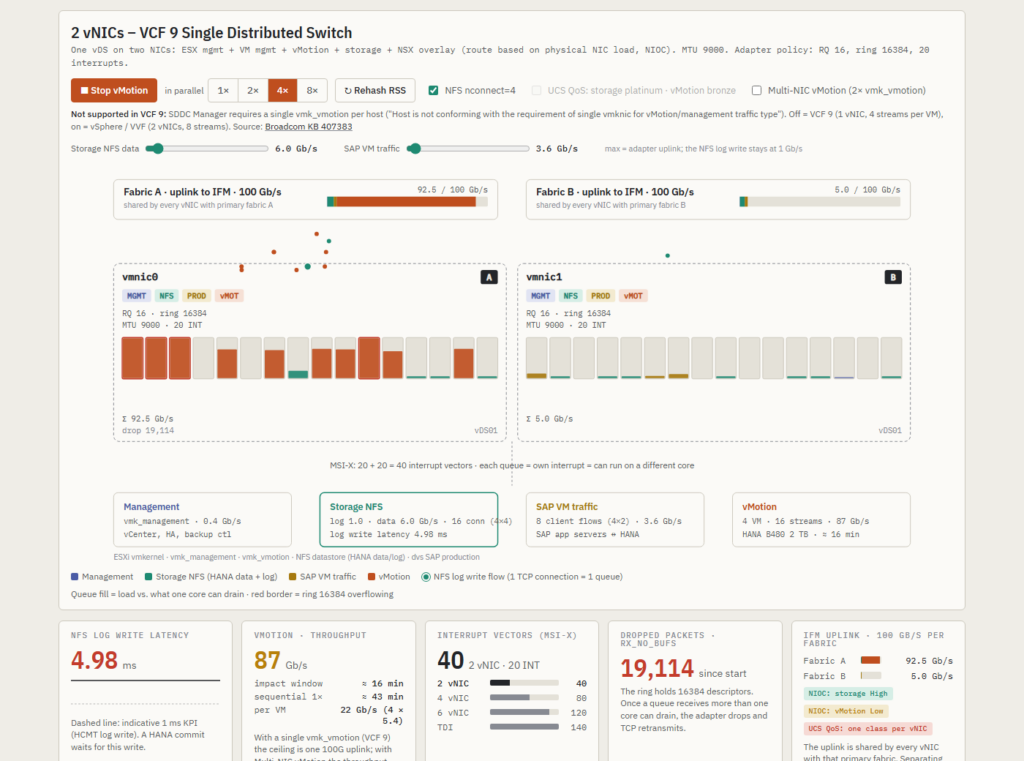
Cisco VIC 15231 with 2 vNICs: vMotion still shares receive queues with the NFS log flow
2 vNICs on a VIC 15231, four migrations. Sixteen queues, a ring of 16384 and a 100G uplink. The vMotion streams still share queues with the NFS log flow, log write at 5.0 ms.
Cisco VIC 15231 with 6 vNICs: four vMotions at 87 Gb/s with the storage vNICs untouched
6 vNICs on a VIC 15231, four migrations at 87 Gb/s. The storage vNICs are untouched and the impact window shrinks to about 16 minutes.

The Synergy 6310C is the other direction. With four RSS queues per FlexNIC, the 2 vNIC layout is above the KPI before any vMotion starts: the log flow of a single HANA VM already shares its queue with NFS data and client traffic. Every migration then lands in the same four queues, and at four and eight migrations the model’s latency formula runs off the scale, so take the direction from those cells and not the digits. The 6 vNIC layout still protects the log, because the storage FlexNIC never sees vMotion packets, but the headroom is smaller than on either VIC. If you run HANA on Synergy, raise the RSS queue count of the storage function from the default and give storage its own FlexNIC pair in Virtual Connect with a bandwidth minimum.
HPE Synergy 6310C with 2 vNICs: four RSS queues per FlexNIC carry vMotion next to the NFS flows
2 vNICs on a Synergy 6310C, four migrations. Four queues per FlexNIC, every one of them carries vMotion next to the NFS flows, and the log write is at 18.4 ms in the model.

Lifecycle note for the VIC 1380: Broadcom KB 391170 lists the UCS VIC 1340 and VIC 1380 as Restricted in ESX 9.0, under both nenic and nfnic. They still work on 9.0 and stay listed in the compatibility guide, but they get no new features or driver enhancements and only best-effort fixes, and Restricted devices are removed in the next major release. The VIC 15231 isn’t in either the Restricted or the End of Life list. If you are planning new HANA hosts for VCF 9, start from the 15231, and check your exact adapter and firmware in the Broadcom Compatibility Guide. The full list is on ESXi 9.0 – Deprecated and unsupported devices.

What I recommend

  • For HANA hosts on VCF 9, use the 6‑NIC Storage and Workload Separation model. If a host has only four ports, Storage Separation is better than Workload Separation because it keeps the NFS log away from vMotion, but SAP client traffic then shares the path with vMotion, so plan for six. On FlexPod without VCF, keep the 7‑vNIC TDI layout from the CVD.
  • Put the storage vNICs in a platinum QoS class in UCS and vMotion in bronze. NIOC is not a substitute on the uplink, and it is no help at all in the queues.
  • Do not buy a faster adapter to avoid the layout decision. A VIC 15231 shortens the maintenance window, it does not separate the queues. Where it does pay off is the storage vNIC: 16 queues for the NFS connections of many databases on one host.
  • Mount HANA data and log with nconnect, or with several mounts. One TCP connection is one queue and one core. Count the connections: eight databases with nconnect=4 are 32 data connections plus their log flows on the storage vNIC.
  • Limit concurrent HANA vMotions per host to two during maintenance windows. With the single vMotion adapter VCF 9 allows, two migrations fill the uplink and a third one only stretches the window.
  • Run HCMT at idle and during a vMotion of one and two HANA VMs, and keep the result as a baseline. On a performance ticket SAP and Broadcom ask about deviations from best practice first.
  • Watch rx_no_bufs on the storage vNICs. If the counter increases during the test, the receive ring is being exhausted. Correlate this with per-queue statistics and traffic load before attributing the drops to RSS/queue contention.

Try it yourself

The interactive model is on this site: vdan.cz/vcf9-sap-hana-tdi-design. You can switch between the four layouts and the three adapters, set one to eight HANA VMs and migrate them in parallel, toggle the UCS QoS policy, nconnect and Multi‑NIC vMotion, move the NFS data and SAP client traffic sliders up to the adapter’s line rate, and re‑roll the RSS hash to see how much of the effect is luck. The numbers update live, including the log write latency, the number of NFS and client connections per layout, the interrupt vector count and the dropped packets on the rings. It is available in Czech and English.

A word on the model: queue capacity, stream rates and the latency formula are illustrative and documented on the page. They are there to explain why the layouts behave differently, not to replace a measurement on your own hardware.

Related on vdan.cz

Sources

VCF 9.x Upgrade Stuck on vRNI / Aria Operations for Networks SSL Thumbprint Validation

VCF 9.x upgrade keeps failing on the vRNI / Aria Operations for Networks thumbprint after a cert change? Clear the stale thumbprint cached in SDDC Manager.


During a VMware Cloud Foundation upgrade, you may hit a situation where the upgrade workflow fails on validation of the vRNI / Aria Operations for Networks certificate thumbprint.

Even after replacing the certificate directly on the vRNI appliance, clicking Retry in SDDC Manager may continue to fail with the old certificate thumbprint.

This can be confusing because the certificate on the vRNI side is already correct, but SDDC Manager still validates against the previous thumbprint.

Root Cause

The root cause is that SDDC Manager caches the SSL thumbprint either in its internal database, platformdb, or in the LCM / Domain Manager service memory when the upgrade task is first initialized.

As a result, even if the certificate is replaced on the vRNI / Aria Operations for Networks appliance, the Retry button does not automatically rediscover the new certificate thumbprint.

Instead, the retry operation may continue to use the old cached value.

To resolve this, the thumbprint stored in the SDDC Manager inventory database must be updated manually.

Warning:
This procedure modifies the internal SDDC Manager database. Use it only when you fully understand the impact. Always take a backup or snapshot of the SDDC Manager appliance before making manual database changes. In production environments, validate with VMware/Broadcom support first.


Step 1: Extract the New Certificate Thumbprint from vRNI

Log in to the SDDC Manager appliance via SSH.

Usually this means logging in as vcf and then switching to root:

su -

Now retrieve the SHA-256 fingerprint of the currently installed certificate on the vRNI / Aria Operations for Networks appliance:

echo -n | openssl s_client -connect <VRNI_FQDN_OR_IP>:443 2>/dev/null | openssl x509 -noout -fingerprint -sha256

Example output:

sha256 Fingerprint=XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX

Copy only the thumbprint value, without the prefix:

XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX

Step 2: Check the Current Thumbprint in SDDC Manager Database

Connect to the SDDC Manager PostgreSQL database:

psql -h localhost -U postgres -d platformdb

Now locate the vRNI / Aria Operations for Networks resource record:

SELECT id, type, status, ssl_thumbprint
FROM resource
WHERE type LIKE '%VRNI%'
OR type LIKE '%ARIA%';

Identify the row that belongs to your vRNI / Aria Operations for Networks appliance.

You should see that the ssl_thumbprint column still contains the old thumbprint, for example:

EF:0B:A2:15:...

Step 3: Update the Stored Thumbprint

Update the resource record with the new thumbprint:

UPDATE resource
SET ssl_thumbprint='<NEW_THUMBPRINT>'
WHERE id='<COMPONENT_ID>';

Example:

UPDATE resource
SET ssl_thumbprint='=XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX:XX'
WHERE id='xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx';

Verify the change:

SELECT id, type, status, ssl_thumbprint
FROM resource
WHERE id='<COMPONENT_ID>';

Exit PostgreSQL:

\q

Step 4: Restart LCM and Domain Manager Services

SDDC Manager may still cache inventory data in memory, so restart the relevant services:

systemctl restart lcm
systemctl restart domainmanager

Wait a few minutes until the services are fully initialized.

You can monitor the LCM service log with:

tail -f /var/log/vmware/vcf/lcm/lcm.log

Step 5: Reset a Stuck Upgrade Task if Needed

In some cases, the upgrade task may remain stuck in an IN_PROGRESS state or the Retry button may stay unavailable.

If this happens, check the active execution tasks in the SDDC Manager database.

Connect again to PostgreSQL:

psql -h localhost -U postgres -d platformdb

Find tasks that are still marked as running:

SELECT id, status, action
FROM execution_task
WHERE status='IN_PROGRESS';

Identify the specific stuck task related to the failed upgrade validation.

Then manually mark it as failed:

UPDATE execution_task
SET status='FAILED'
WHERE id='<TASK_ID>';

Exit PostgreSQL:

\q

Step 6: Resume the Upgrade

Return to the SDDC Manager UI and refresh the upgrade page.

The upgrade workflow should now allow you to click Retry again.

This time, SDDC Manager should read the corrected thumbprint from the database, validate it against the current vRNI / Aria Operations for Networks certificate, and continue with the VCF 9.x upgrade.


Summary

If a VCF 9.x upgrade continues to fail on vRNI / Aria Operations for Networks certificate validation even after the certificate has been replaced, the issue may not be the certificate itself.

The problem can be caused by a stale SSL thumbprint cached in SDDC Manager.

The fix is to:

  1. Extract the new SHA-256 certificate thumbprint from vRNI.
  2. Update the corresponding ssl_thumbprint value in platformdb.
  3. Restart the lcm and domainmanager services.
  4. Reset the stuck execution task if required.
  5. Retry the upgrade from the SDDC Manager UI.

This is a useful recovery procedure when the UI retry mechanism continues to use stale inventory data instead of the actual certificate currently installed on the vRNI appliance.

Holodeck 9.0.2 with VCF 9.0.2.0 Stuck at Install-VcfInstallerBundles

Holodeck 9.0.2 with VCF 9.0.2.0 hangs at Install-VcfInstallerBundles: why the API returns 8 bundles, the PowerShell workaround, and the proper fix.


Bug VCF 9.0.2.0 with Holodeck 9.0.2

While deploying VMware Cloud Foundation 9.0.2.0 with Holodeck 9.0.2, I hit an interesting issue during the bundle download phase.

The deployment did not fail with a clear error. Instead, it stalled indefinitely at:

Install-VcfInstallerBundles

At first glance, everything looked fine. The VCF Installer depot UI showed all required components as downloaded successfully. However, the Holodeck deployment kept waiting forever.

The root cause turned out to be a hardcoded bundle count check inside the Holodeck PowerShell module.


Environment

The issue was observed with the following setup:

Holodeck:        9.0.2
HoloRouter OVA: 9.0.2.0424
VCF Installer: 9.0.2.0
Target VCF: 9.0.2.0
Deployment: Full VCF, ManagementOnly
Depot: Online depot

Important detail: this was full VCF, not VVF.


Symptom

During deployment, the log repeatedly showed:

SddcMgmtDomain[<pid>]: [INFO] Received Bundles. Checking if all VCF 9 bundles are available
SddcMgmtDomain[<pid>]: [INFO] Didn't receive all bundles. Received 8 bundle details. Trying again after 10 seconds

This message repeated every 10 seconds.

At the same time, the VCF Installer UI showed all visible components as successfully downloaded:

SDDC Manager 9.0.2.0
VMware Cloud Foundation Automation 9.0.2.0
VMware Cloud Foundation Operations 9.0.2.0
VMware Cloud Foundation Operations Collector 9.0.2.0
VMware Cloud Foundation Operations fleet management 9.0.2.0
VMware NSX 9.0.2.0
VMware vCenter 9.0.2.0

So from the UI perspective, everything looked complete. However, Holodeck was still waiting.


Root Cause

The problematic logic is inside the Holodeck PowerShell module on the deployed HoloRouter:

/root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1

The affected function is:

Install-VcfInstallerBundles

Holodeck queries the VCF Installer API:

https://${HostName}/v1/bundles/download-status?imageType=INSTALL

Then it filters bundles matching the selected VCF version:

}elseif($Version -eq "9.0.2.0"){
$vcf9_bundle_details = $bundle_details.elements | Where-Object {$_.version -match "9\.0\.2\.0\.*"}
}

The problem is the final count check:

elseif($vcf9_bundle_details.count -eq 7){
Write-Log -Message "Received all Bundle Details"
$bundle_api_response = $true
}
else{
Write-Log -Message "Didn't receive all bundles. Received $($vcf9_bundle_details.count) bundle details. Trying again after 10 seconds"
Start-Sleep -Seconds 10
}

For VCF 9.0.2.0, the API returns 8 matching bundle entries, not 7.

That means this condition never becomes true:

$vcf9_bundle_details.count -eq 7

Holodeck receives 8 bundles, but waits for exactly 7.

Result: an infinite loop.


Why Does the API Return 8 Bundles?

In VCF 9.0.2.0, the bundle structure changed compared to earlier VCF 9 versions.

The depot UI shows 7 visible rows, but the API response contains 8 entries matching:

9.0.2.0.*

The 9.0.2 BOM appears to split some components more granularly, for example around VCF Operations, Operations Collector, and Fleet Management. The UI abstracts this nicely, but the API exposes one additional bundle-level entry.

The important part is this:

VCF Installer UI: 7 visible downloaded components
VCF Installer API: 8 matching bundle entries
Holodeck logic: expects exactly 7

That mismatch is enough to block the deployment.


Workaround

Edit the Holodeck module directly on the HoloRouter.

Change this:

}elseif($vcf9_bundle_details.count -eq 7){

To this:

}elseif($vcf9_bundle_details.count -ge 7){

One-liner:

sed -i 's/$vcf9_bundle_details.count -eq 7/$vcf9_bundle_details.count -ge 7/' \
/root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1

This changes the check from “exactly 7 bundles” to “at least 7 bundles”.


Restart the Running PowerShell Session

The currently running pwsh process already has the old function loaded in memory.

After patching the file, kill the running PowerShell process:

pkill -9 -f pwsh

Then start a fresh PowerShell session and resume the deployment:

Import-HoloDeckConfig -ConfigID <id>

New-HoloDeckInstance -Version 9.0.2.0 -InstanceID <same-as-before> <original flags>

For example:

New-HoloDeckInstance -Version 9.0.2.0 -InstanceID 1 -ManagementOnly

Use the same flags you used in the original deployment.


What Happens After the Patch?

After applying the workaround, Holodeck resumes at the existing deployment state.

In my case, the state engine resumed at:

Install-VcfInstallerBundles

The patched function immediately accepted the 8 returned bundle entries and logged:

Received all Bundle Details

The deployment then moved forward.

Some bundle download calls may return:

BUNDLE_DOWNLOAD_ALREADY_DOWNLOADED

That is expected because the bundles are already present in the depot. The existing try/catch handling allows the phase to complete quickly.

After that, the deployment advanced to the management-domain phase.


Suggested Proper Fix

The quick fix is:

- }elseif($vcf9_bundle_details.count -eq 7){
+ }elseif($vcf9_bundle_details.count -ge 7){

A version-specific fix would also work, for example:

VCF 9.0.0.0 / 9.0.1.0 -> expect 7
VCF 9.0.2.0 -> expect 8

However, that would likely reintroduce the same type of bug in a future VCF BOM revision.

A better long-term approach would be to avoid a hardcoded count completely and validate the actual bundle download state instead.

For example, Holodeck should check that all required bundles for the selected deployment type and version are present and successfully downloaded, instead of assuming that the bundle count is always static.

Still, as an immediate workaround, changing -eq 7 to -ge 7 is enough to unblock the deployment.


Important Notes

This is an unofficial workaround.

The affected PowerShell module is not part of the public Holodeck documentation repository. It is bundled inside the HoloRouter OVA distributed through the Broadcom Support Portal.

Before editing vendor-supplied files, it is always a good idea to make a backup:

cp /root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1 \
/root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1.bak

Then apply the patch.


Summary

This is a good example of a small hardcoded assumption causing a deployment to stall without an obvious fatal error.

The VCF Installer API was returning valid data. The depot was populated. The UI showed the bundles as successfully downloaded. But Holodeck was waiting for an exact number of bundle entries that no longer matched the VCF 9.0.2.0 BOM.

For affected Holodeck 9.0.2 users deploying VCF 9.0.2.0, the key symptom is:

Didn't receive all bundles. Received 8 bundle details. Trying again after 10 seconds

If you see this message, check the bundle count logic in:

SddcMgmtDeployment.psm1

The workaround is small, but it can save a lot of troubleshooting time.


Quick Reference

cp /root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1 \
/root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1.bak

sed -i 's/$vcf9_bundle_details.count -eq 7/$vcf9_bundle_details.count -ge 7/' \
/root/.local/share/powershell/Modules/HoloDeck/Modules/SddcMgmtDeployment.psm1

pkill -9 -f pwsh

Then resume:

Import-HoloDeckConfig -ConfigID <id>
New-HoloDeckInstance -Version 9.0.2.0 -InstanceID <same-as-before> <original flags>

KB 406901: Fix “Certificate authorities update failed” in the VCF Management CA Wizard (VCF 9.0)

VCF 9.0 CA wizard: “Certificate authorities update failed” and 401 Unauthorized? A # or & in the CA service account password causes it (KB 406901).

Short answer: if the VCF 9.0 wizard Configure Certificate Authority for VCF Management fails with “Certificate authorities update failed” and /var/log/vrlcm/vmware_vrlcm.log shows 401 Unauthorized, check the Microsoft CA service account password. A # or & in the password breaks the request (Broadcom KB 406901). Change the password to one without those characters and run the wizard again.

When integrating a Microsoft Certificate Authority (CA) with VMware Cloud Foundation (VCF) Operations / Fleet Management in VCF 9.0, you may hit a frustrating blocker: the “Configure Certificate Authority for VCF Management” wizard fails with:

“Certificate authorities update failed”

This is documented in Broadcom KB 406901 and, importantly, it’s not always a connectivity or permissions problem—it can be a password character parsing issue.


What you’ll see

UI symptom

In the Configure Certificate Authority for VCF Management wizard, the validation/update step fails with:

  • Certificate authorities update failed

Log symptom (Fleet Management / VCF Operations appliance)

On the VCF Operations appliance, you’ll typically find a 401 Unauthorized in:

  • /var/log/vrlcm/vmware_vrlcm.log

Example (as shown in the KB):

  • Exception occurred while trying to validate Microsoft CA
  • HttpClientErrorException$Unauthorized: 401 Unauthorized
  • 401 - Unauthorized: Access is denied due to invalid credentials.

At first glance, this looks like wrong credentials or insufficient permissions. But KB 406901 highlights a very specific trigger.


Root cause (the “gotcha”)

This is a known issue with special characters in the CA service account password, specifically:

  • # or &

Even if the username/password are correct, the wizard’s CA validation request can fail in a way that surfaces as a 401 Unauthorized.


Resolution / Workaround (what to do now)

1) Reset the service account password

Change the Microsoft CA service account password to a value that does NOT contain:

  • #
  • &

Use a “safe” password character set (letters + numbers is the simplest) to avoid re-triggering the issue.

2) Re-run (or re-save) the CA configuration in the wizard

Go back to the Configure Certificate Authority for VCF Management wizard, enter the updated credentials, and run the validation/update again.

Once certificates have been reissued from the new CA, you can verify the chain with vCert on the vCenter side: the CA certificates in VECS and VMware Directory, and the Lookup Service trust anchors.

Link: Configure Certificate Authority for VCF Management fails with error, “Certificate authorities update failed”

Next step: once the CA is configured, it changes who renews which certificate across the fleet, and how new ESX hosts must be onboarded. See VCF 9 Certificate Management: Custom CAs, Auto-Renewal, and Host Onboarding.

Highlights from VMware Explore 2024 Barcelona

Highlights from VMware Explore 2024 Barcelona: the general session on private cloud, VCF announcements and the sessions worth watching.

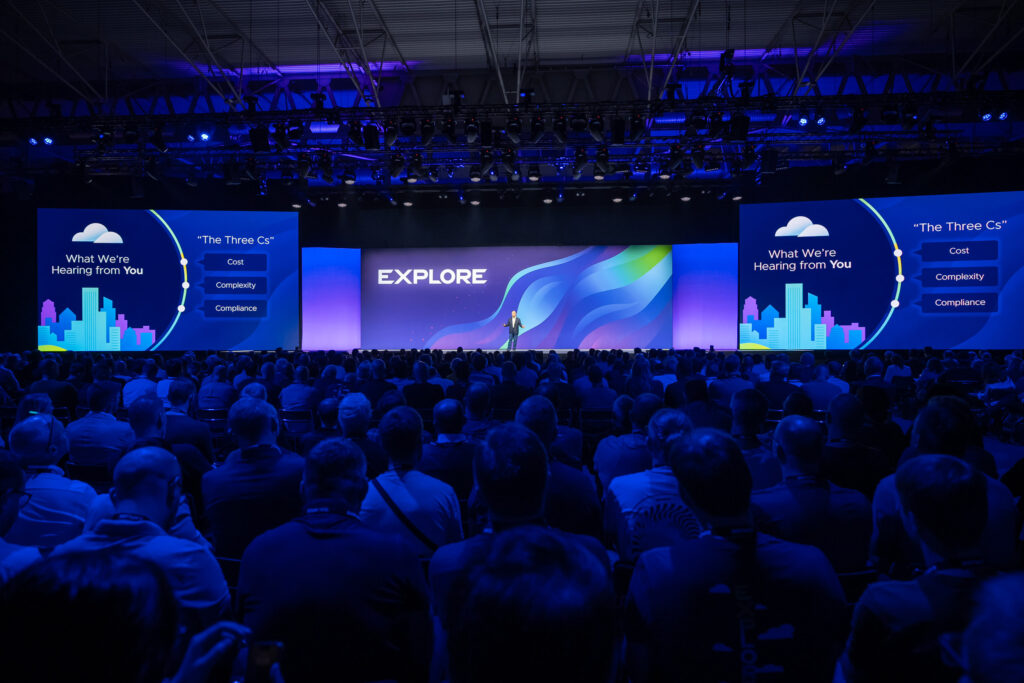
General Session Insights:

  • Private Cloud as the Future of Innovation: Broadcom’s President and CEO, Hock Tan, emphasized that private cloud has become the foundation for enterprise innovation.
  • Balancing AI with Compliance: Chris Wolf highlighted the importance of aligning AI advancements with organizational privacy and compliance needs.
  • Community Acknowledgments: Joe Baguley celebrated the vibrant VMware community, from 1,600+ vExperts to 150,000 VMUG members, for their global contributions.
  • Agile IT for Business Success: Paul Turner emphasized the need for IT agility to rapidly deliver applications and services, crucial for achieving business goals.
  • VeloRAIN Architecture: Sanjay Uppal introduced the VeloRAIN (Robust AI Networking) architecture, leveraging AI/ML to enhance distributed AI workloads’ performance and security.

For more details, check the general session recap.

Notable Sessions and Presentations:

  • Distributed Security Simplified: Dive into the intricacies of distributed security in VMware Cloud Foundation. Read more.
  • VMware vSAN ESA: Explore how VMware vSAN ESA serves as a robust storage platform for VMware Cloud Foundation. Details here.
  • Demystifying DPUs and GPUs: Understand the role of DPUs and GPUs in VMware Cloud Foundation for advancing AI and data workloads. Learn more.
  • AI Without GPUs: Discover innovative ways to harness CPU power for AI workloads in GPU-limited environments. Read more.
  • Data Unlocking with VMware and NVIDIA: Broadcom and NVIDIA offer deep insights into unlocking data potential through AI-powered solutions. Deep dive.
  • VMware Fusion and Workstation: Exciting news—VMware Fusion and Workstation are now available for free. Get the details.

For a complete list of VMware Explore 2024 Barcelona presentations, visit this link.

An inspiring evening of networking and meaningful conversations at the Community Leadership Reception at Explore in Barcelona.
The VMware Community truly is the heart of Explore.
It was an honor to meet Hock Tan CEO,

and engage with incredible leaders like Corey Romero hashtag#vExpert leader and Josef Zach, our hashtag#VMUG Czech leader.

VMware Cloud Foundation (VCF) Brownfield Deployments

Bring existing vSphere into VCF 5.2 with the VCF Import Tool: convert to a management domain, import VI workload domains, prechecks, NSX JSON and sync.

Short answer: in VCF 5.2 you bring existing vSphere into VCF with the VCF Import Tool on SDDC Manager: convert turns an existing vCenter into the management domain, import adds another vCenter as a VI workload domain, check/precheck validate first, and sync fixes configuration drift later. You need the SDDC Manager OVA, the Import Tool and the NSX install bundle. This article describes the VCF 5.2 tool; VCF 9 changes the workflow, so check the VCF 9 documentation before you plan a 9.x import.

VMware Cloud Foundation (VCF) provides a unified platform for managing hybrid clouds, but the deployment process differs between Greenfield (new) and Brownfield (existing) environments. Brownfield deployment involves integrating pre-existing infrastructure into the VCF framework.

Preparing to Use the VCF Import Tool

The VCF Import Tool is essential for transitioning existing infrastructure into the VCF framework. Here’s a step-by-step guide to preparing the tool:

  1. Download the Necessary Files:
    • SDDC Manager OVA: The foundation for managing VCF.
    • VCF Import Tool: Enables import and integration of existing infrastructure.
    • NSX Install Bundle: Configures the networking components for VCF.
  2. Deploy SDDC Manager:
    • This step is necessary for “convert” use cases to establish centralized management within VCF.
  3. Extract the Import Tool:
    • Transfer and configure the import scripts within the SDDC Manager.
  4. Copy NSX Bundle:
    • Ensure the NSX configuration is uploaded for seamless network integration.

Convert Workflow: Transitioning Infrastructure to VCF

The Convert Workflow addresses the challenge of adapting existing environments to align with VCF’s architecture. Follow these steps:

  1. Verify Prerequisites:
    • Confirm that SDDC Manager is running version 5.2 or later.
    • Ensure all required files (Import Tool, NSX bundles) are uploaded.
  2. Run Pre-Check Scripts:
    • Validate the current environment using the Import Tool’s pre-check capabilities. This step identifies configuration issues or incompatibilities.
  3. Create NSX JSON:
    • Generate a JSON file to map the existing network configurations into VCF’s NSX environment.
  4. Convert Management Domain:
    • This final step transitions the management domain to align with VCF’s integrated control and automation.

Import Workflow: Integrating Existing Components

For specific components or domains, the Import Workflow provides a framework to incorporate them into VCF:

  1. Check Prerequisites:
    • Confirm readiness by ensuring the infrastructure meets the required configurations.
  2. Generate NSX JSON:
    • Map existing NSX configurations into a JSON format suitable for VCF integration.
  3. Import Workload Domains:
    • Import and integrate vSphere and NSX components into the VCF ecosystem.

Sync Workflow: Maintaining Infrastructure Alignment

The Sync Workflow ensures continued alignment between the existing infrastructure and VCF:

  1. Verify Prerequisites:
    • Confirm that SDDC Manager is operational and all required scripts are present.
  2. Sync Workload Domain:
    • Synchronize the workload domains with VCF’s management systems, ensuring consistency and reliability.

VCF Import Tool Options and Parameters

Below is an overview of the key actions and parameters available in the VCF Import Tool:

1. Help and Version Commands

  • -h, --help
    Displays the help menu for the VCF Import Tool, outlining available commands and their usage.
  • -v, --version
    Shows the current version of the VCF Import Tool.

2. Core Actions for Brownfield Deployments

  • convert
    Converts an existing vSphere infrastructure into a management domain within SDDC Manager.
  • check
    Validates if a vCenter is suitable for import as a workload domain in SDDC Manager.
  • import
    Imports an existing vCenter as a VI workload domain into SDDC Manager.

3. Sync and Deployment Operations

  • sync
    Synchronizes configuration between an imported VI workload domain or a workload domain deployed from SDDC Manager. This helps manage configuration drift between vCenter Server and SDDC Manager.
  • deploy-nsx
    Deploys NSX Manager as a standalone operation. This is useful for preparing networking configurations for workload domains.
  • precheck
    Runs validation checks on a vCenter to identify any potential issues before starting the import or conversion process.

Demystifying DPUs and GPUs in VMware Cloud Foundation

How DPUs and GPUs fit into VMware Cloud Foundation, based on the VMware Explore EU 2024 session: offload, acceleration and use cases.

At VMware Explore EU 2024, the session “Demystifying DPUs and GPUs in VMware Cloud Foundation” provided deep insights into how these advanced technologies are transforming modern data centers. Presented by Dave Morera and Peter Flecha, the session highlighted the integration and benefits of Data Processing Units (DPUs) and Graphics Processing Units (GPUs) in VMware Cloud Foundation (VCF).

Key Highlights:

  1. Understanding DPUs:
    • Offloading and Acceleration: DPUs enhance performance by offloading network and communication tasks from the CPU, allowing more efficient resource usage and better performance for data-heavy operations.
    • Enhanced Security: By isolating security tasks, DPUs contribute to a stronger zero-trust security model, essential for protecting modern cloud environments.
    • Dual DPU Support: This feature offers high availability and increased network offload capacity, simplifying infrastructure management and boosting resilience.
  2. Leveraging GPUs:
    • Accelerated AI and ML Workloads: GPUs in VMware environments significantly speed up data-intensive tasks like AI model training and inference.
    • Optimized Resource Utilization: VMware’s vSphere enables efficient GPU resource sharing through virtual GPU (vGPU) profiles, accommodating various workloads, including graphics, compute, and machine learning.
  3. Distributed Services Engine:
    • This engine simplifies infrastructure management and enhances performance by integrating DPU-based services, creating a more secure and efficient data center architecture.

Getting started with VCF 4.0 Part 3 – vSphere…

Getting started with VCF 4.0 Part 3 – vSphere with Kubernetes in a Workload Domain

Getting started with VCF 4.0 Part 3 – vSphere…

At this point, we have a fully configured workload domain which includes an NSX-T Edge deployment. Check here for the previous VCF 4.0 deployment steps. We are now ready to go ahead and deploy vSphere with Kubernetes, formerly known as Project Pacific. Via SDDC Manager in VMware Cloud Foundation 4.0, we ensure that an NSX-T Edge is available, and we also ensure that the the Workload Domain is sufficiently licensed to enable vSphere with Kubernetes. Disclaimer: “To be clear, this post is based…Read More


VMware Social Media Advocacy

Getting started with VCF 4.0 Part 2 –…

Getting started with VCF 4.0 Part 2 – Commission hosts, Create Workload Domain, Deploy NSX-T Edge

Getting started with VCF 4.0 Part 2 –…

Now that a VCF 4.0 Management Domain has been deployed, we can move onto creating our very first VCF 4.0 Virtual Infrastructure Workload Domain (VI WLD). We will require a VI WLD with an NSX-T Edge cluster before we can deploy Kubernetes on vSphere (formerly known as Project Pacific). Not too much has changed in the WLD creation workflow since version 3.9. We still have to commission ESXi hosts before we can create the WLD. But something different to previous versions of VCF is that today in…Read More


VMware Social Media Advocacy

Getting started with VMware Cloud Foundation…

Getting started with VMware Cloud Foundation (VCF) 4.0

Getting started with VMware Cloud Foundation…

On March 10th, VMware announced a range of new updated products and features. One of these was VMware Cloud Foundation (VCF) version 4.0. In the following series of blogs, I am going to show you the steps to deploy VCF 4.0. We will begin with the deployment of a Management Domain. Once this is complete, we will commission some additional hosts and build our first workload domain (WLD). After that, we will deploy an NSX-T 3.0 Edge Cluster to our Workload Domain. The great news here is that…Read More


VMware Social Media Advocacy