Daniel Micanek virtual Blog – Like normal Dan, but virtual.
Category: CISCO
The “Cisco” blog category focuses on various aspects of the technologies and products of Cisco Systems, a global leader in networking technologies. This category may include articles on the latest trends in networking, security, cloud computing, and IoT (Internet of Things), which are key for Cisco. It could also cover reviews and guides on Cisco products like routers, switches, security systems, and other networking solutions.
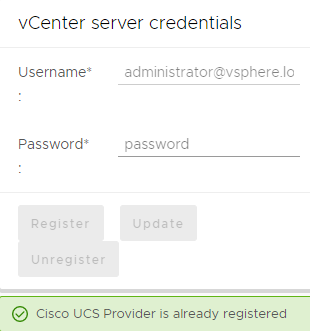
Cisco UCS / Proactive HA Registration / vCenter server credentials / Register
Cisco UCS / Proactive HA Registration / Register
How Could I check it? Edit Proactive HA / Providers
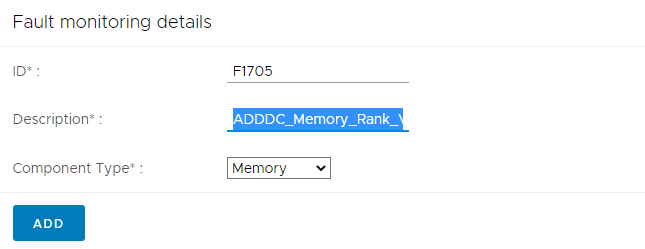
It is better use Name “ADDDC_Memory_Rank_VLS” without spaces. On my picture I used “My F1705 Alerts”
Adding Custom Alert is only possible with unregistered Cisco UCS Provider, it is better to do it immediatly after Cisco UCS Manager Plugin instalation.
Now I can deceided If I will block F1705 or NOT. I personaly preffer to have F1705 Alert under Proactive HA. Then I only restart Blades with F1705. During reboot Hard-PPRpermanently remaps accesses from a designated faulty row to a designated spare row.
NSX Edge design on Cisco UCS for NSX 4.x and VCF 9: Edge VM vs bare metal, vNIC pairs without fabric failover, TEP MTU and VIC Geneve offload.
Short answer: On Cisco UCS, NSX Edge VMs usually go on a small, dedicated ESX edge cluster. Give each Edge a pair of vNICs, one pinned to Fabric A and one to Fabric B, with UCS fabric failover disabled. Redundancy then comes from the Edge’s fp-eth active/standby mapping, not from the Fabric Interconnect. Keep TEP MTU consistent: 1700 or more, ideally 9000 end to end. Enable Geneve offload in the VIC adapter policy for the host transport nodes. For VCF 9, follow the VCF Edge Cluster design library.
I wrote this in 2021 for NSX-T 3.x, because Cisco’s design guides did not cover Edge placement. This September 2026 refresh covers NSX 4.2 and VCF 9.0/9.1, checked against Broadcom TechDocs and Cisco documentation. Parts that apply only to the 2021 design are labelled.
Where is the NSX-T design guide now?
Version
Design reference
NSX-T 3.x (2021, this post’s original basis)
VMware NSX-T Reference Design Guide. The old communities.vmware.com links no longer work.
From vCenter / NSX. Passwords managed by VCF Operations.
Installed from ISO or PXE, then registered manually with NSX Manager
Data path interfaces
4 datapath vNICs
Up to 16 physical interfaces
Strengths
Easy to scale up, vSphere HA recovery, enough performance for most cases
Better small-packet performance, can use several 100G links
UCS specifics
Runs on any UCS ESX host. Uses VIC vNICs through the VDS.
The VCF 9.0 NIC list includes Cisco VIC 1300 and 1400 series (VIC 15000 is not listed). You must configure enough RX/TX queues in UCS Manager for one queue per datapath core. The CPU needs AES-NI and 1 GB huge pages.
Edge VM sizes (VCF 9.0 docs): Small 2 vCPU / 4 GB (proof of concept only), Medium 4 vCPU / 8 GB (L2 to L4 under 2 Gbps), Large 8 vCPU / 32 GB (2 to 10 Gbps, L7 load balancing, TLS inspection), Extra Large 16 vCPU / 64 GB (VPN, IDS/IPS, URL filtering, malware prevention). All sizes use a 200 GB disk.
NSX Edge design on Cisco UCS: uplinks and TEPs on vNICs
The VCF 9.1 edge cluster design recommends a dedicated vSphere cluster for Edges. It limits Edges per host to the number of available physical NICs and gives each Edge its own pair of pNICs. fp-eth0 maps to pNIC 1 active / pNIC 2 standby, and fp-eth1 maps to pNIC 2 active / pNIC 1 standby. Each Edge peers BGP only with the ToRs in its own rack, with BFD. On an FI-attached UCS server, “pNIC 1 / pNIC 2” means a Fabric A vNIC and a Fabric B vNIC:
Create a vNIC pair per Edge (for example edge1-A on Fabric A and edge1-B on Fabric B), plus separate vNICs for host management, vMotion and storage. If ESX numbers the vmnics in a different order than the UCS vNIC placement, fix that first: vNIC order not matching Cisco UCS placement.
Disable fabric failover on these vNICs. Cisco’s teaming guidance for FI-attached servers says to use either fabric failover or OS/vSwitch teaming, never both. The VDS/Edge active/standby mapping is the teaming here.
On the VDS, use two trunk port groups: one with the Fabric A uplink active and Fabric B standby, and one with the reverse. Connect fp-eth0 and fp-eth1 to them. Cisco supports only “Route based on originating port ID” and “source MAC hash” on FI-attached VICs. IP hash is not supported.
In the Edge uplink profile, use two TEPs (multi-TEP) and add named teaming policies that pin each Tier-0 uplink VLAN to one uplink. The Fabric Interconnects run in end-host mode, so the BGP peers are the upstream switches, not the FIs. If a session stays down, see NSX BGP neighbor down: Tier-0 to ToR troubleshooting.
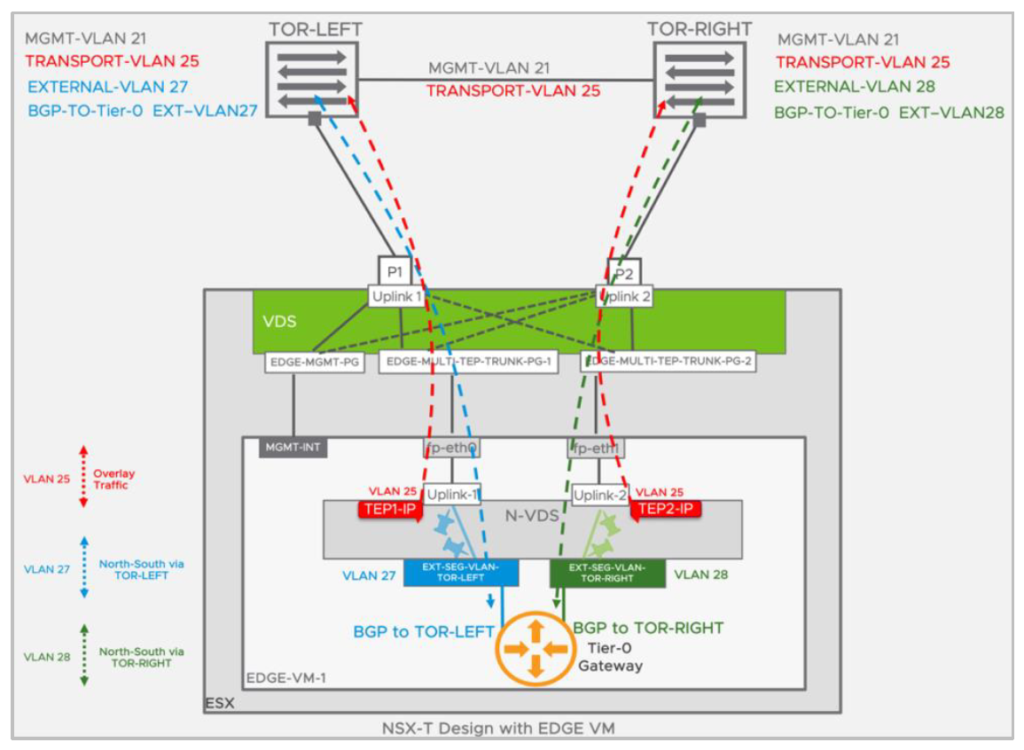
NSX-T 3.0 single N-VDS multi-TEP Edge VM design (source: VMware NSX-T 3.0 Edge Design Step-by-Step). The topology is still valid in NSX 4.x and VCF 9.
The 2021 named teaming example still applies: two policies, PIN-TO-TOR-LEFT (“uplink-1” active) and PIN-TO-TOR-RIGHT (“uplink-2” active), one per external VLAN segment. On UCS, left and right become Fabric A and Fabric B.
MTU for NSX on UCS
NSX requires an MTU of at least 1600 bytes and recommends 1700 to allow for Geneve header growth. For better throughput, set the global TEP MTU, uplink profile MTU and VDS MTU to 9000 when the underlay supports jumbo frames. VCF also requires the Edge TEP MTU to match the host TEP MTU in the same overlay transport zone. On UCS, set the vNIC MTU to 9000, as Cisco’s VIC best practices recommend. The QoS system class and the upstream switches must also carry jumbo frames. Guest VMs can use up to 8800 on a 9000 underlay. If overlay traffic between hosts fails, start with the checks in NSX east-west traffic fails across hosts: TEP and MTU.
VIC adapter policy and Geneve offload
Supported on VIC 1400 from UCSM/IMC 4.1(2) (NSX standard mode) and 4.1(3) (Enhanced Datapath, nenic-ens driver). Supported on VIC 15000 from 4.2(3). Not supported on VIC 1200/1300. Geneve offload is disabled by default.
Recommended Ethernet adapter policy with Geneve offload (UCSM 4.3 guide): TX queues 1, TX ring 4096, RX queues 8, RX ring 4096, completion queues 16, interrupts 32, RSS on, GENEVE offload enabled. RoCEv2 cannot be used with it. Remove the Geneve setting before downgrading firmware.
Geneve offload is used by ESX host transport nodes (the nenic driver). Check it on the host per Broadcom KB 397644:
vsish -e get /net/pNics/vmnic0/properties | grep "Driver\|Device Hard\|Device Soft"
# look for VMNET_CAP_GENEVE_OFFLOAD in "Device Hardware Cap Activated"
# vmkernel.log: "nenic: ... Geneve: Overlay offload enabled, udp_port = 6081"
Use the nenic driver and VIC firmware pair listed in the Broadcom Compatibility Guide for your ESX release. The history (nenic 1.0.35.0 on ESXi 7.0) is covered in my nenic post linked below. A VIC 14xx bug where Geneve traffic leaves on the wrong vNIC is described in CSCvz43359. The newer optimized VIC adapter policy from UCSM 4.3(4a) is covered in VMware-v2 adapter policy for Cisco VIC.
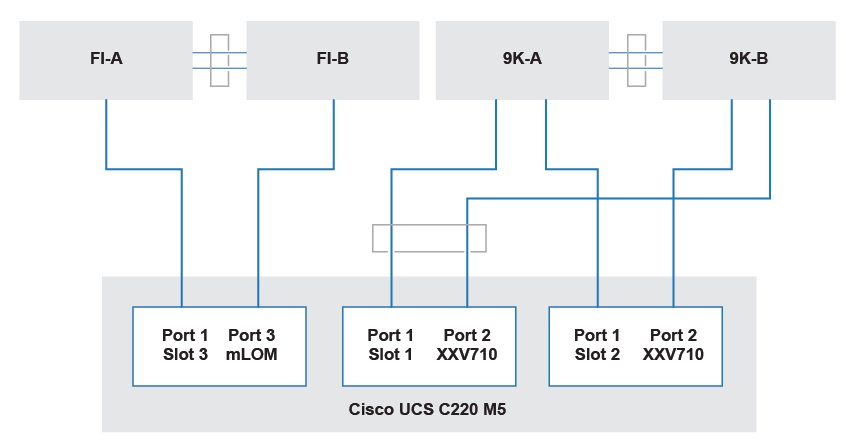
The 2021 Dell EMC VxBlock NSX-T design put the edge on a C220 M5 host. vmnic0/1 were a Cisco VIC 1457 to the FIs for management, vmnic2/3 an Intel XXV710 for TEP/overlay, and vmnic4/5 a second XXV710 for BGP peering, cabled directly to the Nexus 9000 pair. The pattern is still valid when Edge traffic should bypass the FI domain, and it fits VCF’s dedicated-host, dedicated-pNIC recommendation.
C220 M5 edge host cabling, after the Dell EMC VxBlock NSX-T design (2021)
PoC or lab: FI uplink Ethernet interfaces
For a PoC or homelab, configure FI uplink Ethernet ports for the edge VLANs and bind a vNIC template to them. For production, use the vNIC pairs described above.
What’s in version 3.0(6) of the Cisco UCS Manager plugin for the vSphere HTML client: view, manage and monitor UCS hardware from vCenter.
Cisco has released the 3.0(6) version of the Cisco UCS Manager VMware vSphere HTML client plugin. The UCS Manager vSphere HTML client plugin enables a virtualization administrator to view, manage, and monitor the Cisco UCS physical infrastructure. The plugin provides a physical view of the UCS hardware inventory on the HTML client.
I notify BUG “Host not going into monitoring state vCenter restart”. Thank You for fix.
Release 3.0(6)
Here are the new features in Release 3.0(6):
Custom fault addition for proactive HA monitoring
Resolved host not going into monitoring state vCenter restart
Included defect fixes
VMware vSphere HTML Client Releases
Cisco UCS Manager plug-in is compatible with the following vSphere HTML Client releases:
VMware vSphere HTML Client Version
Cisco UCS Manager Plugin for VMware vSphere Version
6.7
3.0(1), 3.0(2), 3.0(3), 3.0(4), 3.0(5), 3.0(6)
7.0
3.0(4), 3.0(5), 3.0(6)
7.0u1, 7.0u2
3.0(5), 3.0(6)
Note
VMware vSphere HTML Client Version 7.0u3 is not supported.
ADDDC Sparing and PPR on Cisco UCS M5: how they work, the Memory RAS and PPR Type BIOS tokens, FN-70432 firmware, and handling F1705/F1706 events.
Short answer: ADDDC Sparing (Adaptive Double Device Data Correction) is the Memory RAS mode that Cisco recommends, and uses as the default, on UCS M5 servers with 1st and 2nd Gen Intel Xeon Scalable CPUs. It watches for correctable errors and moves a failing region into virtual lockstep before the errors become uncorrectable. Post Package Repair (PPR) then repairs the DIMM permanently on the next reboot. Field Notice FN-70432 recommends server firmware 4.1(3d) or later, or 4.1(3c) for standalone C-Series.
Why FN-70432 exists
Intel changed how Single Device Data Correction (SDDC) works in the Xeon Scalable (“Skylake Server”) and 2nd Gen Xeon Scalable (“Cascade Lake Server”) processors. As a result, Cisco UCS M5 servers with DIMM errors can see a higher rate of runtime uncorrectable memory errors than older generations did with the default SDDC RAS mode. An uncorrectable error at runtime means a crash or hang and an outage. Cisco’s answer was new microcode plus BIOS changes that turn on ADDDC Sparing. Cisco also changed the default Memory RAS option to ADDDC Sparing (defect CSCvq38078). FN-70432 was last updated on 19 November 2021.
What ADDDC sparing does
ADDDC can correct two successive DRAM device failures in the same region. It tracks correctable errors and spare-copies the failing bits into a “buddy” cache line.
It uses virtual lockstep (VLS) within a memory channel, at DRAM bank level (bank VLS) or device level (rank VLS). Platinum and Gold CPUs support bank and rank VLS. Silver and Bronze CPUs support bank VLS only.
It does not reserve spare DIMM capacity and does not reduce the memory the OS sees.
Once a region is in lockstep, the server keeps running at slightly reduced memory performance until you can schedule maintenance.
Cisco’s measured overhead with ADDDC enabled, before any sparing event:
Test
Bandwidth change
Memory access, all reads
-4.5%
3:1 reads-writes
-1.3%
2:1 reads-writes
-1.2%
1:1 reads-writes
+1.7%
STREAM-triad-like
-4.4%
SPECrate2017_int_base
-2.3%
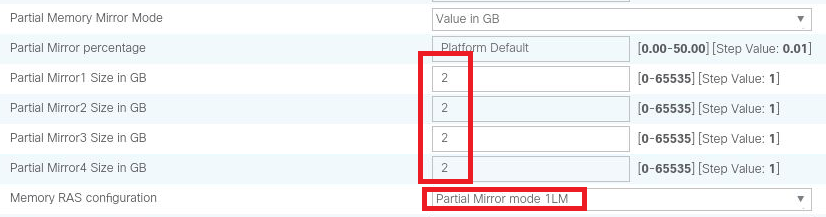
The penalty grows as more bank or rank regions are spared. For comparison, full memory mirroring halves usable capacity. Partial Mirror leaves the non-mirrored memory with baseline ECC only, with no ADDDC protection. Maximum Performance turns off all firmware RAS beyond ECC.
What PPR (Post Package Repair) adds
PPR permanently remaps a failing DRAM row to a spare row inside the DIMM. For a repair, the server must first have an ADDDC event and then go through at least one reboot. It has no effect on performance or capacity. Cisco analysed 273 field-returned DDR4 DIMMs and found that PPR repairs 70% of the faults that ADDDC detected. PPR does not start on a DIMM that has had an uncorrectable error. ADDDC Sparing must be enabled for PPR to work. The platform default PPR type is Hard PPR, and Cisco does not recommend disabling it.
BIOS tokens: Memory RAS configuration and PPR Type
From the Cisco UCS Server BIOS Tokens guide (UCS Manager 4.1, table “Server BIOS Tokens in Release 4.1(1a)”):
UCS Manager: if the BIOS policy’s Memory RAS configuration is Platform Default, nothing needs to change. If it is set to anything else, change it to ADDDC Sparing or Platform Default, or ADDDC will not be active. Check this before the firmware upgrade so you do not need an extra reboot.
Standalone C-Series (IMC): no change is needed.
Since 4.1(3), the BIOS policy also has Enhanced Memory Test (EMT). It adds boot time (about 8 minutes for 768 GB and 30 minutes for 3 TB, worst case) and repairs weak rows with PPR. Cisco recommends it for burn-in and after memory changes.
FN-70432 recommended firmware
Platform
Firmware that supports ADDDC Sparing
Recommended firmware
UCS M5 blades and UCSM-integrated M5 rack servers
3.2(3p)+, 4.0(4i)+, 4.1(1d)+
4.1(3d) or later
Standalone UCS M5 rack servers
3.1(3k)+, 4.0(4l)+, 4.1(1g)+
4.1(3c) or later
ADDDC Sparing first shipped in UCS Manager 4.0(4c) and 4.1(1a) and in IMC 4.0(4e) and 4.1(1c). Critical fixes came later, including the ADDDC virtual lockstep hang. As a minimum, Cisco recommends 4.1(1) for ADDDC event monitoring and PPR, and 4.1(3d) or later for ADDDC, PPR and Enhanced Memory Test together. For HyperFlex, FN-70432 points to the HyperFlex compatibility matrix and lists minimum HXDP releases. In October 2021 I recommended 4.2(1i), which already met the notice. Today, pick the current Cisco-recommended release on your train, not the FN minimum.
Handling ADDDC and PPR events (F1705 / F1706)
Bank-level and rank-level RAS events are non-critical. They mean a bad memory region was swapped out at runtime. Cisco’s procedure:
Check that there are no other DIMM faults, such as an uncorrectable error.
Schedule a maintenance window. Put the ESXi host in maintenance mode and reboot so PPR can repair the DIMM permanently.
If there are no new errors, the repair worked. If new ADDDC events appear, reboot again for another PPR pass.
If an uncorrectable error occurs after the reboot, replace the DIMM.
Firmware
CPU SKU
Bank event
Rank event
4.0(4)
Standard / Advanced
N/A / N/A
N/A / F1706
4.1(1)
All
F1706
F1706
4.1(2), 4.1(3)
Standard / Advanced
F1706 / F1705
N/A / F1706
4.2(1)
Standard / Advanced
F1705 / F1705
N/A / F1706
The Cisco UCS Manager plugin for vSphere can pass these faults to vSphere Proactive HA, so a host can be evacuated before the DIMM fails. The related posts below cover the setup.
Use Fault Resilient Memory (reliable memory) on Cisco UCS with ESXi to protect against uncorrectable memory errors: how to enable it in UCS.
We can see annual incidence of uncorrectable errors is rissing. Here is one possibility – How to solved it with FRM.
ESXi supports reliable memory.
Some systems have reliable memory, which is a part of memory that is less likely to have hardware memory errors than other parts of the memory in the system. If the hardware exposes information about the different levels of reliability, ESXi might be able to achieve higher system reliability.
How to enable in Cisco UCS
Configuration is in BIOS policy / Advanced / RAS Memory
8GB Could be enough for ESXi hypervisor …
This forces the Hypervisor and some core kernel processes to be mirrored between DIMMs so ESXi itself can survive the complete and total failure of a memory DIMM.
# esxcli hardware memory get
    Physical Memory: 540800864256 Bytes
    Reliable Memory: 8589934592 Bytes
    NUMA Node Count: 2
#  esxcli system settings kernel list | grep useReliableMem
 useReliableMem Bool TRUE TRUE TRUE System is aware of reliable memory.
Configuring Reliable Memory in Per-virtual machine basis (2146595)
I can decided to configure more Reliable Memory for VM – not only 8GB for hypervisor.
To turn on the feature per VM:
Edit the .vmx file using a text editor
Add the parameter: sched.mem.reliable = "True"
Save and close the file
Conclusion:
For enable Fault Resilient Memory (FRM) I had to disable ADDDC Sparing in BIOS policy / Advanced / RAS Memory / Memory RAS configuration
With ADDDC and Proactive HA I can save about 95% failures – Personaly I prefer to use ADDDC
The Best possibility is to have both in future firmware …
Cisco nenic Geneve offload: introduced with VIC driver 4.1(2a)/nenic 1.0.33.0, extended in 1.0.35.0. How to enable, verify, and current nenic for ESXi 8.
Short answer: Cisco’s VIC driver release notes first list nenic Geneve offload for ESXi in the 4.1(2a) driver release, which shipped nenic 1.0.33.0 for ESXi 6.7 U3 and 7.0. The 4.1(3a) release shipped nenic 1.0.35.0, which added ESXi 7.0 U1, plus the first nenic_ens driver for the NSX Enhanced Datapath. In UCS Manager, Geneve offload is disabled by default. You enable it per adapter policy on VIC 1400, 14000 or 15000. For ESXi 8, Cisco’s current driver is nenic 2.0.17.0.
I wrote the original post in January 2021 from the VMware download page for nenic 1.0.35.0 (ESXi 6.7). That page listed “Enabled Geneve Offload support for VIC 14xx adapters” as a new feature. The page has since been retired, and Cisco’s own release notes put the Geneve feature one driver release earlier. This update, from September 2026, follows the Cisco documentation.
Which nenic version introduced Geneve offload
Cisco VIC driver release
ESXi nenic
Supported ESXi
Geneve note in the release notes
4.1(1a)
1.0.31.0
6.5 U3, 6.7 U2/U3
none
4.1(2a)
1.0.33.0
6.5 U3, 6.7 U2/U3, 7.0
New: “GENEVE Offload supports on ESX 6.7U3 and ESX 7.0”
4.1(3a)
1.0.35.0
6.5 U3, 6.7 U2/U3, 7.0, 7.0 U1
New: “GENEVE Offload is supported on ESX 7.0U1”. First nenic_ens drivers: 1.0.2.0 (ESXi 6.7 U3) and 1.0.4.0 (ESXi 7.0, 7.0 U1)
Cisco’s VIC 1400 best-practices white paper gives the same timeline from the firmware side. Geneve offload on the fourth-generation VIC is supported for ESXi “starting from Cisco UCSM and Cisco IMC release 4.1(2)”. Enhanced Datapath (ENS) support arrived with 4.1(3) and needs the additional nenic-ens driver.
So for NSX-T in standard (non-ENS) mode on VIC 1400, the minimum is the 4.1(2) firmware plus nenic 1.0.33.0. 1.0.35.0 is the version that brought ESXi 7.0 U1 support and the ENS path.
Enable nenic Geneve offload in UCS Manager
Per the UCS Manager 4.3 Network Management Guide, GENEVE offload is supported on ESXi with VIC 1400, 14000 and 15000 series adapters. It is present in all Ethernet adapter policies and disabled by default. Cisco’s recommended adapter policy for it:
Setting
Value
Transmit queues / ring size
1 / 4096
Receive queues / ring size
8 / 4096
Completion queues
16
Interrupts
32
RSS
Enabled
GENEVE offload
Enabled
For ENS, the VIC 1400 white paper recommends a single TX and RX queue with 4096 rings, and states that there is no RSS support on VIC 1400 for Geneve offload with ENS.
Limitations
Not supported on VIC 1200 and 1300 series.
External outer IPv6 is not supported with GENEVE offload.
RoCEv2 cannot be used with GENEVE offload. Azure Stack QoS is also excluded.
Remove the GENEVE offload configuration before downgrading to a release that does not support it.
Verify Geneve offload on the ESXi host
Broadcom KB 397644 shows how to confirm it. Look for VMNET_CAP_GENEVE_OFFLOAD under “Device Hardware Cap Activated”. In vmkernel.log, look for the nenic lines showing geneve yes and Geneve: Overlay offload enabled, udp_port = 6081:
vsish -e get /net/pNics/vmnic0/properties | grep "Driver\|Device Hard\|Device Soft"
# then check /var/log/vmkernel.log for the nenic Geneve lines
The same KB notes that the RX queue filter class for Geneve (the NetQueue Geneve filter) is not configured on nenic. That is expected: the filter is supported only by nenic_ens, and it is separate from checksum offload.
Current nenic versions for ESXi 8 and 9
Cisco VIC driver release notes
nenic
nenic_ens
ESXi
4.3(2), 4.3(4)
2.0.11.0 (2.0.10.0 for 7.0 Ux)
1.0.6.0
8.0, 8.0 U1 (7.0 U1–U3)
4.3(6)
2.0.17.0
1.0.9.0
7.0 U1–U3, 8.0 and above
6.0(1)
2.0.17.0
1.0.9.0
7.0 U1–U3, 8.0 and above
6.0(2)
2.0.17.0
1.0.18.0
8.0 and above
Cisco’s VIC driver release notes say “ESX 8.0 and above” for nenic but do not name ESX 9.0 for it (the same document names ESX 9.0 for the fnic driver). Before you deploy on VCF 9, check the Broadcom Compatibility Guide for the exact nenic and VIC firmware pair certified for your ESX build.
Where to download nenic now
The old my.vmware.com download link no longer works. Async drivers are now on the Broadcom Support Portal, which requires a Broadcom account (see Broadcom KB 142814 on downloading Broadcom products). Use the Broadcom Compatibility Guide to pick the version.
What’s in version 3.0(4) of the Cisco UCS Manager plugin for the vSphere HTML client: view, manage and monitor Cisco UCS hardware from vCenter.
Cisco has released the 3.0(4) version of the Cisco UCS Manager VMware vSphere HTML client plugin. The UCS Manager vSphere HTML client plugin enables a virtualization administrator to view, manage, and monitor the Cisco UCS physical infrastructure. The plugin provides a physical view of the UCS hardware inventory on the HTML client.
Fix “The virtual machine is configured for too much PMEM” when testing SAP HANA VMs with 1 TB RAM and 1 TB Intel Optane PMem on vSphere.
VMware supports Intel Optane PMem with vSphere 6.7 and 7.0. VMware and Intel worked with SAP to complete the validation of SAP HANA with Optane PMem enabled VMs.
I configured PoC testing VM RAM 1 TB and 1 TB PMem. I was unable to power on. Error – The virtual machine is configured for too much PMem. 6.0 TB main memory and 1024 GB PMem exceeds the maximum allowed 6.0 TB.
Problem was with enable Memory Hot Plug, because there is a limit calculation:
With enable Memory Hot Plug
* Limit 6TB <= size of RAM x 16 + size of PMEM

With disable Memory Hot Plug
* Limit 6TB <= size of RAM + size of PMEM
SAP HANA does not support hot-add memory. Because of this, hot-add memory was not validated by SAP and VMware with SAP HANA and is therefore not supported. According SAP HANA on VMware vSphere
Example how to reproduce an error:
6 TB limit
1 TB PMem
5 * 1024 / 16 = 320 GB

With enable Memory Hot Plug I can't start VM with more than 321 GB RAM.
UCS M5 servers could hang and reboot (#IERR, M2M timeout) once ADDDC virtual lockstep kicked in. The Cisco bugs, fixed releases and what to run now.
Short answer: On Cisco UCS M5 servers with ADDDC Sparing, the memory controller could hang after ADDDC activated virtual lockstep (VLS). The result was #IERR, an M2M (mesh-to-memory) timeout and a reboot. Intel documents the root cause as erratum SKX108 (CLX37 on Cascade Lake). Cisco fixed it in the BIOS: CSCvr79388 and CSCvr79396 in UCS Manager 4.1(1c), and CSCvt64871 for C480 M5 / C480 M5 ML in 4.1(1d). Run at least 4.1(1d). Field Notice FN-70432 recommends 4.1(3d) or later.
This page covers only the lockstep hang. For what ADDDC Sparing and PPR are, the BIOS tokens and FN-70432, see ADDDC Sparing and PPR on Cisco UCS M5.
ADDDC virtual lockstep hang: symptom
ADDDC Sparing corrects failing DRAM by pairing cache lines in virtual lockstep once correctable errors build up on a bank or rank. That is when this bug appears. A server that ran fine for months logs an ADDDC sparing event (UCS Manager fault F1706 or F1705, depending on firmware and CPU SKU). Later it stops responding and reboots with an internal error (#IERR) and an M2M timeout in the memory subsystem. For memory-heavy workloads such as SAP HANA on vSphere, this is exactly the outage ADDDC was supposed to prevent.
Cisco’s release notes point to the Intel specification updates: SKX108 in the Intel Xeon Processor Scalable Family Specification Update, and CLX37 in the 2nd Gen Intel Xeon Scalable Specification Update. The erratum title is “Memory Controller May Hang While in Virtual Lockstep”. Under complex microarchitectural conditions, a memory controller in VLS may hang on a partial write, and the BIOS can contain a workaround. Cisco’s fix is that BIOS workaround.
UCS servers stop responding and reboot after ADDDC virtual lockstep is activated. #IERR and M2M timeout in the memory system.
4.0(4e)B
4.1(1c)B
CSCvr79396
On UCS M5, the VLS sparing copy finishes early, leaving incorrect values in the lockstep region.
4.0(4e)B
4.1(1c)B
CSCvt64871
In rare cases, C480 M5 and C480 M5 ML stop responding and reboot after ADDDC virtual lockstep is activated (SKX108 / CLX37).
4.0(4h)C
4.1(1d)C
The “B” and “C” suffixes are the UCS Manager bundle types (B-Series and C-Series server bundles). CSCvt64871 was still an open caveat in 4.1(1c). Cisco’s workaround until 4.1(1d): “If the server crashes many times after activating ADDDC virtual lockstep, disable ADDDC.”
Why I no longer recommend stopping at 4.1(1c)
When I first wrote this post in May 2020, 4.1(1c) was the fix. The UCS Manager 4.1 release notes later listed two regressions in the 4.1(1c) M5 BIOS, both resolved in 4.1(1d) (July 2020):
CSCvu14656: after the BIOS upgrade to the 4.1(1c) versions (for example B200M5.4.1.1c.0.0404202345, C240M5.4.1.1c.0.0405200025), M5 servers could hang at the memory testing step during boot.
CSCvu11155: possible performance degradation on B-, C- and S-Series M5 servers with 2nd Gen Xeon Scalable CPUs on the same BIOS versions.
FN-70432 also moved the minimum up. ADDDC support begins at 4.1(1d) for UCSM-managed servers (4.1(1g) for standalone). The recommended releases are 4.1(3d) or later for blades and integrated racks and 4.1(3c) or later for standalone M5 racks. So the practical rule is to treat 4.1(1c) as history. Run a current Cisco-recommended release for M5, and never lower than 4.1(3d)/4.1(3c).
What to check on your M5 servers
Find the server firmware (host firmware package) version in UCS Manager or IMC. If it is older than 4.1(1c) and ADDDC is active, check it against CSCvr79388/CSCvr79396. The release notes list 4.0(4e) as first affected, so check the Bug Search Tool for fixed 4.0(4) builds.
Look for past F1705/F1706 faults and unexpected reboots with #IERR or M2M timeout in the SEL. The hang can only happen after ADDDC has actually put a region into lockstep.
Check the BIOS policy. Select Memory RAS configuration should be Platform Default or ADDDC Sparing. Do not switch ADDDC off as a permanent fix. That brings back the higher uncorrectable-error risk that FN-70432 describes.
Upgrade the server firmware bundle. Put the ESXi host in maintenance mode first, because the BIOS update needs a reboot.
After the upgrade, follow Cisco’s ADDDC event procedure. Reboot in a maintenance window so PPR can repair the DIMM, and replace the DIMM only if an uncorrectable error follows.
Intel Xeon Processor Scalable Family Specification Update (erratum SKX108) and 2nd Gen Intel Xeon Scalable Processors Specification Update (erratum CLX37), both referenced by Cisco in CSCvt64871. Search Intel’s Resource and Documentation Center for the current revision.