How to Install llama.cpp and Run Llama 2 (and Newer Models) Locally

Install llama.cpp, get a GGUF model from Hugging Face and run Llama 2 or newer models locally on CPU or NVIDIA GPU, with the current 2026 commands.

Short answer: the fastest way to run Llama 2 locally today is llama.cpp with a GGUF model file. Install llama.cpp (prebuilt release, Docker, or build from source with CMake), then run llama-cli -hf TheBloke/Llama-2-7B-Chat-GGUF: it downloads the Q4_K_M quantized model from Hugging Face and starts a chat. Add -ngl all to offload layers to an NVIDIA GPU. You no longer need Meta’s download script, convert.py or make.

Updated September 2026. The original 2023 version of this guide used commands that no longer exist in llama.cpp. The steps below follow the current ggml-org/llama.cpp documentation. A table mapping the old commands to the new ones is at the end.

What you need

  • OS: Linux, Windows (native or WSL 2) or macOS.
  • Memory: a 4-bit (Q4_K_M) Llama 2 7B GGUF file is about 4 GB, so plan for at least 8 GB of RAM or VRAM for the 7B model, and more for 13B and 70B.
  • GPU (optional): an NVIDIA GPU with the CUDA toolkit for the CUDA backend. Vulkan, Metal (Apple Silicon) and plain CPU also work.
  • To build from source: Git, CMake and a C/C++ compiler (on Windows, Visual Studio 2022 with the C++ workload).

Step 1: Install llama.cpp

The project documents four install options:

  1. Guided setup at llama.app.
  2. Prebuilt binaries from the GitHub releases page. This is the easiest option on Windows: pick the archive that matches your backend (CPU, CUDA, Vulkan).
  3. Docker, for example the ghcr.io/ggml-org/llama.cpp:server-cuda image for an NVIDIA GPU server.
  4. Build from source with CMake (below). Use this when you need a specific CUDA version or GPU architecture, as with a homelab Tesla P40.

Build for CPU

git clone https://github.com/ggml-org/llama.cpp
cd llama.cpp
cmake -B build
cmake --build build --config Release

The binaries (llama-cli, llama-server, llama-quantize, llama-bench and others) end up in build/bin. On Windows, run the commands from the Developer Command Prompt for VS 2022. With the Visual Studio generator, the binaries are in build\bin\Release.

Build with NVIDIA CUDA

cmake -B build -DGGML_CUDA=ON
cmake --build build --config Release

To build only for your GPU (a faster build and a smaller binary), set the compute capability explicitly. For example, -DCMAKE_CUDA_ARCHITECTURES="86;89" covers RTX 30xx and 40xx. For a Tesla P40 (Pascal, compute capability 6.1), use -DCMAKE_CUDA_ARCHITECTURES=61 and a CUDA 12.x toolkit, because CUDA 13 dropped support for Pascal GPUs. My Tesla P40 homelab article covers ESXi passthrough and benchmarks, and CUDA support for WSL 2 explains the WSL setup.

Step 2: Get a Llama 2 model in GGUF format

llama.cpp loads models in the GGUF format, with quantization from 1.5-bit to 8-bit. You have two options.

Option A: download a ready GGUF (recommended). The -hf flag downloads a model straight from Hugging Face and caches it. The quant tag is optional and defaults to Q4_K_M:

llama-cli -hf TheBloke/Llama-2-7B-Chat-GGUF:Q4_K_M

Option B: convert the original Meta weights yourself. The official meta-llama/Llama-2-7b-chat-hf repository on Hugging Face is gated: accept Meta’s license on the model page, then set an access token in HF_TOKEN. Convert the model to GGUF and quantize it:

pip install -r requirements.txt
python convert_hf_to_gguf.py --outfile llama-2-7b-chat-f16.gguf --outtype f16 --remote meta-llama/Llama-2-7b-chat-hf
./build/bin/llama-quantize llama-2-7b-chat-f16.gguf llama-2-7b-chat-Q4_K_M.gguf Q4_K_M

Step 3: Run Llama 2 locally

Interactive chat in the terminal

./build/bin/llama-cli -m llama-2-7b-chat-Q4_K_M.gguf -ngl all -c 4096
  • -ngl (--n-gpu-layers) sets how many layers go to VRAM: a number, auto (the default) or all. Lower it if you run out of GPU memory.
  • -c sets the context size. Llama 2 was trained with a 4,096-token context.
  • -sys "You are a helpful assistant" sets a system prompt. --list-devices shows which GPUs llama.cpp can use.

Newer releases also include a unified llama launcher, so llama cli and llama serve do the same as the standalone binaries.

OpenAI-compatible API server

./build/bin/llama-server -m llama-2-7b-chat-Q4_K_M.gguf -ngl all --host 0.0.0.0 --port 8080

llama-server provides a built-in web UI at http://<host>:8080 and an OpenAI-compatible /v1/chat/completions endpoint, so existing OpenAI client libraries and tools can use your local model:

curl http://localhost:8080/v1/chat/completions \
  -H "Content-Type: application/json" \
  -d '{"messages":[{"role":"user","content":"Explain vSphere HA in two sentences."}]}'

While the model runs, you can watch GPU utilisation and VRAM use with nvtop or nvidia-smi:
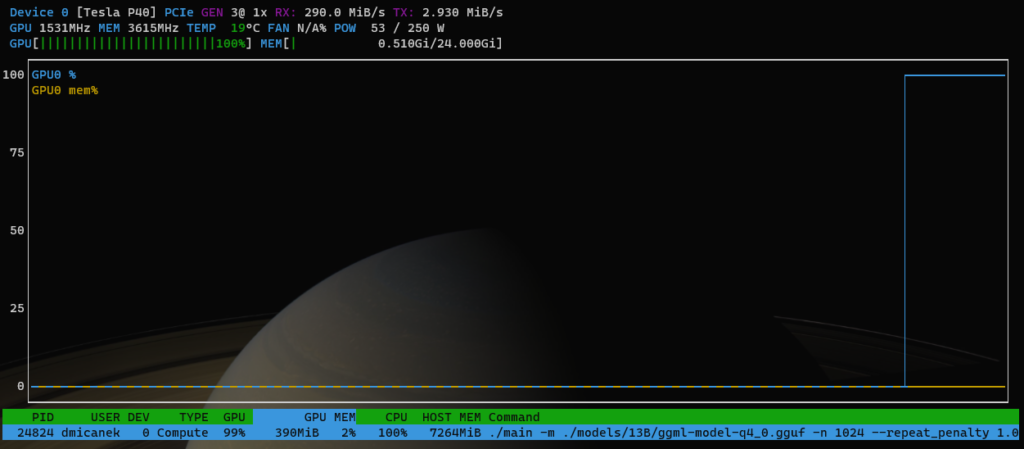
nvtop showing GPU utilisation while llama.cpp runs a Llama 2 model

Install Llama 2 on Windows

On Windows you have two options. The first is to download the CUDA or CPU build from the releases page, unzip it and run llama-cli.exe -hf TheBloke/Llama-2-7B-Chat-GGUF from PowerShell. The second is to use WSL 2 with the NVIDIA Windows driver and follow the Linux steps above. For a source build, use the Developer Command Prompt for VS 2022.

What changed since the 2023 version of this guide

2023 (old)2026 (current)
github.com/ggerganov/llama.cppgithub.com/ggml-org/llama.cpp
make / LLAMA_CUBLAS=1 makecmake -B build -DGGML_CUDA=ON + cmake --build build --config Release
Meta download script + python3 convert.py-hf download of a GGUF, or convert_hf_to_gguf.py
./quantize … q4_0llama-quantize … Q4_K_M
./main -m … --n-gpu-layers 3800llama-cli -m … -ngl all
GGML .bin filesGGUF files

Llama 2 still works well for learning and testing. For new projects, compare it with newer open-weight models on Hugging Face, since the same -hf workflow runs any GGUF model.

Further reading

vSphere Code Capture is your ChatGPT for…

vSphere Code Capture is your ChatGPT for…

Have you ever tried to automate a specific vSphere operation but not sure which vSphere API to use or if know which vSphere API to use you unsure how to actually use it? This is something I frequently see and get asked about quite often! Did you know about this hidden little gem that has […]


VMware Social Media Advocacy

Tanzu & Kubernetes for vSphere Admins: Complete…

Tanzu & Kubernetes for vSphere Admins: Complete Guided Workshop (HOL-2413-01-SDC)

Tanzu & Kubernetes for vSphere Admins: Complete…

Link to Lab: https://userui.learningplatform.vmware.com/HOL/catalog/lab/13926 🌟 Welcome to our VMware Expert-Led Guided Workshop Series! 🌟 In this series, you’ll explore various VMware Hands-On Labs, each led by our team of VMware experts. Dive deep into different VMware solutions, gaining hands-on experience and valuable insights! 🔹 Featured Lab: Tanzu and Kubernetes for vSphere Administrators (HOL-2413-01-SDC) 🔹 This workshop covers: 1️⃣ Module 1: Introduction to vSphere with Tanzu (30 min, Level: Intermediate) Get started with the basics of vSphere and Tanzu integration. 2️⃣ Module 2: What’s New for vSphere 8 Update 1 (15 min, Level: Beginner) Discover the latest updates and features in vSphere 8. 3️⃣ Module 3: Managing vSphere with Tanzu…Read More


VMware Social Media Advocacy

VMUG Virtual December | With Keynote Speaker…

Learn from anywhere! Join us virtually at 9 AM for a LIVE Keynote with Amanda Blevins, VP and CTO, Americas at
@vmware by Broadcom. Register today to secure your spot:

VMUG Virtual December | With Keynote Speaker…

Learn from anywhere! Join us virtually at 9 AM for a LIVE Keynote with Amanda Blevins, VP and CTO, Americas at @vmware by Broadcom. Register today to secure your spot:


VMware Social Media Advocacy

New instance type: M7i with disaggregated…

New instance type: M7i with disaggregated…

This next-generation architecture for VMware Cloud on AWS enabled by an Amazon EC2 M7i bare-metal diskless instance featuring a custom 4th Gen Intel Xeon processor is really bringing a lot of value to our customers. As they combined this instance with scalable and flexible storage options, it […]


VMware Social Media Advocacy

NVIDIA Tesla P40 for Private AI in the Homelab: Specs, ESXi Passthrough and Benchmarks

Tesla P40 specs (24 GB GDDR5, 250 W, 10.5-inch dual slot, compute 6.1), cooling and ESXi passthrough setup, llama.cpp benchmarks, and CUDA 13 limits.

Short answer: the NVIDIA Tesla P40 is a 2016 Pascal data-center GPU with 24 GB GDDR5, a 250 W power limit and a dual-slot, 10.5-inch PCIe Gen3 card with no fan of its own. It’s one of the cheapest ways to get 24 GB of VRAM for local LLMs in a homelab. It runs fine with ESXi PCIe passthrough and in my tests was 16–26× faster than the CPU in llama.cpp. The catch in 2026: CUDA 13 no longer targets Pascal, so you stay on CUDA 12.x.

Tesla P40 specifications

Architecture / GPUPascal, GP102
CUDA cores3,840
Compute capability6.1
Memory24 GB GDDR5, 384-bit
Max power250 W
Form factorDual-slot, 10.5-inch, full height, PCI Express Gen3 x16
CoolingNo fan: designed for server airflow
INT8 inference47 TOPS

Source: NVIDIA Tesla P40 datasheet; compute capability as reported by CUDA in the benchmark output below.

Why I picked the P40

For Private AI in HomeLAB, I was searching for budget-friendly GPUs with a minimum of 24GB RAM. Recently, I came across the refurbished NVIDIA Tesla P40 on eBay, which boasts some intriguing specifications:

  • GPU Chip: GP102
  • Cores: 3840
  • TMUs: 240
  • ROPs: 96
  • Memory Size: 24 GB
  • Memory Type: GDDR5
  • Bus Width: 384 bit

Fitting and cooling the P40 in a homelab

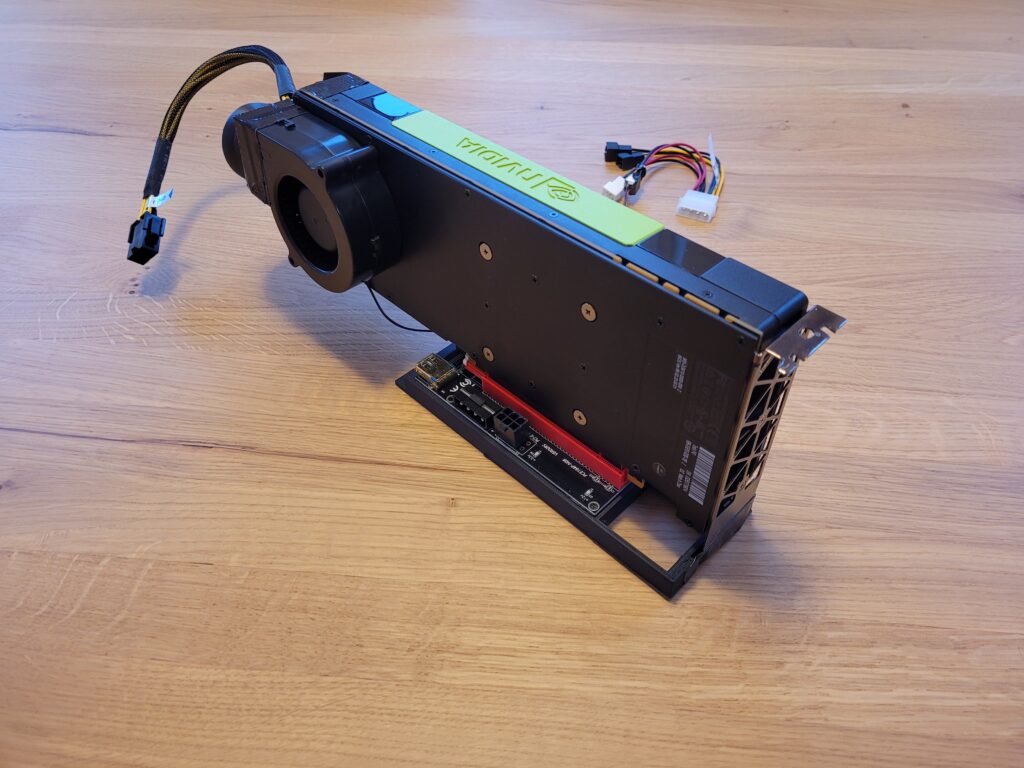
Since the NVIDIA Tesla P40 comes in a full-profile form factor, we needed to acquire a PCIe riser card.

A PCIe riser card, commonly known as a “riser card,” is a hardware component essential in computer systems for facilitating the connection of expansion cards to the motherboard. Its primary role comes into play when space limitations or specific orientation requirements prevent the direct installation of expansion cards into the PCIe slots on the motherboard.

Furthermore, I needed to ensure adequate cooling, but this posed no issue. I utilized a 3D model created by MiHu_Works for a Tesla P100 blower fan adapter, which you can find at this link: Tesla P100 Blower Fan Adapter.

As for the fan, the Titan TFD-B7530M12C served the purpose effectively. You can find it on Amazon: Titan TFD-B7530M12C.

ESXi PCIe passthrough settings

Currently, I am using a single VM with PCIe pass-through. However, it was necessary to implement specific Advanced VM parameters:

  • pciPassthru.use64bitMMIO = true
  • pciPassthru.64bitMMIOSizeGB = 64

If the P40 later disappears from the VM and nvidia-smi can no longer reach the driver, see Tesla P40 passthrough GPU disappears: “PCIe link to the device is down”. A VM reboot doesn’t help there; only a host reboot brings the card back.

llama.cpp benchmark: P40 vs CPU

Now, you might wonder about the performance. It’s outstanding, delivering speeds up to 16x-26x times faster than the CPU. To provide you with an idea of the performance, I conducted a llama-bench test:

pp 512CPU t/sGPU t/sAcceleration
llama 7B mostly Q4_09.50155.3716x
llama 13B mostly Q4_05.18134.7426x
./llama-bench -t 8
| model                          |       size |     params | 
| ------------------------------ | ---------: | ---------: | 
| llama 7B mostly Q4_0           |   3.56 GiB |     6.74 B | 
| llama 7B mostly Q4_0           |   3.56 GiB |     6.74 B | 
| backend    |    threads | test       |              t/s |
| ---------- | ---------: | ---------- | ---------------: |
| CPU        |          8 | pp 512     |      9.50 ± 0.07 |
| CPU        |          8 | tg 128     |      8.74 ± 0.12 |
./llama-bench -ngl 3800
ggml_init_cublas: GGML_CUDA_FORCE_MMQ:   no
ggml_init_cublas: CUDA_USE_TENSOR_CORES: yes
ggml_init_cublas: found 1 CUDA devices:
  Device 0: Tesla P40, compute capability 6.1
| model                          |       size |     params |
| ------------------------------ | ---------: | ---------: |
| llama 7B mostly Q4_0           |   3.56 GiB |     6.74 B |
| llama 7B mostly Q4_0           |   3.56 GiB |     6.74 B |
| backend    | ngl | test       |              t/s | 
| ---------- | --: | ---------- | ---------------: | 
| CUDA       | 3800 | pp 512     |    155.37 ± 1.26 |
| CUDA       | 3800 | tg 128     |      9.31 ± 0.19 |
 ./llama-bench -t 8 -m ./models/13B/ggml-model-q4_0.gguf
| model                          |       size |     params |
| ------------------------------ | ---------: | ---------: |
| llama 13B mostly Q4_0          |   6.86 GiB |    13.02 B |
| llama 13B mostly Q4_0          |   6.86 GiB |    13.02 B |
| backend    |    threads | test       |              t/s |
| ---------- | ---------: | ---------- | ---------------: |
| CPU        |          8 | pp 512     |      5.18 ± 0.00 |
| CPU        |          8 | tg 128     |      4.63 ± 0.14 |
./llama-bench -ngl 3800 -m ./models/13B/ggml-model-q4_0.gguf
ggml_init_cublas: GGML_CUDA_FORCE_MMQ:   no
ggml_init_cublas: CUDA_USE_TENSOR_CORES: yes
ggml_init_cublas: found 1 CUDA devices:
  Device 0: Tesla P40, compute capability 6.1
| model                          |       size |     params |
| ------------------------------ | ---------: | ---------: |
| llama 13B mostly Q4_0          |   6.86 GiB |    13.02 B |
| llama 13B mostly Q4_0          |   6.86 GiB |    13.02 B |
| backend    | ngl | test       |              t/s | 
| ---------- | --: | ---------- | ---------------: | 
| CUDA       | 3800 | pp 512     |    134.74 ± 1.29 |
| CUDA       | 3800 | tg 128     |      8.42 ± 0.10 |

Feel free to explore this setup for your Private AI in HomeLAB.

Is the Tesla P40 still worth it in 2026?

  • CUDA: CUDA Toolkit 13.0 removed offline compilation and library support for Maxwell, Pascal and Volta. You can keep building for the P40 with CUDA 12.x, but newer toolkits can’t target it (CUDA 13.1 release notes).
  • Still good for: running quantized models that need a lot of VRAM on a budget, where 24 GB matters more than raw speed.
  • Plan for: power (250 W) and your own airflow, because the card has no fan.

Related: vGPU management in VMware environments.

DELL R610 or R710: How to Convert an H200A to H200I for Dedicated Slot Use

Convert a Dell H200A to an H200I so it fits the R610/R710 dedicated storage slot and frees a PCIe slot, e.g. for an NVIDIA Tesla P40.

For my project involving the AI tool llama.cpp, I needed to free up a PCI slot for an NVIDIA Tesla P40 GPU. I found an excellent guide and a useful video from ArtOfServer.

Based on this helpful video from ArtOfServer:

ArtOfServer wrote a small tutorial on how to modify an H200A (external) into an H200I (internal) to be used into the dedicated slot (e.g. instead of a Perc6i)

ArtOfServer wrote a small tutorial on how to modify an H200A (external) into an H200I (internal) to be used into the dedicated slot (e.g. instead of a Perc6i)

Install compiler and build tools (those can be removed later)

# apt install build-essential unzip

Compile and install lsirec and lsitool

# mkdir lsi
# cd lsi
# wget https://github.com/marcan/lsirec/archive/master.zip
# wget https://github.com/exactassembly/meta-xa-stm/raw/master/recipes-support/lsiutil/files/lsiutil-1.72.tar.gz
# tar -zxvvf lsiutil-1.72.tar.gz
# unzip master.zip
# cd lsirec-master
# make
# chmod +x sbrtool.py
# cp -p lsirec /usr/bin/
# cp -p sbrtool.py /usr/bin/
# cd ../lsiutil
# make -f Makefile_Linux

Modify SBR to match an internal H200I

Get bus address:

# lspci -Dmmnn | grep LSI
0000:05:00.0 "Serial Attached SCSI controller [0107]" "LSI Logic / Symbios Logic [1000]" "SAS2008 PCI-Express Fusion-MPT SAS-2 [Falcon] [0072]" -r03 "Dell [1028]" "6Gbps SAS HBA Adapter [1f1c]"

Bus address 0000:05:00.0

We are going to change id 0x1f1c to 0x1f1e

Unbind and halt card:

# lsirec 0000:05:00.0 unbind
Trying unlock in MPT mode...
Device in MPT mode
Kernel driver unbound from device
# lsirec 0000:05:00.0 halt
Device in MPT mode
Resetting adapter in HCB mode...
Trying unlock in MPT mode...
Device in MPT mode
IOC is RESET

Read sbr:

# lsirec 0000:05:00.0 readsbr h200.sbr
Device in MPT mode
Using I2C address 0x54
Using EEPROM type 1
Reading SBR...
SBR saved to h200.sbr

Transform binary sbr to text file:

# sbrtool.py parse h200.sbr h200.cfg

Modify PID in line 9 (e.g using vi or vim):
from this:
SubsysPID = 0x1f1c
to this:
SubsysPID = 0x1f1e

Important: if in the cfg file you find a line with:
SASAddr = 0xfffffffffffff
remove it!
Save and close file.

Build new sbr file:

# sbrtool.py build h200.cfg h200-int.sbr

Write it back to card:

# lsirec 0000:05:00.0 writesbr h200-int.sbr
Device in MPT mode
Using I2C address 0x54
Using EEPROM type 1
Writing SBR...
SBR written from h200-int.sbr

Reset the card an rescan the bus:

# lsirec 0000:05:00.0 reset
Device in MPT mode
Resetting adapter...
IOC is RESET
IOC is READY
# lsirec 0000:05:00.0 info
Trying unlock in MPT mode...
Device in MPT mode
Registers:
DOORBELL: 0x10000000
DIAG: 0x000000b0
DCR_I2C_SELECT: 0x80030a0c
DCR_SBR_SELECT: 0x2100001b
CHIP_I2C_PINS: 0x00000003
IOC is READY
# lsirec 0000:05:00.0 rescan
Device in MPT mode
Removing PCI device...
Rescanning PCI bus...
PCI bus rescan complete.

Verify new id (H200I):

# lspci -Dmmnn | grep LSI
0000:05:00.0 "Serial Attached SCSI controller [0107]" "LSI Logic / Symbios Logic [1000]" "SAS2008 PCI-Express Fusion-MPT SAS-2 [Falcon] [0072]" -r03 "Dell [1028]" "PERC H200 Integrated [1f1e]"

You can now move the card to the dedicated slot 🙂

Thanks to ArtOfServer for a great video.